We can't find the internet
Attempting to reconnect
Something went wrong!
Hang in there while we get back on track


Big Ideas
AI adoption is becoming an operating-model problem, not a software-procurement problem. Sachin Rekhi reports a widening gap: average teams are seeing a 20–30% increase in engineering velocity, while the strongest teams are seeing 2–3×. His four-step playbook is to build a shared Compounding OS, set an AI-fluency floor, redesign the product process so agents work alongside product, design, and engineering, and use behavior-change principles rather than training and mandates alone. The useful leadership audit is whether the team’s system, skills, workflow, and habits are changing—not merely whether people have access to AI tools.
“AI PM” is not one job. Jonathan Evens separates modeling PMs, who define model behavior, capabilities, and acceptable error rates, from AI feature/product PMs, who apply AI to a domain workflow and design the surrounding experience—the last 20% that makes a general model work for a use case. Using AI to improve a PM’s own knowledge work is simply PM productivity, not a separate role. For AI features, establish product principles and existing north-star outcomes first, then add side-by-side output comparisons and behavioral signals to the evaluation system.
Measure successful work, not hours saved. A controlled study compared 108 people using agents with 110 doing the same context-heavy tasks without them. Task success rose from 59% to 93% while completion time fell 38%, or roughly 2.5× more successful outcomes per unit of time; the report cautions that it does not yet show how those gains translate into business outcomes.
Tactical Playbook
Debug AI quality at the source. Teresa Torres describes a customer finding a flat branch in an AI-generated opportunity tree; the team spent three weeks building four evaluation metrics and testing 16 variations rather than applying a quick prompt fix. The operating rule is to combine evals, guardrails, and orchestration; calibrate judges against production data; trace upstream fixes for downstream regressions; and consider an agent that audits its own work. A practitioner’s more operational checklist includes cost per token, latency, payload size, structured-output errors, first-pass rate, real-user failures marked mandatory to detect, and broad regression runs—while remembering that a better eval score can still produce worse UX if it makes the product materially slower.
Case Studies & Lessons
Lightfield used customer pull to escape a successful but unsatisfying product. Its presentation product reached about 2 million users per month, but the founders stopped it because they could not see discerning professionals finding it indispensable; they also judged that missing context about the presenter, audience, and relationship—not general reasoning—was the core limitation. They found 12 B2B pilots among sales and marketing users, followed requests from decks into research, lead qualification, and account expansion, then discovered that conflicting CRM, call-recorder, and warehouse data was the deeper problem. A first go-to-market assistant had daily users but no pricing power because it did not own the underlying data; after restarting around a CRM, 10 startups used the rough product daily and sent feedback roughly every two hours. The lesson is to distinguish reach and usage from indispensability, pricing power, and ownership of the workflow’s core data.
Hinge demonstrates an outcome-led consumer strategy. Its North Star is great dates and getting people off the platform, not maximizing engagement; fewer than 15% of users pay, and monetization is reserved for constraints or accelerators while the free experience remains “sacred.” Hinge segments daters, identifies their problems, forms hypotheses, and does not ship a change unless it increases the chance of two people meeting in real life.
Career Corner
For senior interviews with founders or executives, use the final five minutes to ask questions that expose the real role: What will you continue owning after hiring the head of product? What is the one superpower you want this person to have? What are the one or two things that truly matter enough to require an 11/10? The framework is aimed at senior roles; it is not designed for a PM3 reporting to a GPM.
Tools & Resources
All Things PM is a current community-built resource derived from 604 PM job postings across 95 companies and 137 career boards, with an updating AI-PM curriculum, a 205-concept knowledge graph, and interview/resume tools. Treat it as a map of hiring language rather than a definition of the job: its creator acknowledges that postings can miss stakeholder management, judgment, and politics, and a commenter argues that JDs often diverge from actual workflows.

- Treat product assumptions as revisable models. Nir Eyal defines beliefs as convictions open to revision based on evidence and as tools rather than truths. For a team stuck on a customer, problem, or stakeholder interpretation, his inquiry method is to identify where the difficulty is, state the assumed cause, ask whether it is true and absolutely true, examine the effect of holding the belief, imagine operating without it, and generate alternative interpretations. The goal is a portfolio of perspectives rather than a forced replacement belief, giving the team more freedom to choose a useful response.
- Design sustained motivation around behavior, benefit, and belief. Eyal argues that persistence is critical to reaching goals and that long-term motivation requires knowing what to do, why it matters or what benefit it provides, and believing in one’s ability or in the leadership behind the effort. For product adoption and internal execution, make all three explicit instead of relying on incentives or information alone.
- Treat expectation-setting as part of the product experience, but validate behavioral outcomes. Eyal describes identical wine being judged differently when framed as expensive versus cheap, and golfers performing better when told a putter was used by a famous golfer. He attributes the improvement to behavior changes such as greater relaxation and focus—not to positive thinking or “manifesting” alone. Product teams should therefore test how pricing, positioning, and launch framing affect perceived value and usage, while separating expectation effects from actual product capability.

- For B2B SaaS, repeated use of the same core workflow is a stronger intent signal than login frequency; one practitioner cites using that workflow three times in a week, while daily logins may reflect curiosity. Repeated feature depth, organic usage-limit hits, and teammate invitations that lead to actual teammate activity are also prioritized signals.
- A lightweight operating model is to score users from 0–3 on these signals and manually review users scoring 2+ instead of building a full lead-scoring model. Interpret limit events in trial context: reaching a cap on day 2 of a 14-day trial may indicate faster workflow adoption than reaching it on day 13.
- In a small beta, combine behavioral signals with direct conversations rather than relying only on product data. For short B2C trials, onboarding completion may be the only practical intent signal; one three-day-trial example improved trial starts from about 2.5% to 5% and weekly MRR from $60 to $300 by showing the paywall after onboarding and removing the “continue for free” option.

Use case: In interviews for senior product leadership roles with founders or senior executives, use the limited end-of-interview question period to ask sharper questions; this framework is not intended for a PM3 reporting to a GPM and is less applicable when the interviewer is a GPM at a FAANG company.
- Ownership: Ask, “What aspects of the product makes sense for you to continue owning after you hire the head of product?” This probes founder or executive ownership boundaries, which can reveal a source of future conflict, and signals that the candidate is optimizing for the company rather than personal ownership.
- Role-defining strength: Ask, “What is the one superpower you want this person to have?” instead of asking for an ideal-candidate profile; the sharper prompt is intended to make the interviewer think and provide more useful information for the next conversation.
- Highest bar: Ask, “What are the one or two things that truly matter that this person needs to score an 11 out of 10 on?” rather than the generic “what does success look like?” question.

- Outcome-based North Star: Hinge measures success through great dates and getting users off the platform rather than maximizing engagement; it does not ship work unless it believes the change increases the chance that two people meet in real life. A transferable implementation pattern is to define the customer outcome beyond the product, research the problems blocking it, form hypotheses, and filter prioritization through that outcome.
- Segment-led discovery and constraint-based monetization: Hinge’s culture and consumer-insights team studies different dater situations, identifies their problems, and develops hypotheses before selecting solutions. Its free experience is intended to let everyone succeed; it monetizes features that break constraints or accelerate success, especially where scarcity would lose its value if offered universally, while fewer than 15% of users pay.
- Strategy-driven product organization: Hinge treats org structure as a reflection of the company’s problem and strategy, reviewing the organization annually as strategy is updated. It deliberately brings engineering, AI, data, product, design, and research leaders into prioritization debates; a lack of disagreement over product-versus-technology investment is treated as a warning sign, while infrastructure preparation must be balanced against user-facing improvements.
- AI as a product-learning accelerator: Hinge’s biggest current AI benefit is a faster feedback loop: PMs can prototype near-final experiences connected to APIs and back-end systems, put them in users’ hands, create visualizations instead of relying on long feature specifications, expand user research, and begin translating native iOS work to Android.
- Guardrails for AI-assisted building: Hinge lets PMs and designers use AI for prototypes, faster learning, and communicating ideas, but engineers still own production code, architecture, and quality because scalability and maintainability have not yet been proven for non-engineer-built systems. Ben’s forecast is that broader non-engineer production work requires highly complete product specifications, reusable design systems, and documented edge cases; he estimates this is at least about two years away and prefers not to trade quality for speed prematurely.
- Trust and safety as core product investment: Trust and safety sits under Hinge’s Chief Product and Technology Officer and is described as roughly a third of the organization; the company uses AI, including traditional machine-learning models, to identify fake users and bad actors.

- Distinguish AI PM roles: A modeling PM defines what the model should do, how core capabilities such as factuality, long-context handling, and reasoning are measured, and which error rates are acceptable; in frontier labs, these responsibilities may be split across capability-specific PMs. An AI feature/product PM treats AI as a capability in service of a product, relying on deep domain and workflow expertise and designing the surrounding experience—the last mile that adapts a general model to a specific use case. Merely using an LLM for knowledge-work productivity does not constitute a separate AI-PM role, although rapid prototyping, vibe coding, and AI-assisted data analysis are useful PM skills.
- Use a two-layer measurement system: Keep established north-star measures such as retention, fulfilled user needs, satisfaction, information quality, and trust, but add AI-specific proxy metrics including continuous side-by-side win rates against a prior model, competitor, or internal baseline. Supplement those evaluations with behavioral signals—copying answers, following recommendations, clicking links, giving feedback, or consuming generated media to completion—to inform reinforcement-learning and human-feedback loops. Define product principles and the intended experience before building evaluations, then translate those principles into measurable tests that can teach or improve the model.
- Make trust an explicit product-design requirement: For AI features added to trusted products, set an acceptable error rate for the intended release scale, launch first with power users where appropriate, and study real failure cases such as conflicting source information. Improve user trust through factuality and grounding in trusted sources, clearly placed citations, visual cues that distinguish higher- from lower-confidence information, and redirection or qualification when questions are politically sensitive or genuinely ambiguous.
- Use synthetic users selectively: Synthetic users are especially useful for cold-start products or features, privacy-constrained research, automated regression testing, and checking edge cases after a change. They can accelerate iteration when the PM performs initial human QA and the team then validates with trusted testers before broader real-user exposure.
- Match team shape to problem complexity: A senior developer may take some AI problems a long way alone, but complex or unsolved products also require product principles, AI research, and repeated iteration; AI work is likely to involve more prototyping and greater overlap between engineering and product roles. Engineers can own technical quality checks, while PMs apply product sense to define principles and prioritize the capabilities and use cases that matter to customers. The practical starting point for an AI feature PM is a deep user problem or pain point—not a gimmick—followed by friction reduction and principles such as purpose over possibility and human accountability over full automation.

- Pivot and discovery: Lightfield’s team stopped its presentation product despite reaching about 2 million users per month because the founders did not like the product and could not see a path to making it indispensable for discerning professional users. They rejected simply waiting for better models because the core gap was missing context about the presenter, audience, and relationship—not general reasoning ability. They then identified sales and marketing users in their existing base, ran 12 free pilots, and followed customer requests from presentation decks into research, lead qualification, and account expansion. Connecting CRM, call-recording, and warehouse data exposed incomplete and conflicting records, leading them to reframe the problem as organizing business reality for humans and machines. An early go-to-market assistant had daily users but no pricing power because it did not own the underlying data and faced ten competitors; after restarting around a CRM, ten startups used the barely finished product daily and sent feedback roughly every two hours. The founder’s pivot heuristic was to find real pain, build a product that solves it, focus obsessively on customers, and ignore surrounding noise.
- Product design principles: Lightfield made a chronological activity log—the full history of interactions, documents, product usage, and payments—the canonical primitive from which conventional CRM fields and stages are updated. Because a fully unstructured approach made queries too slow, the team adopted a semi-structured model that stores large amounts of unstructured activity data while using it to infer causality. To avoid locking customers into a flawed initial data model, it used schemaless onboarding: connect email and other systems, assemble relationships automatically, and fill or revise fields later. For enterprise adoption, the team kept dashboards and table views while also supporting natural-language workflows; sales sequences that once required explicit conditions could instead be generated as agent-written recipes.
- Monetization and execution: Lightfield tested seat pricing, where the heaviest user consumed about 10,000 times more than the lightest, then pure consumption pricing, which led signups to avoid using the product. It settled on a platform fee plus seats for core CRM work and consumption pricing for pipeline generation, workflow automation, intelligence, and forecasting. It avoided outcome-based pricing because sales outcomes depend heavily on each customer’s product-market fit, so it charges for the work performed. Internally, a 40-person team removed fixed swim lanes: everyone joined the same daily standup, ranked cross-functional problems, and whoever was available took the next problem; planning was continuous, with a low bar to start projects but a high bar to ship them, reinforced by company-wide bug bashes. For prioritization, the team evaluates an account’s expansion potential over a three-year horizon and leans toward building for the fastest-growing customers rather than the average customer.

- A customer identified a flat, unstructured branch in an AI-generated opportunity solution tree; the team spent three weeks tracing the issue to its source instead of applying a quick fix, creating four new AI evaluation metrics and testing 16 experiment variations.
- Reliable AI product quality requires evals, guardrails, and orchestration—not prompt engineering alone. Judges need calibration against production data, upstream fixes can worsen downstream errors, and a self-auditing agent may be preferable to endless prompt tuning.
- Opportunity solution trees are only useful when their details are accurate enough to show teams exactly what to work on next.

- Evaluate AI agents on recurring work, not one-off outputs. For cross-system workflows, test whether an agent can identify meaningful changes, carry context between systems, reopen the loop later, and return when a human decision is required—not merely generate another draft.
- Use the second run as the core product test. A useful agent should preserve prior state, avoid duplicate work and repeated alerts, recognize when nothing meaningful changed, and make yesterday’s work reduce today’s effort. A practical quality bar is: “Would I give the Bot the same job again next week?”
- Design around jobs and continuity rather than organizational categories or isolated artifacts. Agents are most valuable when they remove coordination work—remembering to check systems, transferring context, and rebuilding briefs—while stopping at explicit human-approval boundaries.
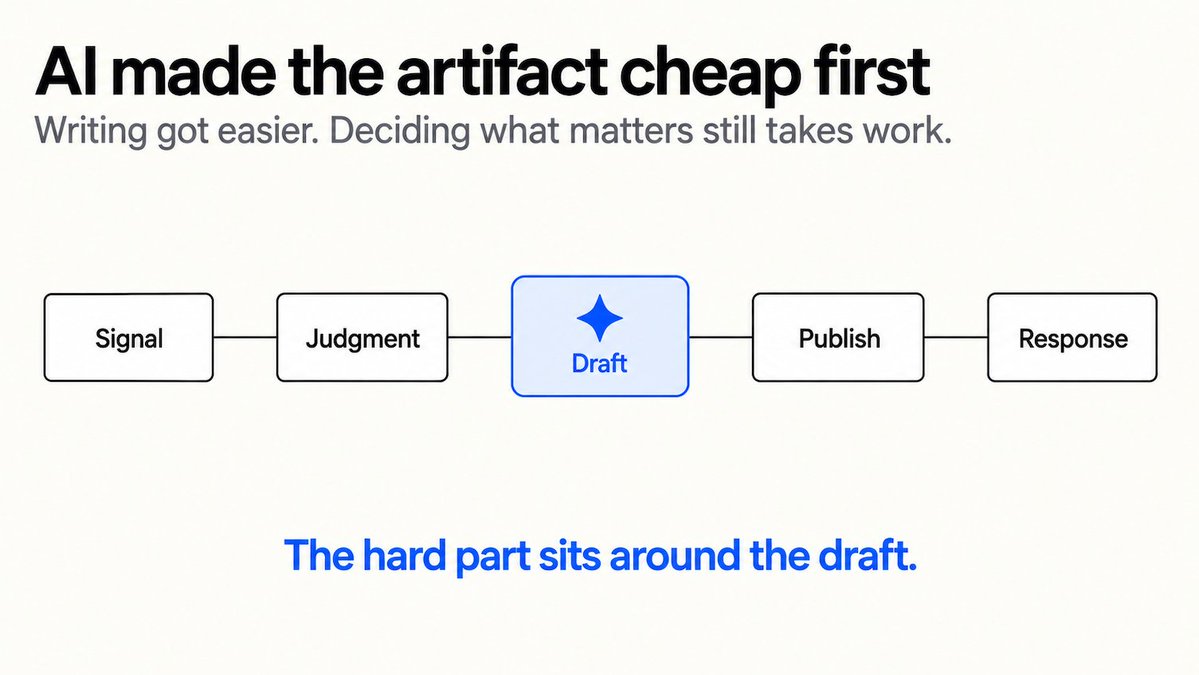
- Evaluate AI agents as durable handoffs, not first-run demos. Model the job as a loop: notice a signal, decide whether it matters, make a change, observe the result, and retain what was learned rather than stopping at a single artifact. Test the second run for retained context and baselines, suppressed duplicate work, and the ability to stay quiet when nothing meaningful changed. Use “Would I give the Bot the same job again next week?” as the quality bar; success means responsibility has moved out of the user’s head.
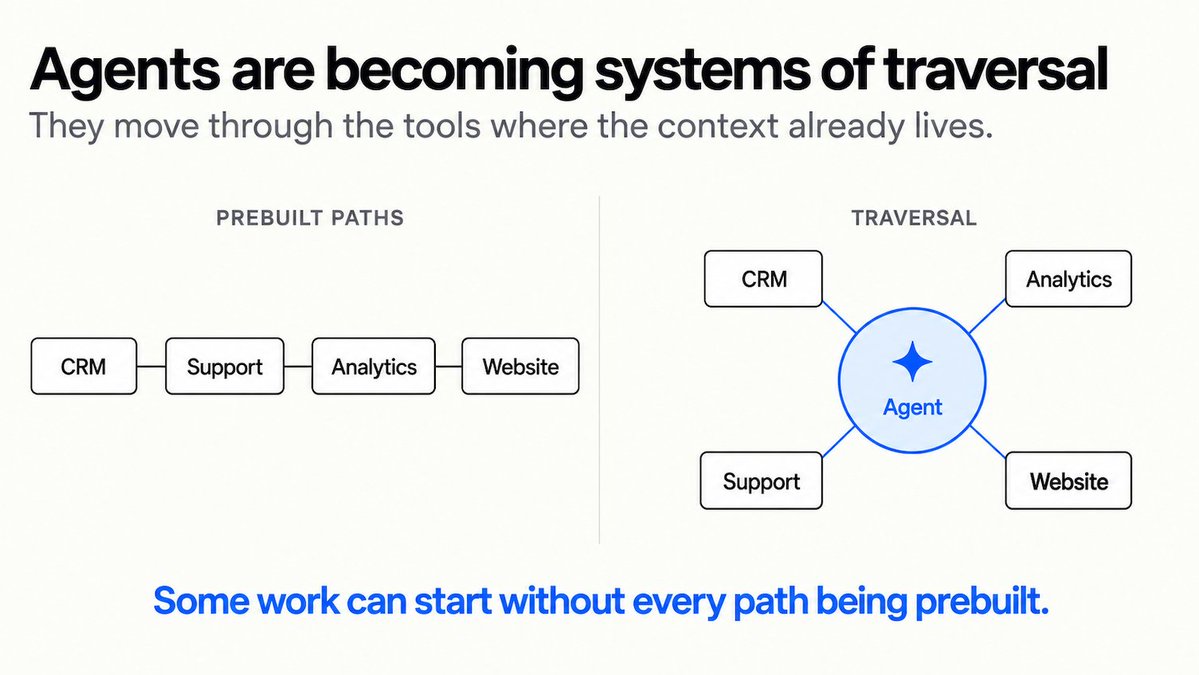
- Design for cross-system traversal with explicit autonomy boundaries. In fragmented workflows, an agent can move across systems of record while carrying working context instead of relying only on predetermined system-to-system paths; this requires clean data, reliable systems, and stable access. Let the agent proceed through routine steps but stop for human approval before consequential actions such as changing budgets, sending messages, or publishing pages.
- Use repeatability and failure modes as product acceptance criteria. Shah cataloged more than 900 public Grok Bots and is testing which jobs merit continued handoff; failure signals include weak sources, lost state, repeated alerts, constant corrections, and broken logins.
- For evaluating AI-agent productivity, measure successful work per hour, not hours saved alone: task success increased from 59% to 93% while completion time fell 38%, yielding roughly 2.5× more successful outcomes per unit of time.
- A controlled study compared 108 people using agents with 110 completing the same context-heavy knowledge-work tasks without them; agent users completed more work faster and had higher confidence in their work. The report cautions that it does not yet show how reclaimed time or quality improvements translate into business outcomes, so PMs should pair productivity metrics with downstream ROI measures.
- Evaluate AI agents as ongoing jobs, not one-off demos. Test whether the agent preserves state on the second run, avoids duplicate work and false alarms, stays quiet when nothing meaningful changed, and knows when to stop for human approval at consequential steps. The practical quality bar is: “Would I give the Bot the same job again next week?”
- Prioritize loop continuity over artifact generation. A useful agent should reopen the relevant source with prior context, determine whether anything materially changed, carry context across systems, and return when a person needs to decide; the value is reducing the need to remember checks, transfer context, and rebuild briefs—not maximizing autonomy.

- AI-driven technological change is creating career uncertainty for tech workers, including questions about whether product management remains a viable long-term career and whether starting a company is the only path forward.
- Shreyas Doshi frames career decision-making around alignment with one’s authentic identity and life goals, explicitly aiming to help people avoid FOMO, envy, and career anxiety.

- Lenny Rachitsky reports that stage fright affected his talks, large meetings, and time in the spotlight, though it has improved in recent years.
- His practical approaches are low-stakes public-speaking practice through Ultraspeaking, considering beta-blockers only after personal research and consultation with a doctor, and repeating reframing mantras such as “Look what I get to do,” “Don’t perform. Be yourself,” and “Find the joy in it.”
- Tobi Lutke recommends deliberate belief rehearsal: he wrote “I like public speaking” for 10 minutes daily for a week while afraid of speaking, and says he now loves it; he adds that writing something about yourself 100 times can help the brain reconcile with that belief.
- Claude is merging Cowork and chat into a single Claude experience: users can ask quick questions or hand off reports, while Claude continues working after the laptop is closed, asks for clarification when needed, and preserves the user’s final say.
- The unified experience is rolling out to Pro and Max subscribers over the following few weeks.
- Instrumentation and metrics: The workflow uses PostHog for analytics and traces and Homeric for skills management and analytics. Beyond usage, it tracks cost per token, generation time, input/output payload sizes, structured-output errors, and— for coding agents—first-pass rate: how often a change passes reviews/tests and is deployable on the first iteration.
- User-grounded evals: Real user failures are added to the evaluation dataset, with some cases marked “mandatory to detect.” Those cases are run repeatedly, and the eval must return a failure in 100% of them.
- Model-change regression testing: New models trigger a broad eval rerun—described as 100 repetitions across 100 use cases rather than a single run over 10 cases—followed by dashboard review. Eval results can remain difficult to interpret, and better eval performance may not improve perceived UX if it causes a significant speed reduction.
- Prompt and skill validation: More detailed workflow steps have sometimes reduced consistency and eval scores, while reordering modular skill components materially changed generative quality; evals were used to detect these counterintuitive regressions.

Casey Winters describes an unexpected long-tail consequence of growth work at a large consumer company: when the company changes its privacy policy ten years later, “they will personally email you a thousand times.”
- AI monitoring products should distinguish meaningful movement from routine updates and interrupt users only when the change matters; otherwise, users still have to perform the filtering the AI was meant to handle.
Grok Bot testing highlights two product requirements for delegated AI workflows: bots should resume jobs autonomously with context intact, and their outputs should be usable without requiring users to inspect how the work was done. A Friday 10 AM PT demonstration will show marketing tasks the author would hand off to Grok Bot.

- A mid-sized B2B SaaS product-discovery team’s AI interview tool contaminated live customer insights with snarky placeholder labels from its testing dataset, including claims that customers found the feature “useless” or pricing a “cash grab.”
- The tool’s automated highlight reel removed hedging and stitched together dramatic fragments, making nuanced “this is fine but” trade-offs sound like broad customer anger. The incident exposed the need to treat AI-generated research summaries as drafts: verify training/test-data separation, inspect raw context, and sanity-check outputs before executive or customer readouts.
- AI coding agents are shifting the PM bottleneck from implementation to alignment: one PM reports that carefully crafted requirements and technical alignment now lag developers using Claude agents, while parallel iterations and refactors create ongoing work-allocation and coordination chaos.
- AI-assisted specifications, research, prototypes, and slides produced “pretty decent” results but remained insufficient for discovery and alignment; the PM also tried supplying more business context so developers could generate ideas independently.
- AI acceleration can weaken release controls: a commenter reports that code bypassed QA and reached production because AI “cleared it,” with bugs then discovered in production rather than before release.