We can't find the internet
Attempting to reconnect
Something went wrong!
Hang in there while we get back on track


Huang is out at Nvidia, and export-control politics move fast
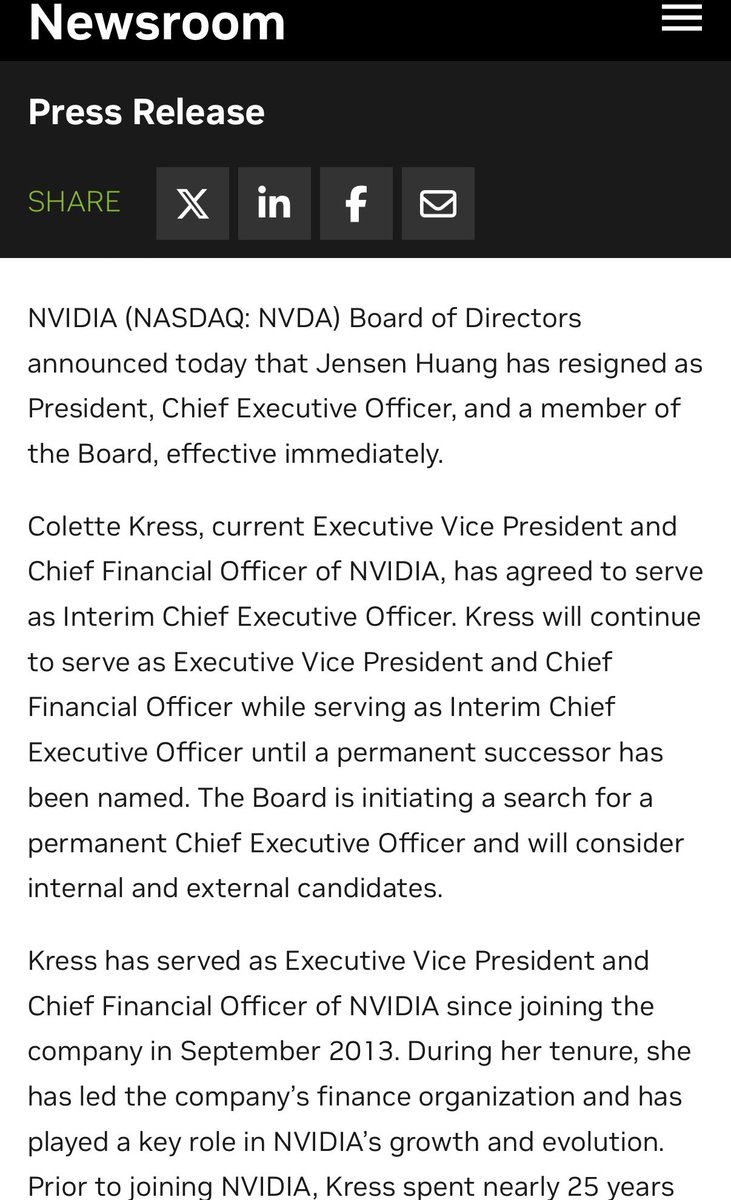
Jensen Huang has resigned as Nvidia's President, CEO and board member, effective immediately . CFO Colette Kress takes over as interim CEO . Bloomberg, as relayed in a post, reports that the board met late into the night and left him no choice but to resign . The NYT reports he has hired the law firm Paul Weiss . According to WIRED, an internal post asking the board to weigh employee sentiment drew more than 1,600 comments, most of them backing his return . CNN sources say US intelligence on the Chinese businesswoman linked to Huang does not so far prove she was spying for Beijing .
The policy effects matter more than the personnel change. Shakeel Hashim points out that Nvidia was leading the lobbying against the NDAA export-control measures, and argues that its disarray and lost credibility mean it can no longer do so . Andrew Curran reports that OpenAI is joining Anthropic in backing bipartisan chip export controls, with the aim of passing legislation before year-end . Separately, The Information reports that Litong Inc, a group of companies tied to Alice Huang, has imported 240,000 Nvidia chips worth at least $7.5B into China since 2023 despite export controls. It says the group also invested in DeepSeek, which is still trying to get more Blackwell chips .
Commerce is also reportedly weighing a rule on China's access to AI chips in overseas data centers. One analysis says the rule as described has three gaps:
- it covers only certain countries;
- it applies only to future exports, so existing data centers are untouched;
- it only covers chips at least as powerful as Blackwell, so H200-class chips stay available.
The analysis puts the effect at no more than 14% of China's end-2027 compute, and calls that "almost certainly a strong ceiling" .
Contested forensics: were Chinese frontier models built on Blackwell?
Will Depue says checkpoint forensics on released weights shows that DeepSeek, Moonshot, MiniMax and Ant Group built their newest models on Blackwell chips, which are barred from export to China . His method relies on a claim that each GPU-and-seed combination leaves an initialization pattern that survives training . He searched more than six trillion combinations and says six Chinese models, including DeepSeek-V4-Pro, Kimi K3 and MiniMax-M3, match Blackwell. Four of them match GB200/GB300 parts specifically .
His evidence and estimates:
- Reproduction tests: a B300 reproduced DeepSeek-V4-Flash's starting weights bit for bit, and a GB200 reproduced Kimi K3's to 0.999995 correlation. An H100 did not reproduce the DeepSeek weights .
- Cluster size: he estimates Kimi K3 and DeepSeek-V4-Pro each used 2,000–3,000 Blackwell GPUs, at roughly $150–200M per cluster .
- Outside checks: he says senior OpenAI and Anthropic researchers independently verified the results .
- Location: he concedes the method cannot show where the chips physically are .
The pushback came quickly:
- Initialization isn't training. Dfranke argues that initialization is computationally trivial and could be done on separate hardware, so it says nothing about where a model was trained . Depue answers that the fingerprint matched publicly disclosed hardware in all 24 known cases. He adds that Kimi K3's weights were created by at least 64 processes, all on Grace Blackwell .
- No match for DeepSeek's latest model. Depue acknowledges that DeepSeek-V4.1-Flash produced no match. He says this means DeepSeek changed how it creates starting weights, which reveals nothing about the chip either way . Late in the period he posted that it "might be NVIDIA," without further detail .
- The scale is small. Teortaxes notes that against roughly 24 GW of installed Chinese compute, even five labs with 10 MW each come to 0.2%. He calls that a success for export controls, not a failure .
Depue has released his code . Treat the hardware attribution as plausible but unconfirmed. It is already shaping the policy debate.
Gemini 4 Hydrogen: Google's fast tier, with independent caveats
Google launched Gemini 4 Hydrogen as the execution model alongside Carbon and Argon. It is available across AI Studio, the API, the Gemini app, Search and Antigravity . Pricing is a flat $1.50/$7.50 per 1M tokens across a 1M-token context window. Google says it scores 51 on the Artificial Analysis Intelligence Index at high reasoning, 54 at xhigh, against Argon's 50 . In Antigravity, a new Orchestrator switches between Carbon and Hydrogen within a session. Google reports near-Carbon success on Terminal-Bench 4.0 while using 24% less quota .
Independent evaluations:
- Artificial Analysis: puts it 1 point behind Claude Sonnet 5.5 and GPT-6.1 Sol at about 32% of Sonnet's cost but about 2.5× Sol's . It has an 8% hallucination rate and is weaker on terminal-based agentic work (54% on Terminal-Bench 4.0) .
- Vals: #6 on its index, 2.0 points behind Carbon at 38% of Carbon's list price .
- Agent Arena: #5, and the fastest model in its top 10 at a median 5.3 minutes per task. Arena notes it spends 41% more output tokens per task than Carbon .
Developers raised complaints too:
- Pricing: Simon Willison finds the pricing confusing. Hydrogen is only a 25% discount on Carbon and Argon, though those two double in price on Dec 1 .
- Budget exhaustion: at xhigh, one tester saw Hydrogen spend 131K thinking tokens on reading a jersey number and return no answer. The same budget exhaustion hit 1.8% of their text benchmark .
Inkling 2 Small goes open-weight
Thinking Machines released Inkling 2 Small under Apache 2.0 . It is a mixture-of-experts model with 594B total and 17B active parameters, takes text and images as input, and supports up to 1M tokens of context. vLLM says it fits on a single GB200/GB300 node . Arena ranks it the #1 US open model in Agent Arena and #2 among all open models. Its median cost is $0.26 per task, about 4.7× less than Kimi K3.1 Pro .
Other notable items
- OpenAI cyber: OpenAI launched two security products, Daybreak Defense Factory and Daybreak Red Team . A slide from the livestream reportedly shows an unreleased OpenAI model at 77% on an unnamed cyber metric, against about 30–50% for Opus 5.5, Mythos 5.2 and Carbon .
- Anthropic: Self-hosted Claude Managed Agents is now in private beta . Claude Meetings, which builds documents and other artifacts during calls, is rolling out on Team and Enterprise plans . Theo reports the IPO is set for next Wednesday .
- Perplexity Decider v1.3: Perplexity open-sourced the latest versions of its decision models and added a "locate" span-extraction feature . Internally, Decider read 1B tokens across 7,000 agent sessions in one day, which led to 14 fixes to Perplexity's agent security rules .
- Rubin inference: vLLM reports DeepSeek-V4.1-Flash on Vera Rubin NVL72 at 2.52M tokens/s/GPU peak, 2.7× GB300 .
- OWE-Bench: Mercor's new benchmark of 26 long-horizon engineering projects is led by Fable 5.2 at 54.6%, ahead of GPT-6 Astra at 44.2% .
- Speech: Salesforce's SOV-Transcribe-1 is now the top open-weights speech-to-text model on Artificial Analysis, with 2.3% WER .

- Anthropic introduced Claude Fable 5.2 and Claude Mythos 5.2, reporting improvements in coding, reasoning, and vision; ThursdAI said Fable ranked #1 on Artificial Analysis and was 20% cheaper.
- Gemini 4 Carbon became available in the Gemini API and to Ultra subscribers; ThursdAI reported 60.4% on CursorBench, $2/$10 per 1M tokens through Nov 30, and up to 1M output tokens. Google introduced Gemini 4 Hydrogen for everyday coding and agentic work, claiming four thinking levels and 2.5× the speed of Gemini 3.8 Flash.
- Google’s Gemini Decision 1 is a decision model that returns probabilities for yes/no, multiple-choice, or scoring queries, handling up to 1,000 questions per call; it supports image, audio, video, and PDF inputs, a 256K context window, and is listed at $0.10 per million input tokens with no additional cost.
- Cloudflare’s Michelle Chen described four models released in three weeks, including Apache 2.0 Clef decision models and Clairic, an extraction model that returns confidence scores.
- Nous Research introduced Arete-27B, a Qwen3.8-27B post-trained toward Western values. On Nous’s 803-prompt, seven-category evaluation, it reported reducing the model’s propaganda rate from 22% to 1% after roughly 53 million training tokens, with no significant Hermes Bench performance tradeoff; the evaluation, weights, and training data were made available. ThursdAI identifies the release as Apache 2.0.
- Anthropic launched the roadshow for its proposed IPO; ThursdAI reported an offering of 825 million Class A shares at $70–$78 under ticker ANT. Anthropic’s post says the registration statement had been filed but was not yet effective, and that securities could not be sold or offers accepted before it became effective.
- NVIDIA announced a CEO transition. ThursdAI says Jensen Huang resigned and left the board, with CFO Colette Kress as interim CEO, but the quoted NVIDIA post confirms only that a CEO transition was announced.
- CoreWeave announced a multi-year agreement for Wayve to train its AI Driver foundation models on CoreWeave Cloud; Wayve plans to evaluate models there and put them on the road only when they beat the current model. A ThursdAI segment also reported CoreWeave Q3 revenue of $3.66B, up 168%, and qualified demand at 10 times available capacity through the end of 2027.
- @jachiam0 warns that a crackdown on chip exports that excludes China from AI’s upside near RSI/ASI could heighten pressure for near-term hot conflict . The responding account says hawks infer U.S. escalation dominance from China’s failure to initiate prior exchanges , and lists Taiwan action, reverse-engineering ASML DUV scanners, critical-material embargoes, compute centralization, and stealing Mythos as possible responses to U.S. escalation—not as events that have occurred .
- In a follow-up, @teortaxesTex says the AI 2027 team’s “DeepCent” idea is “coming together,” citing Tencent as DeepSeek’s biggest single backer and saying newly produced compute is being somewhat centralized; the author says this was not intuitive in April 2025 .
The Wall Street Journal says an unnamed woman whom Jensen Huang called “a deer in the headlights” at a meeting three months earlier is now replacing him; the post does not say what role is changing or identify her.
A post asserts that DeepSeek V4.1F is served on Blackwell GPUs and speculates that Blackwells were also likely used for RL; the author says they are agnostic about the V4 training setup. In a reply, the same account argues there is no evidence DeepSeek has trained on non-NVIDIA hardware, framing that as a rebuttal to claims that it avoids NVIDIA.
An X commentator claims Jensen Huang was abruptly “booted” from Nvidia, the company he built . The thread links the claimed exit to allegations of an affair with a direct report and disputed insinuations that the woman was a Chinese spy . The supplied posts assert these claims but do not independently substantiate them, so treat the reported exit as unverified rather than confirmed Nvidia news .
A WIRED post reports that an internal post urging the board to consider employee sentiment about Nvidia’s former CEO drew more than 1,600 comments, most in full support of reinstalling him; this reports employee support, not a confirmed reinstatement.
Will Depue says checkpoint fingerprints matched the publicly disclosed training hardware for 24 models and that Kimi K3’s weights were initialized by at least 64 processes on Grace Blackwell, which he interprets as evidence the training job started on a Blackwell rack. He says CPU-initialized cases reflect a software default—initializing weights on CPUs before copying them to GPUs—while critic Dfranke argues initialization can be performed cheaply apart from training and therefore does not establish the hardware that trained a model or the political significance of the inference. Dfranke requested code and data for review; Depue said he was working on it, and a later reply linked the macrogrants/checkpoint-forensics GitHub repository.
Looping a transformer is reported to improve no-CoT capabilities more than other ways of increasing pretraining quality.
A Zhihu contributor argues NVIDIA’s GPU moat extends beyond CUDA or the ability to run the same code: it combines specialized hardware for common operations with APIs and libraries that let developers use it. The post cites Tensor Cores for matrix operations and says texture hardware can perform trilinear interpolation several times faster than a handwritten GPU implementation.
Will Depue reports that his search found one seed/layout for DeepSeek V4-Flash whose weights reproduce bit-for-bit on an NVIDIA B300 at 1,385σ; he says this supports that result, but it does not establish the hardware used for V4.1-Flash. He found no match for V4.1-Flash after searching about 4.3 billion seeds across GPU layouts from 16 to 512 processors and checking PyTorch’s CPU generator; he says the model’s starting-weight generation changed, but that the failure to match cannot determine whether its hardware is NVIDIA or another vendor.
Zachary Lipton characterized John Langford as a major “get” for CoreAuto, calling him a “galaxy-class researcher” and expressing anticipation for what they will accomplish together .
Inkling 2 Small’s width-4 sconv implies inference engines need to maintain a rolling three-token convolution cache per layer alongside the KV cache.
Sakana AI says it is moving into LLM pretraining after work on post-training with Sakana Namazu and orchestration with Sakana Fugu, describing this as an opportune moment to work at the model layer; it plans to begin pretraining Sawara Small (tentative name) in December.
Anthropic introduced Claude Meetings, which joins team video calls and builds documents, whiteboards, and other artifacts during the conversation; beta rollout is starting for Team and Enterprise plans.
- Sakana AI cofounder and CEO David Ha argues that the economics of scaling a single giant model are weakening: open-model performance gaps have narrowed to months, and frontier-model inference can cost more than the hourly labor it is meant to assist. He sees competition shifting toward reinforcement-learning-based orchestration of diverse models, and defines AI sovereignty as domestic capacity to develop and maintain AI alongside resilient supply chains that combine global resources—not exclusion of foreign technology.
- Sakana AI is developing its first mobile app to let people experience multi-model coordination and was recruiting beta testers through Sunday, Nov. 15.
SemiAnalysis says NVIDIA’s fabless supply-chain advantage includes having scaled one product from $1 billion to $250 billion, but predicts the company will probably lose share, with competitors’ share gains now “extremely possible, and probably probable” . The post also presents AI-assisted chip improvement as a coming direction and says NVIDIA is trying to counter it; the outcome remains uncertain .
Baidu’s ERNIE-5.5-Flash-Preview is usable for common, moderately difficult agent tasks, but tested reliability depended heavily on the technology stack. In one contributor’s tests, ERNIE 5.5 in max mode had a median reasoning score of 28.66, versus 5.49 for ERNIE 5.1; it roughly matched Spark X2.6 (28.58) and trailed GLM-5.3-Flash (41.01), with the comparisons explicitly not representing a full ranking.
In coding tests using Claude Code 2.1.280, output quality and visual presentation were broadly comparable to GLM-5.3-Flash and Step 5. Thorough testing helped on familiar frontend tasks, while unfamiliar stacks sometimes led to rushed delivery and serious bugs; the tester cautioned against 3D modeling, SVG animation, and games, noting that the tested animation task failed.
Further caveats: ERNIE sometimes used fewer tokens than Spark X2.6 on solution-search tasks, but both produced incorrect answers; complex text-processing results were uneven, with only one of multiple attempts earning credit. In single-turn reasoning it also occasionally emitted tool-call-formatted output; the proposed explanation of an imbalance toward long-horizon agent training was unverified.
Perplexity’s Producer teammate generated an animated explainer in Computer about what happens inside a GPU when AI “thinks harder”; its tester called it an impressive starting point for people without a creative or editorial team . Arav Srinivas praised the video and said Producer “basically does the work of a creative team” .
Gemini 4 Hydrogen is pitched as bringing fast, efficient AI to coding and agentic workflows and as an upgrade for Search and the Gemini app; the post gives no benchmark or other measured evidence for these claims. A demo, Lingo City, uses on-the-fly 2D/3D flashcards and interactive 3D city scenes for practicing conversations with local shopkeepers.
Perplexity open-sourced its decision models for agentic security, saying they can analyze billions of tokens of telemetry to find security issues; they were offered free on OpenRouter for a week, and the quoted post says both models were Apache-licensed and free until Nov. 19. Perplexity’s internal Decider run processed 1 billion tokens across 7,000 agent sessions in one day and found flaws that led to 14 fixes to its agent security rules.