We can't find the internet
Attempting to reconnect
Something went wrong!
Hang in there while we get back on track


🔥 TOP SIGNAL
Compare cost per completed change, not token rates alone. Anthropic says Opus 5.5 matches Claude Fable 5.1 for most tasks at 40% lower cost on typical workloads; it is now the medium-effort default in Claude Code and the Claude app for Pro, Max, and Team. OpenAI’s GPT-6 Luna starts at $0.10 per million input tokens and $0.50 per million output tokens.
The strongest coding datapoint is Boris Cherny’s internal HAProxy C-to-Rust test: Opus 5.5 and Fable 5.1 both passed nearly all tests, but Opus 5.5 finished in 9.5 hours versus 12 and cost 51% less. Treat it as a promising first-party result, not an independent bake-off.
⚡ TRY THIS
Sweep effort settings on a real task. Matthew Berman’s read of Anthropic’s FrontierCode comparison says Opus 5.5 at medium effort scored higher than max while costing under $1 versus over $5 per task. Run a representative repo task at both settings and compare test results, elapsed time, and cost before pinning a default.
Give long-running coding work an explicit end state. In Theo’s T3 Code workflow, the prompt supplied a screenshot and thread ID, asked the agent to find root causes, fix them, and file one focused PR. Say whether it should stop at the PR, babysit it until CI is green, or merge once green; Theo’s babysit instructions check only comments and CI newer than the latest push, verify bot findings, and avoid scope creep.
Try an agent-assisted formal-verification pass on risky code. Boris Cherny says a couple of short prompts with Opus 5.5 and Lean produced 16 PRs fixing bugs and race conditions in the Claude Agent SDK; he sometimes combines Lean and TLA+ to probe data flow, concurrency, and state management.
For tool discovery, keep lexical recall broad and rerank candidates with Jev. Treg takes the top 30 lexical matches on any rare query term, asks Jev whether each tool would directly accomplish—or be necessary for—the task, drops scores below 0.4, and prioritizes scores of 0.7 or higher while retaining lexical order and existing success/price adjustments. Its interleaving favored the new pipeline by 8.6:1 points excluding ties—not 9× search accuracy—and the test combines broader retrieval with Jev, so it does not isolate Jev’s contribution. Treg’s write-up.
📡 WHAT SHIPPED
Claude Opus 5.5: Anthropic lists API rates of $4/$20 per million input/output tokens and $0.20 per million cache reads—20% lower input/output prices and 60% cheaper cache reads than Opus 5. It claims 40% lower cost on typical workloads at default settings and over 30% faster output; Anthropic also cautions that benchmark margins are a less reliable guide to real-world differences than before.
GPT-6 Sol and Luna: OpenAI lists Sol at $2/$10 and Luna at $0.10/$0.50 per million input/output tokens. Its DeepSWE 1.1 results report Sol at 68.8% on max effort, within 1.1 points of Claude Fable 5 at xhigh and at about 80% lower task cost; Luna scores 66.6% at max, described as comparable to Opus 5 and Fable 5 at medium effort. These are OpenAI-reported evaluations; validate them in your own harness.
LangChain’s Patch demo turns a Slack feature request into a GitHub PR ready for review. The Managed Deep Agents recipe uses
agent.pyfor the agent/model,instructions.mdfor the repo and procedure, a Slack channel, GitHub MCP with its token in an environment-variable secret, anddefine_sandboxfor coding and tests.Simon Willison’s LLM CLI updates:
llm 0.36addsgpt-6-solandgpt-6-luna, plus a guard for single-turn models;llm-anthropic 0.29adds Opus 5.5 (llm -m claude-opus-5.5 "prompt goes here");llm-typesafe 0.1a0adds Jev support (llm install llm-typesafe).
🎬 GO DEEPER
- Matthew Berman on Opus 5.5’s effort economics: The useful segment compares effort settings and cost per task; watch it before assuming max is the best default.
- Theo on long-running Fable coding work: A firsthand PR workflow—context, root cause, review-bot feedback, and a defined stop condition.
- LangChain’s Patch walkthrough: See the Slack-to-PR agent’s setup, including its instructions file, GitHub access, and sandbox.
- Repo —
llm-typesafe: A quick way to inspect Jev’s typed yes/no, choice, and scoring calls from the LLM CLI; the release includes install and API-key setup.
Editorial take: Cheaper models widen the options; effort tuning, explicit PR completion criteria, and verification determine whether the savings turn into shippable code.
GPT‑6 Sol and Luna are listed as available in the OpenAI API under gpt-6-sol and gpt-6-luna. The launch post gives API prices per 1 million tokens: Sol $2 input / $10 output and Luna $0.10 input / $0.50 output.
- Cached input: The post says cached input-token reads receive a 90% discount. Applying that discount to the listed input rates implies $0.20 per 1 million cached input tokens for Sol and $0.01 for Luna; these effective rates are calculated from the announcement, not separately printed.
- Pricing comparison caveat: The listed GPT‑5.6 promotional rates are Sol $4/$20 and Luna $0.20/$1.20 (input/output). The post labels each GPT‑6 model “50% cheaper,” but Luna’s listed output price, $1.20 to $0.50, does not equal a 50% reduction.
- Coding: The post says GPT‑6 Sol improves substantially over GPT‑5.6 Sol on FrontierCode and matches Claude Fable 5.1 xhigh at much lower cost, without giving a numerical GPT‑5.6-to-GPT‑6 score change. On DeepSWE v1.1, max-effort Sol scores 68.8%, versus Claude Fable 5 at xhigh’s 69.9%, at approximately 80% lower cost per task; max-effort Luna scores 66.6%, described as comparable to Claude Opus 5 and Fable 5 at medium effort.
- Computer use: On OSWorld 2.0 offline, Sol at xhigh scores 60.5% versus Claude Opus 5 at medium effort’s 60.3%, at approximately 80% lower cost per task. Luna at max effort exceeds GPT‑5.6 Sol at medium effort at one tenth of its cost.
- Other GPT‑5.6 comparisons: On the post’s internal factuality evaluation, Sol makes about half as many mistakes as its predecessor; at higher effort, Luna matches GPT‑5.6 Sol at about one hundredth its cost. The post cautions that this evaluation uses conversations where users had flagged factual errors and is not representative of typical usage. Both models also show lower rates of misleading claims about their coding work than their GPT‑5.6 counterparts; the post says these evaluations deliberately test challenging situations and do not measure typical-use failure rates.
- Availability context: The post says Sol and Luna are available in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu users, while Free and Go users can access Luna in the desktop app; the models are not yet available in Chat. ChatGPT rollout is described as gradual.
Direct answer: The supplied announcement claims strong agentic-coding results and lower typical-workload costs, publishes reduced token and cache rates, and describes developer-facing speed, security, and API changes. Its CursorBench table score and prose margin claim do not reconcile.
- Coding benchmarks: The table reports Opus 5.5 at 66.4% on Terminal-Bench 4.0, 54.4% on FrontierCode v1.1, and 57.8% on CursorBench 4.0; it shows higher scores than the listed comparison models on those coding tests. The announcement cautions that benchmark margins may be a less reliable guide to real-world differences and says its own performance gap versus Fable 5.1 is narrower than the scores suggest. Unless otherwise noted, Claude results use adaptive thinking at max effort; Terminal-Bench 4.0 uses Opus 5.5 at xhigh and GPT-6 Astra at high effort. The footnote gives a ±2.6-point standard error for Opus 5.5 on that benchmark and says the public leaderboard uses the Claude Code harness and five trials per task.
- Unreconciled CursorBench claim: The table’s 57.8% for Opus 5.5 and 41.7% for GPT-5.6 Sol imply a 16.1-point difference, whereas the coding narrative says Opus 5.5 beats GPT-5.6 Sol by 11 points; the supplied announcement does not explain the difference.
- Task cost and speed claims: Anthropic says Opus 5.5 needs less compute to serve, costs 40% less than Opus 5 on typical workloads at default settings, and generates output more than 30% faster. It attributes the task-cost reduction to both lower per-token cost and fewer tokens per task. A reported example is a 200,000-line codebase audit and fix completed in under three hours, versus over 20 hours for Opus 5, which used 2.5 times as many tokens; in an internal HAProxy C-to-Rust task, Opus 5.5 finished in 9.5 hours versus Fable 5.1’s 12 hours and cost 51% less. For per-task comparisons, the announcement says Opus 5.5 at default effort beats GPT-6 Astra on FrontierCode for roughly one-fifth the cost, matches Astra on Terminal-Bench for about 40% of the cost, and beats GPT-5.6 Sol on CursorBench by 11 points for about one-third the cost.
- Token pricing per million tokens: Opus 5.5 is listed at $4 input, $20 output, $0.20 cache reads, and $5 cache writes; the corresponding Opus 5 rates are $5, $25, $0.50, and $6.25. Fast mode is available in Claude Code and Claude Platform, offers up to 2.5× speed, and costs $8 per million input tokens and $40 per million output tokens.
- Harness and developer-facing details: The named harness detail is methodological: the Terminal-Bench 4.0 public leaderboard uses the Claude Code harness and five trials per task; Terminal-Bench-Science uses that harness and three trials per task. The announcement does not specify a new harness version or configuration. It describes a classifier that screens each action before execution, an open-source sandbox that security teams can audit, and code review intended to catch vulnerabilities before merge. It also says routine software-development bug-fixing is allowed while most cybersecurity tasks are rerouted to Opus 4.8.
- API/model behavior and availability: Preserved thinking prevents API users from editing Claude’s prior context to extract its reasoning; the announcement says it applies to Opus 5.5 and Fable 5.1 for API accounts created on or after August 31, 2026. Opus 5.5 is also no longer available with thinking switched off. The announcement lists
claude-opus-5-5as the Claude Platform model ID and says the model is available across platforms, including AWS, Google Cloud, and Microsoft Azure.

- For agentic coding comparisons, track total tokens, cost, and tool calls per prompt—not token usage per API request alone: each tool call creates another request, so request-level figures can hide higher end-to-end usage on tool-heavy tasks.
- Theo describes an informal, firsthand repo-audit evaluation: have several models find improvement opportunities in a real codebase, then use Fable 5.1 and Astra as LM judges of suggestion quality. On T3 Code, Astra led, Grok 4.7 was close, and Fable 5.1 made five suggestions versus eight for the other models, with valid suggestions but less verification. Grok 4.7’s run cost ranged from roughly peer-level to twice as much at worst, which Theo attributed to it spending extra effort verifying low-value details.
- Theo found Grok 4.7 more persistent and inquisitive, but its strengths were task-dependent: in a same-prompt, same-environment front-end/game test, he judged its result poor compared with Astra, and reports one run took nearly 90 minutes.
- In a sponsored segment, Theo says his team handles hundreds of PRs a day and now runs 8–30 checks per PR as it adds CI to verify agent work; he argues fast, inexpensive feedback matters at that scale. He describes Blacksmith as replacing GitHub Actions runners with a one-line workflow change, and says demo prompts in its Codesmith tool led him to merge three CI-improvement PRs.

- An Anthropic Claude Code team member recommends Opus 5.5 as a daily driver for general software engineering; they used it for an entire personal-site redo, while reserving Fable 5.1 for discrete planning, code review, and security tasks where the cost of a mistake matters more than cost efficiency. Opus 5.5 was available in Claude Code at launch.
- Compare cost per completed task, not token price alone: Berman relayed Anthropic’s claim that Opus 5.5 costs 40% less than Opus 5 on typical workloads at default settings, despite about a 20% reduction in listed token prices, attributing the difference to fewer tokens needed to finish tasks. In Berman’s Frontier Code comparison, Opus 5.5 at medium effort scored higher for under $1 per task than max effort at over $5; test effort settings on your own workload rather than assuming max is best.
- The Claude Code team has removed much of its system prompt and adjusted tools as models improve. Alongside the release, it introduced plugin evaluations to check whether skills and plugins are current for a new model and help update them so they do not constrain it.
- In an early-access demo, Berman’s teammate Alex asked Opus 5.5 to make a Dark Souls-like game in Unreal; Alex said it worked for about 28 hours without Slash Goal and that he now uses natural-language instructions such as “keep working until it’s perfect.” The reported result included six worlds, NPCs, an upgrade system, and roughly 15 bosses—an example of a long-running side-project workflow, not production evidence.

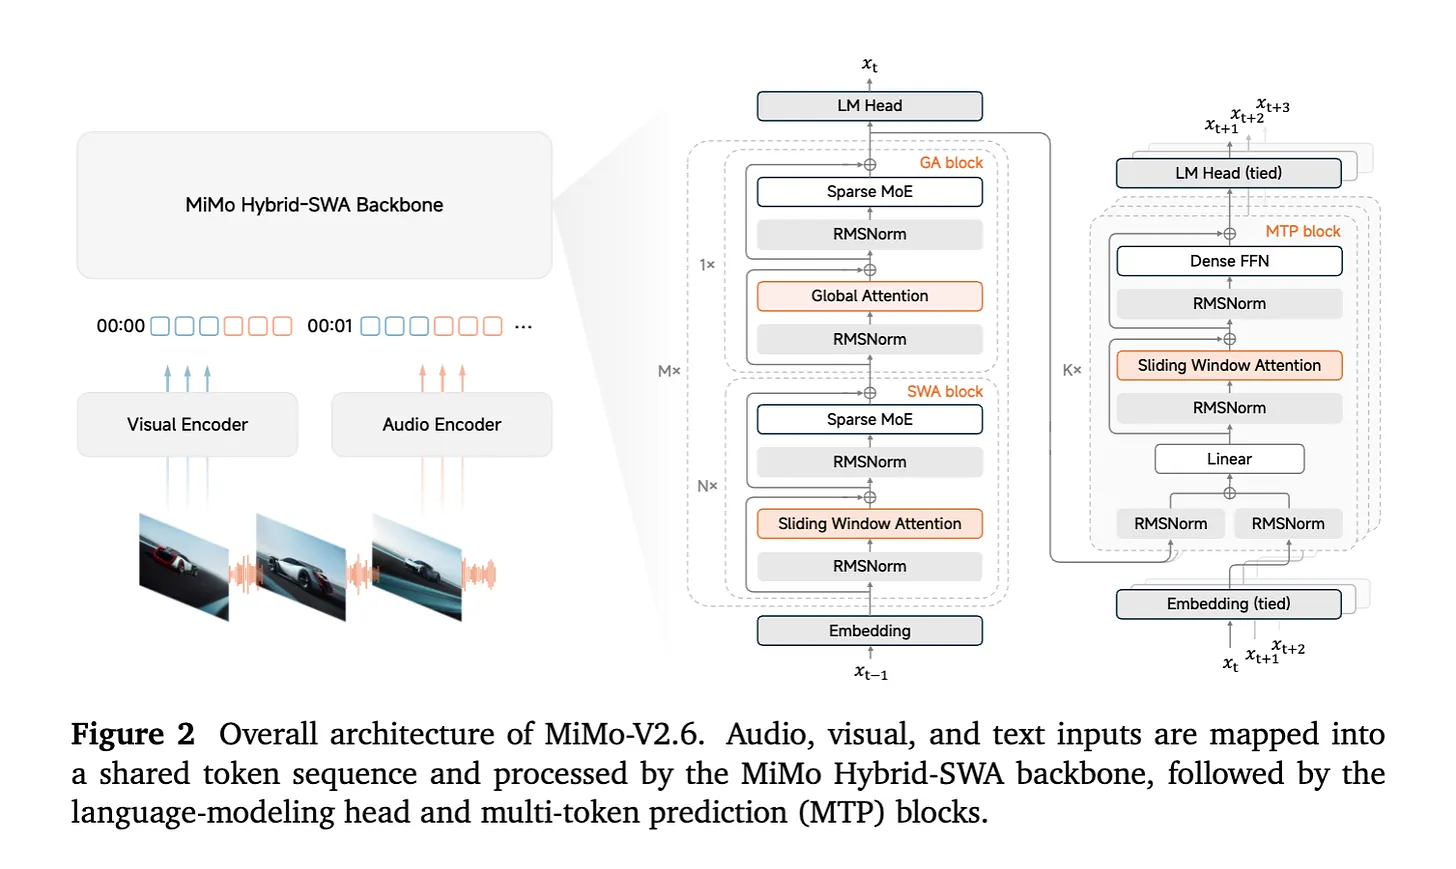
- Latent.Space reports Xiaomi’s open-weight MiMo-V2.6-Pro and Flash release as natively omnimodal; Xiaomi positions Pro as its most capable model and Flash as the efficiency/cost balance, and says Pro-UltraSpeed is rolling out with up to 20× faster output at the same quality. Artificial Analysis reports Pro at 1.02T total/42B active parameters, with a score of 46 on its Intelligence Index and listed rates of $0.435/M input and $0.87/M output.
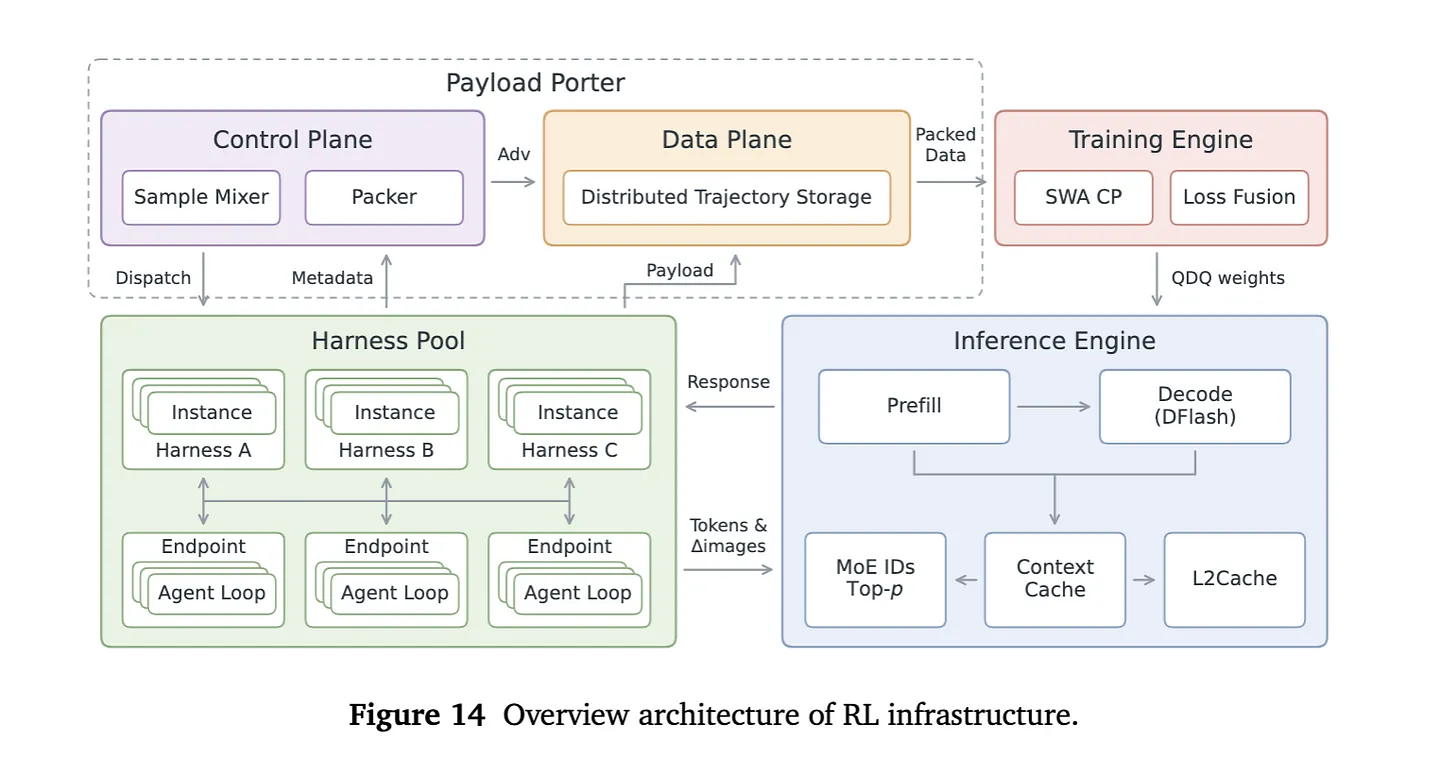
- Xiaomi’s technical report describes an RL recipe using a fully asynchronous architecture, 1,568 samples per update, up to 1M context length, and 3.5–3.7B tokens per step. It mixes coding, general-agent, visual, and cyber tasks across harnesses; group-relative comparisons provide more varied reward signals for long-horizon tasks and steer training toward shorter paths and fewer tokens per task.
- For implementation, Xiaomi links coding recipes, dataset loader, and rewards and composable agent configurations. Xiaomi says the environments and training recipes will be open-sourced, but its 7K+ task datasets had not yet been released.
- A transferable orchestration pattern from the roundup is to use specialized decision models for routing, approval gates, trace scoring, tool selection, and low-cost supervision inside larger agent loops, rather than treating them as standalone agents.
-
The roundup reports Cognition introduced Devin Cloud in Terminal and
devin ssh, exposing Devin’s VM through the CLI and enabling handoff between Devin and the user’s machine; it also says GitHub Copilot had teased editable diffs and shows a Sentry-integrated canvas moving from crash report to fix. These are reported product updates/demos, not firsthand workflow accounts.

John Platt, Google Fellow and head of applied science at Google Research, described ERA as a specialized Gemini-powered research harness; the paper-era setup discussed used Gemini 2.5, and Platt said it likely would not have worked with Gemini 2.0.
- Workflow: A researcher describes a problem, and an agent helps define a scorable objective and creates a Python notebook; supplied papers can guide the initial code, while starter code is optional. ERA then mutates and tests notebook candidates in a tree and can recombine ideas from different candidates.
- Orchestration: ERA keeps shared history of attempts and results, pruning it to manage context. Its default is 10 search leaves at a time: larger batches limit cross-learning. It uses an upper-confidence-bound strategy to favor candidates with promising performance and uncertainty, rather than always choosing the current top scorer.
- Human oversight and rigor: Platt says people often need to refine the objective when the agent finds loopholes, and recommends hidden holdout sets to guard against overfitting. ERA can run for hours before a person reviews examples and steers the next round.
- Firsthand result: In Google’s contrail counterfactual modeling work, the team had been stuck for two years on estimating reflected sunlight; ERA searched confounders and found a simple model that passed synthetic-data tests the team’s earlier attempts had failed.
- Model choice (firsthand use): An Anthropic technical-staff guest says they used Opus 5.5 throughout a personal-site rebuild and sees it as a daily driver; they’d use Fable 5.1 for discrete planning, code review, or security tasks where the cost of error matters more than cost efficiency.
- Tune effort; compare cost per completed task: Matthew Berman’s recap reports Opus 5.5 at 66.4 on Terminal Bench 4.0, ahead of Astra at 57.9 and Fable 5.1 at 55.8. He says that on Frontier Code, medium effort scored higher than max while costing under $1 versus over $5 per task, and recommends experimenting with effort settings rather than defaulting to max. He also reports over 30% faster output and 40% lower cost on typical workloads at default settings versus Opus 5, arguing that cost per completed task matters more than token price alone.
- Keep the harness aligned with model capability: The Anthropic guest says the team removed much of its system prompt, changed tools, and released plug-in evaluations to check whether skills and plugins suit the newer model and help update them so they do not constrain it. For parallel-agent oversight, Berman says shorter, important-first completion summaries make it easier to switch between threads when managing 10–20 agents.
- Model choice and effort: Theo reports that Fable 5.1 is less noisy than Astra and can sustain longer runs; he defaults to High, uses X High for especially deep work, and reserves Low/Medium for deliberately limiting a rabbit hole because a failed lower-effort attempt can mean spending more tokens on a rerun. These are his firsthand usage observations.
- Prompt for a finished outcome: State where the agent should stop—such as filing a PR, monitoring it until checks are green, or merging once it is ready—and give it conditional paths when the right next step depends on what it finds. For PR babysitting, Theo’s skill says to check only comments and CI results newer than the latest push, verify bot findings against source, fix real issues, and avoid scope creep or filler comments.
- Delegate verification across agents: Theo describes Fable as the stronger code writer and Astra as a somewhat better reviewer; he has Fable ask Astra to review or test changes, then revise and retest before reporting back. For computer-use verification, he says Claude is weaker than Codex on macOS and suggests having Fable call Codex for that work.
- Gate risky changes with evidence: In a non-critical Lakebed experiment, Theo had Fable assess a risky runtime change, identify what staging lacked, and build confidence measures including shadow mode, structured refresh-failure reasons, synthetic staging traffic, and runtime health counters. He cautions that this kind of autonomous workflow is dangerous on important codebases without strong staging and QA; during the experiment, laptop-driven testing caused network problems and he told the agent to stop.
- Keep prompts and configuration lean: Theo recommends removing stale formatting rules from Agent.md/Claude.md and starting with minimal defaults, adding instructions only to address observed problems. If an agent is making unrequested changes, he relays this prompt from Anthropic’s guide: “If, while working or testing, you find pre-existing bugs, performance concerns, or behaviors the task doesn't mention, don't fix, optimize, or extend it in this change unless the requested behavior cannot work without it. Report it as a follow-up in your summary.”

LLM 0.36 added gpt-6-sol and gpt-6-luna model support. Model-plugin authors can set supports_conversation = False for single-turn models; LLM raises ConversationNotSupported if they receive assistant or tool history, and llm chat rejects them before a session starts. The first plugin using this capability is llm-typesafe—a useful compatibility guard for integrations that route requests to single-turn models.
- Simon Willison now uses GPT-6 Sol and Claude Opus 5.5 as his default models in Codex and Claude Code; he switched his Datasette Agent demo to GPT-6 Luna, which he says seems fast and competent at SQL queries and building HTML and JavaScript for Datasette Apps.
- GPT-6 Luna costs $0.10/$0.50 per million input/output tokens versus GPT-5.6 Luna at $0.20/$1.20; GPT-6 Sol costs $2/$10 versus GPT-5.6 Sol at $4/$20. Opus 5.5 costs $4/$20, 20% below earlier Opus pricing, and its cache-read price fell 60%—notable for long agent conversations, where Willison says 90%+ of input tokens are processed at cached prices.
- Caution on Opus 5.5 “max”: in Willison’s SVG-generation test, it spent so long reasoning that it hit the 128,000-token output limit without returning a response; the failure repeated, and each run cost $2.56 and took nearly 20 minutes. He suspects max can overthink to the point of breaking, though this test was not a coding-agent benchmark.

Kent C. Dodds says Kody can be useful beyond development once “everything” is wired up . The accompanying ChatGPT example chains a search for an A Christmas Carol audition email, retrieval of its Google Drive sheet music, song identification, Spotify lookup, and practice-playlist creation; it reports finding three songs and says it is building the playlist .
Simon Willison’s llm-anthropic 0.29 adds support for Claude Opus 5.5; it can be invoked through the LLM CLI with llm -m claude-opus-5.5 "prompt goes here".

Addy Osmani introduced Claude Opus 5.5, claiming it costs 40% less than Opus 5, cache reads are 60% cheaper, and it performs at the level of Claude Fable 5.1 for most tasks. He called it a step up from Opus 5 and a strong model for agentic coding and computer use. In a reply, he also said it writes more naturally and follows provided writing rules more closely than Opus 5.
@kentcdodds linked an @dabit3 post relaying a Cognition giveaway announcement: it says Devin now offers models including GPT-6 Astra/Sol/Luna, Claude Opus 5.5 and Fable 5.1, SWE-2, Gemini 3.8 Flash, Grok 4.7, Kimi K3, Inkling, DeepSeek V4.1 Flash and GLM-5.3 Flash; it also lists the Fusion Frontier harness for Fable, Astra, Sol and Opus, and cloud agents on Linux, macOS and Windows. SWE-2 was advertised as free until October 15.

Ben Tossell says Astra generated the device images and built his “50 years of devices” site; he later added a live leaderboard.

Simon Willison says GPT-6 Luna is his favorite model for building product features, citing its cost and speed; he describes it as half the price of GPT-5.6 Luna . OpenAI’s launch post describes GPT-6 Sol and Luna as faster, more affordable models carrying forward much of GPT-6 Astra’s strengths, and says their API prices are 50% below GPT-5.6 promotional pricing .
- Ben Tossell says he used Astra to generate imagery for a “50 years of devices” site and build the site itself; the project lets visitors save devices they had or wanted.
-
Ben shared a demo video made with Nilbuild’s
/video-demoskill. Nilbuild describes invoking it as/video-demo [description]; it records a web-app demo with zoom-ins and voiceover, and users can request revisions until satisfied. The skill’s repository is https://github.com/nilbuild/video-demo.

Jason Zhou says Treg compared Jev with BM25 across 3,000+ endpoints; Treg’s write-up describes Jev in its production search. For agent API/tool discovery, the team kept lexical retrieval but broadened it to the top 30 candidates matching any rare query term, then batch-scored candidates with TypeSafe Jev’s System One model using a Noul yes/no probability question: “Would calling this tool directly accomplish the task, or be a necessary step toward it, on the platform or data source the task requires?” They dropped scores below 0.4, placed scores ≥0.7 in a priority group and scores from 0.4 to below 0.7 in the next group, preserved lexical ordering within groups, and retained existing success-rate and price adjustments. Jev could judge about 30 candidates per request; the reported input cost was about $0.0002 per search at $42 per billion input tokens.
For evaluation, Treg interleaved the two result lists on the same query and credited the variant that contained or ranked higher the tool the agent actually called. The Jev variant won roughly 8.6:1 points excluding ties (rounded to 9:1)—not 9× search accuracy. A call does not establish task completion, and the comparison combines broader retrieval with Jev reranking, so it does not isolate Jev’s contribution.

- Geoffrey Huntley says Underclass now supports automatic Codex subscription resets: when a live request finds every enabled ChatGPT/Codex account unavailable, it redeems one banked reset for the account that would otherwise wait longest for natural quota recovery; the feature is enabled by default.
-
For agent secret handling, Huntley says he added Preflight as a checkpoint because agents might paste
.envinto the model; the request path isclient → preflight → underclass → model. To try it, runnix run github:ghuntley/preflight -- serveand point the harness at:8081instead of:8080; Preflight repo.

Alex Albert says he has been using Opus 5.5 with Blender and that its modeling and vision capabilities let him build an entire world from one prompt; his example is pre-earthquake Market Street, San Francisco, in 1906. The prompt first asks for a research file based on Sanborn maps, a 1906 film, historical photos, and USGS topography, recording each building’s footprint, height, facade material, occupant, sources, and confidence level. It then specifies Blender Python, reusable generators for period buildings and street objects, assembly from the sourced data, no downloaded meshes, textures, or HDRIs, and a 10-second video.