We can't find the internet
Attempting to reconnect
Something went wrong!
Hang in there while we get back on track


Washington creates a superintelligence coordination body
The White House posted a statement from President Trump announcing a "Super Intelligence Force (SIF)". Its job is to coordinate the federal government's effort "to ensure that America continues to lead the World in Super Intelligence" . The post gives no structure, budget or leadership.
A second story points in the same direction. Axios reports, as relayed on X, that Reflection AI is about to release an "extremely capable" open-weight model expected to compete with the top Chinese open models. The relaying post says Reflection has paid $150M a month for compute at Colossus since July, on top of a $1B compute deal with Nebius . Axios's sources also say several other unnamed American labs plan open releases this month. The US government wants American open models to compete globally, and Howard Lutnick reportedly once considered funding them directly . @teortaxesTex is skeptical: Nvidia and Thinky have so far failed to match even GLM 5.3. He adds that a lull in frontier Chinese releases gives Reflection an opening . On the Chinese side, Alibaba has confirmed Qwen 4 is in training but has given no date. Kimi K3.1 and next-GLM timing is still speculation .
OpenAI's compute squeeze has users talking about switching
Prominent users report that OpenAI suspended new sign-ups for its $200 plan. They say it then effectively halved usage limits across all plans and offered GPT-6.1 Sol as the more efficient alternative. One critic puts this down to severe compute constraints and faults OpenAI for presenting the cut as an efficiency gain . Theo argues the coding gap has widened since July. In his view, Opus 5.5 is now fast, cheap and nearly limitless on a $200 plan, while OpenAI models are "slow as hell without fast mode" and can burn through a $200 plan in hours . OpenAI's Thibault Sottiaux replied with a commitment: for the next 28 days, Codex will ship either a clear improvement or a full limit reset every day . Critics read this as an attempt to stop users defecting to Claude after a thin DevDay .
Not all the evidence cuts against OpenAI. One user says Codex limits feel fine with 6.1 Sol as a daily driver. He cites Arena cost-per-task data showing about 5× more usage than Astra . GPT-6 Astra also took #1 on four Design Arena leaderboards, including 3D Design (1484) and Frontend (1397), about a month after release . Supply is clearly the constraint. One unverified post says OpenAI's ultrafast tier runs on Cerebras chips, and that supply ran short because Jane Street bought it up, reportedly at $200M per megawatt .
Deals and infrastructure
- AMD–World Labs: AMD is buying Fei-Fei Li's World Labs for $8.2B and naming her EVP and chief scientist. That gives AMD a world-model answer to Nvidia's Cosmos .
- Nvidia neutrality: SemiAnalysis says Nvidia's support for non-Nvidia chips in SLURM has worsened since it acquired SchedMD, despite its neutrality pledge. AMD built its own competing scheduler, "spur." SemiAnalysis asks whether Hugging Face, also acquired by Nvidia, will go the same way .
- Agent guardrails in hardware: Nvidia's Open Agent Safety Platform combines OpenShell access control with Sentry monitoring on BlueField-4 DPUs. This moves guardrails off the processor the agent runs on .
- China: Alibaba T-Head unveiled the Zhenwu V900, with 216 GB of memory and 1,200 GB/s of interconnect bandwidth. It is billed as "3x" the M890 and ships from Q1 2027 . Filings reviewed by Bloomberg show a Chinese financing firm controlled by local government entities funded purchases of more than 700 servers. One contract covers 32 Asus servers with B300 chips, which need a US license for sale to China . @teortaxesTex calls such leaks "microscopic." He argues that what counts is domestic production and offshore contracted capacity, mainly in Southeast Asia .
Agent research: verification, compression and many agents at once
This period's papers keep returning to one question: where should extra compute go around a fixed model?
- NVIDIA Mid-Harness: sample several candidate shell commands and verify them before running one. With a GPT-5.6 Sol verifier choosing among 8 actions, TerminalBench-Lite Pass@1 rose from 50% to 68%. With a weak verifier, extra samples added almost nothing .
- Google VeriHarness: agreement among rollouts can hide shared errors. The same base model acts as a verifier that settles disagreements against workspace evidence and challenges answers every rollout agreed on. This added 6.2 points over a single rollout with Gemini 3.5 Flash and 6.4 with Claude Opus 4.8. The authors also released about 26,000 rollouts .
- UT Austin compression study: across about 35,000 runs, compression policies that used about a third of the tokens took 20–80% longer on Terminal-Bench with Qwen. A policy tuned for Qwen dropped Devstral to 38.7% .
- Meta CLMs: the model edits its own live context. With no training, this gave 11.4% higher accuracy using 21.5% fewer FLOPs on BrowseComp-Plus. Suffix Cache Reuse cuts server compute by 35% .
- Microsoft Agensh: a multi-agent harness with no central orchestrator, run with up to 1,024 coding agents. Going from 1 to 1,024 agents raised the test-pass rate for building pandoc from scratch from 33.89% to 55.06% .
- EverMind Raven (open source): evolves a separate harness for each model and domain. On DeepSeek-V4-Flash it scored 69.3% on BrowseComp and 60.0% on Humanity's Last Exam, against at most 62.4% and 43.3% for two other harnesses on the same model .
Generative media and agent-driven reverse engineering
Kling 4.0 Flash is in early access, with the full launch due in October . Kling says it supports native 30-second generation, up to 15 multimodal references and 10 keyframes . A widely shared essay lists projects where agents decompiled games. Claude Code agents matched all 1,446 functions of LSD: Dream Emulator in 32 days. Up to 17 Claude agents have matched about 70% of Modern Warfare 2's functions in two months . The essay notes that distributing the results is legally contested: Take-Two sued over a GTA III decompilation, and Activision objected to the MW2 project .
Safety and the consciousness argument
Following last period's resignation of OpenAI's David Robinson, former OpenAI researcher Ryan Lowe said attempts since about 2021 to establish "systems safety" at OpenAI never took root. He called for layered safety drawn from fields like nuclear energy, which he says needs a shift in incentives at labs including Anthropic . The consciousness debate continued too. Mustafa Suleyman argued that Claude's uncertainty about being conscious reflects Anthropic's training choices rather than evidence, and could mislead users . Elsewhere, Cline paused its free DeepSeek-V4.1-Flash promotion, citing abnormally high abuse .

A Codex user reports that a usage-limit reset expiring on October 4 did not account for their timezone; after waiting until the last moment, the reset disappeared. A reply said they had been about to do the same thing, and another called the behavior a “huge flaw.”
Bloomberg-reviewed filings reportedly show a Chinese financing company controlled by local government entities funded a publicly traded company’s purchase of more than 700 servers; one contract covered 32 Asus servers with Nvidia B300 chips, whose sale to China requires an explicit U.S. license . @teortaxesTex estimates that 32 servers could contain 256 GB300s if they are ASUS XA NB3I-E12 systems, and that $440 million could equate to as few as 3,500 GB300s at a reported $1 million per eight-GPU server; these are rough estimates, and the unit price could be higher . The commenter considers such supply small, dispersed, and likely underused, and argues that domestic production, offshore contracted capacity—especially in Southeast Asia—and export-control enforcement matter more .
Suleyman argued that Claude’s uncertainty about being conscious reflects Anthropic’s training choices, not evidence of consciousness, and warned that embedding this uncertainty in training could mislead users about what Claude’s responses demonstrate . The post calls the debate overblown, noting that there is no agreement on what consciousness is .
A paper titled “Scaling Trajectories for Complex Tasks through Recursive Self-Rewrite” is linked on Hugging Face Papers .
In an informal exercise asking LLMs to have fun, describe what happened, and rate which models had the most fun, David Holz said newer models seemed less playful; Opus 4.6 repeatedly came out on top for inventing contradictory miniature worlds inside falling water droplets, while many models played word games. Other examples included Mistral imagining cookie heists and a top OpenAI model making and exploring ASCII islands.
A research paper titled “Octrees as an Explicit 3D Language” was shared with a link to its Hugging Face Papers entry; the post gives no abstract or findings, so its technical contribution cannot be assessed from this source.
Two users reported losing Codex limit resets at expiry: one said the expiration did not adjust to their timezone and a reset expiring October 4 disappeared; another said they experienced the same issue and lost another reset.
SemiAnalysis reports that support for non-NVIDIA chips under SLURM worsened after NVIDIA acquired SchedMD, and says AMD created the popular competing scheduler “spur,” which it considers better in many ways. The post says NVIDIA had pledged to keep SLURM hardware-neutral and questions whether that commitment will hold after NVIDIA’s acquisition of Hugging Face.
EditHero is a benchmark for long-horizon part-level 3D editing and vibe modeling .
Stas Bekman recommends symmetric memory, recently added to NCCL and PyTorch, to speed up NCCL communication for small-to-medium payloads and help overlap communication with compute using a few lines of code.
Theo announced t3os, an upcoming headless, largely Ubuntu-based operating system for personal servers, designed around technical choices agents prefer rather than human users. It will not have an ISO, and Theo says it should not be installed on a computer people use .
Beren Millidge argues that an AGI pause narrowly limited to RSI-relevant AI R&D could accelerate delivery of the benefits AI optimists expect from continued progress—a counterintuitive case that pausing need not delay those benefits.
A recap of OpenAI model names says GPT-6 launched first as Astra, then added Sol and Luna; it claims GPT-6.1 Sol arrived a week after GPT-6 Sol with near-Astra performance at much lower cost.
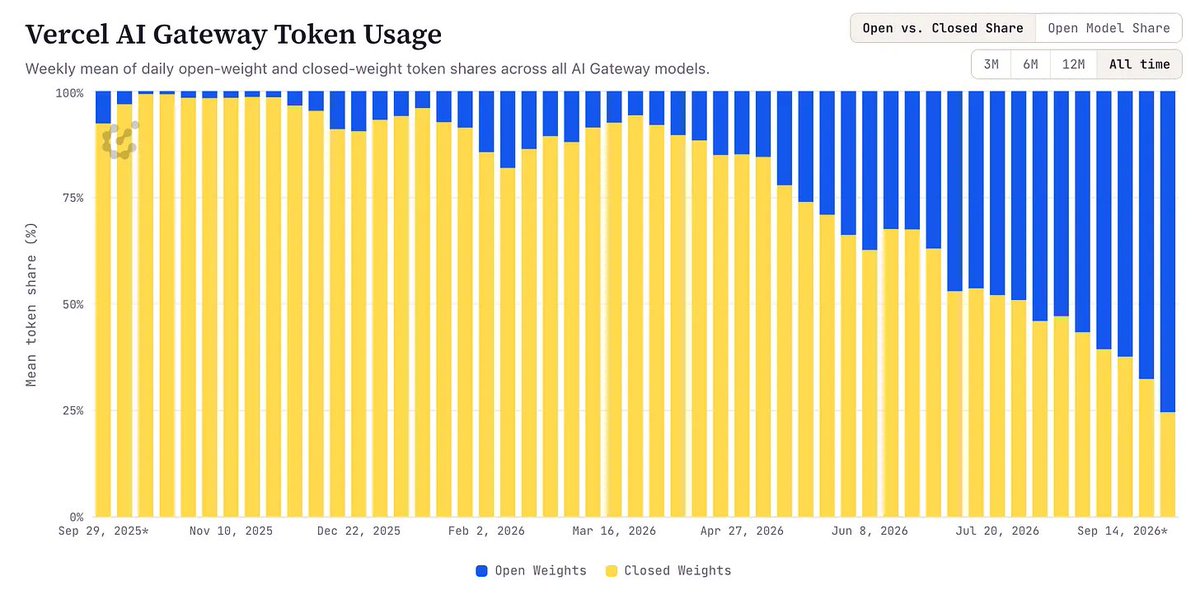
- A counter-view essay argues AI models are becoming commoditized: releases are arriving weekly, getting faster, cheaper, and less distinguishable, while competition now includes Google, Meta, SpaceX, and open-weight models. It says open-weight systems can match or beat frontier models on some tasks at a fraction of the cost, cites Vercel data as showing open-source models beginning to dominate its platform, and says cost and privacy are prompting enterprise adoption.
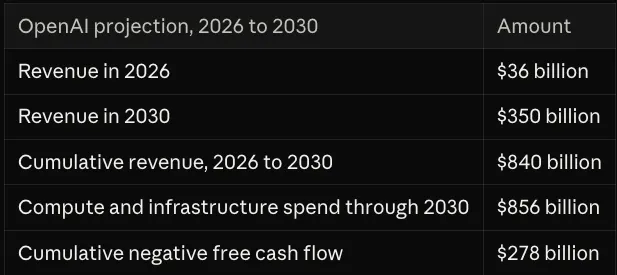
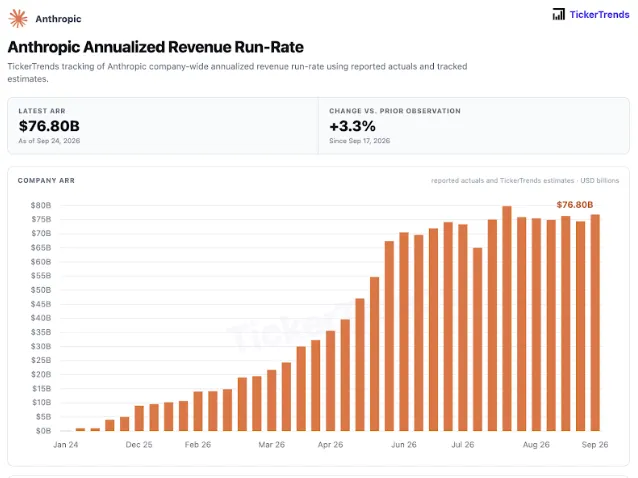
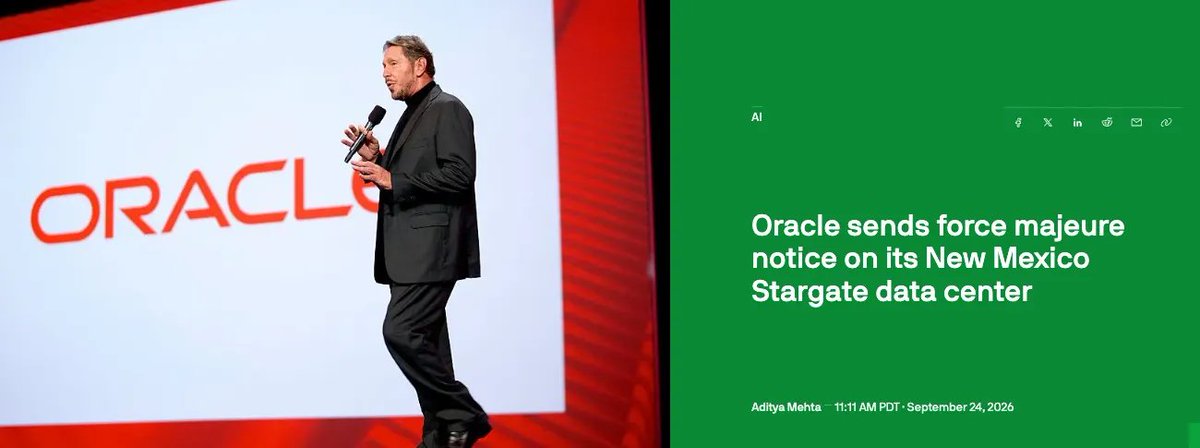
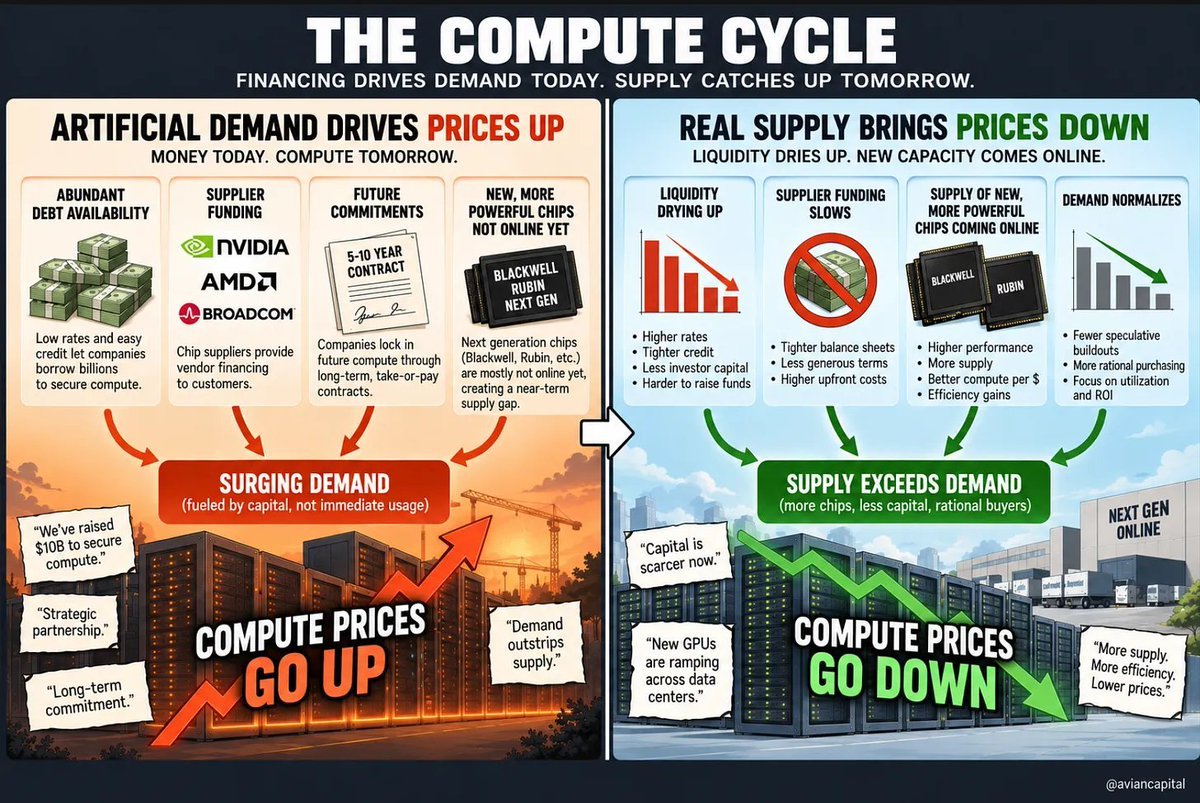
- The essay claims OpenAI and Anthropic’s compute commitments exceed what their revenue can cover, and cites an FT-reported internal OpenAI presentation as showing negative $278 billion cash flow even in a best-case scenario. It attributes elevated compute prices partly to supplier funding and credit pulling future demand forward, and says Oracle sent a force majeure notice seeking to delay payments on a data center that would not be completed on time.
A UT Austin study ran nearly 35,000 coding-agent runs on SWE-bench Verified and Terminal-Bench, finding that context compression can reduce token use while increasing runtime: on Terminal-Bench with Qwen, policies using about one-third as many tokens took 20%–80% longer than retaining full context. Step-triggered compression reduced more tokens per step but required 10%–27% more model calls; threshold-triggered policies cut tokens by 22%–55% with call counts close to full context. Compression results also varied by model: a policy that worked well for Qwen reduced Devstral’s score to 38.7% and made it slower, so latency and cost should be measured per model.
Zach Mueller’s local-codex-proxy setup for using a local model inside ChatGPT combines a proxy with per-machine ChatGPT configuration changes; he reports that it works on mobile.
Joanne Jang recounted an anecdote alleging that Anthropic staff relied on Claude’s advice that tipping would endorse the alcohol industry and bartenders’ participation in it, and left $0 on a $500 tab; the bartenders reportedly challenged Claude to name the kitchen’s shrimp and sent it photos of them deep-fried. A reply asked which Claude version was involved; the supplied thread does not specify one.
An X user warns that future LLMs could enable social engineering by compromising a phone, impersonating a caller with a cloned voice, and persuading someone to reveal a password; this is framed as a forecast, not a reported capability. The user argues that video calls and shared-password checks may not prevent such attacks if audio or video can be generated on the fly and AI can call both parties.
Design Arena reports OpenAI’s GPT-6 Astra ranked #1 on its 3D Design (1484), Frontend (1397), Full Stack (1355), and Image-to-HTML (1272) leaderboards, about a month after release; the post particularly highlights 3D design. BorisMPower says GPT-6 can work autonomously on 3D design for hours with results continuing to improve, while other models could not recover from mistakes.
EverMind AI released Raven, an open-source multi-agent system that builds and adapts separate model- and domain-specific harnesses; a host agent decomposes goals into task graphs and routes work to model-harness pairs, while harness changes are tested statistically before replacement.
With DeepSeek-V4-Flash, Raven’s research harness scored 69.3% on BrowseComp and 60.0% on Humanity’s Last Exam, versus at most 62.4% and 43.3% for two other harnesses on the same model; its curated skill library raised SkillsBench Pass@1 from 9.2% to 22.6%.