We can't find the internet
Attempting to reconnect
Something went wrong!
Hang in there while we get back on track

Hiring now tests the judgment AI can't supply
Aakash Gupta estimates that 40–45% of PM job seekers face at least one take-home or past-project presentation, and that 16–31% of PM hiring processes ask for one. His sources are his own interviews and cohorts of 160 job seekers . Anthropic's candidate rules say not to use Claude unless the company allows it . According to Gupta, graders ask three things: does the work beat the documents already circulating inside the company, does it contain an insight a chatbot wouldn't give everyone, and who put in the most effort. Some run submissions through AI detectors. The real test, he says, is "whether your judgment adds something that AI can't produce for anyone else with the same prompt" .
Mind the Product makes the same point from the hiring manager's side. If a candidate could pass your case study just by using ChatGPT, the round is measuring chatbot access, not the person . One suggested format is the "audit interview": give the candidate flawed AI-generated work, such as a metrics plan that tracks the wrong thing or a launch plan that skips a team that must approve, and see what they catch. Write the rubric first, or you risk hiring whoever sounds most like you .
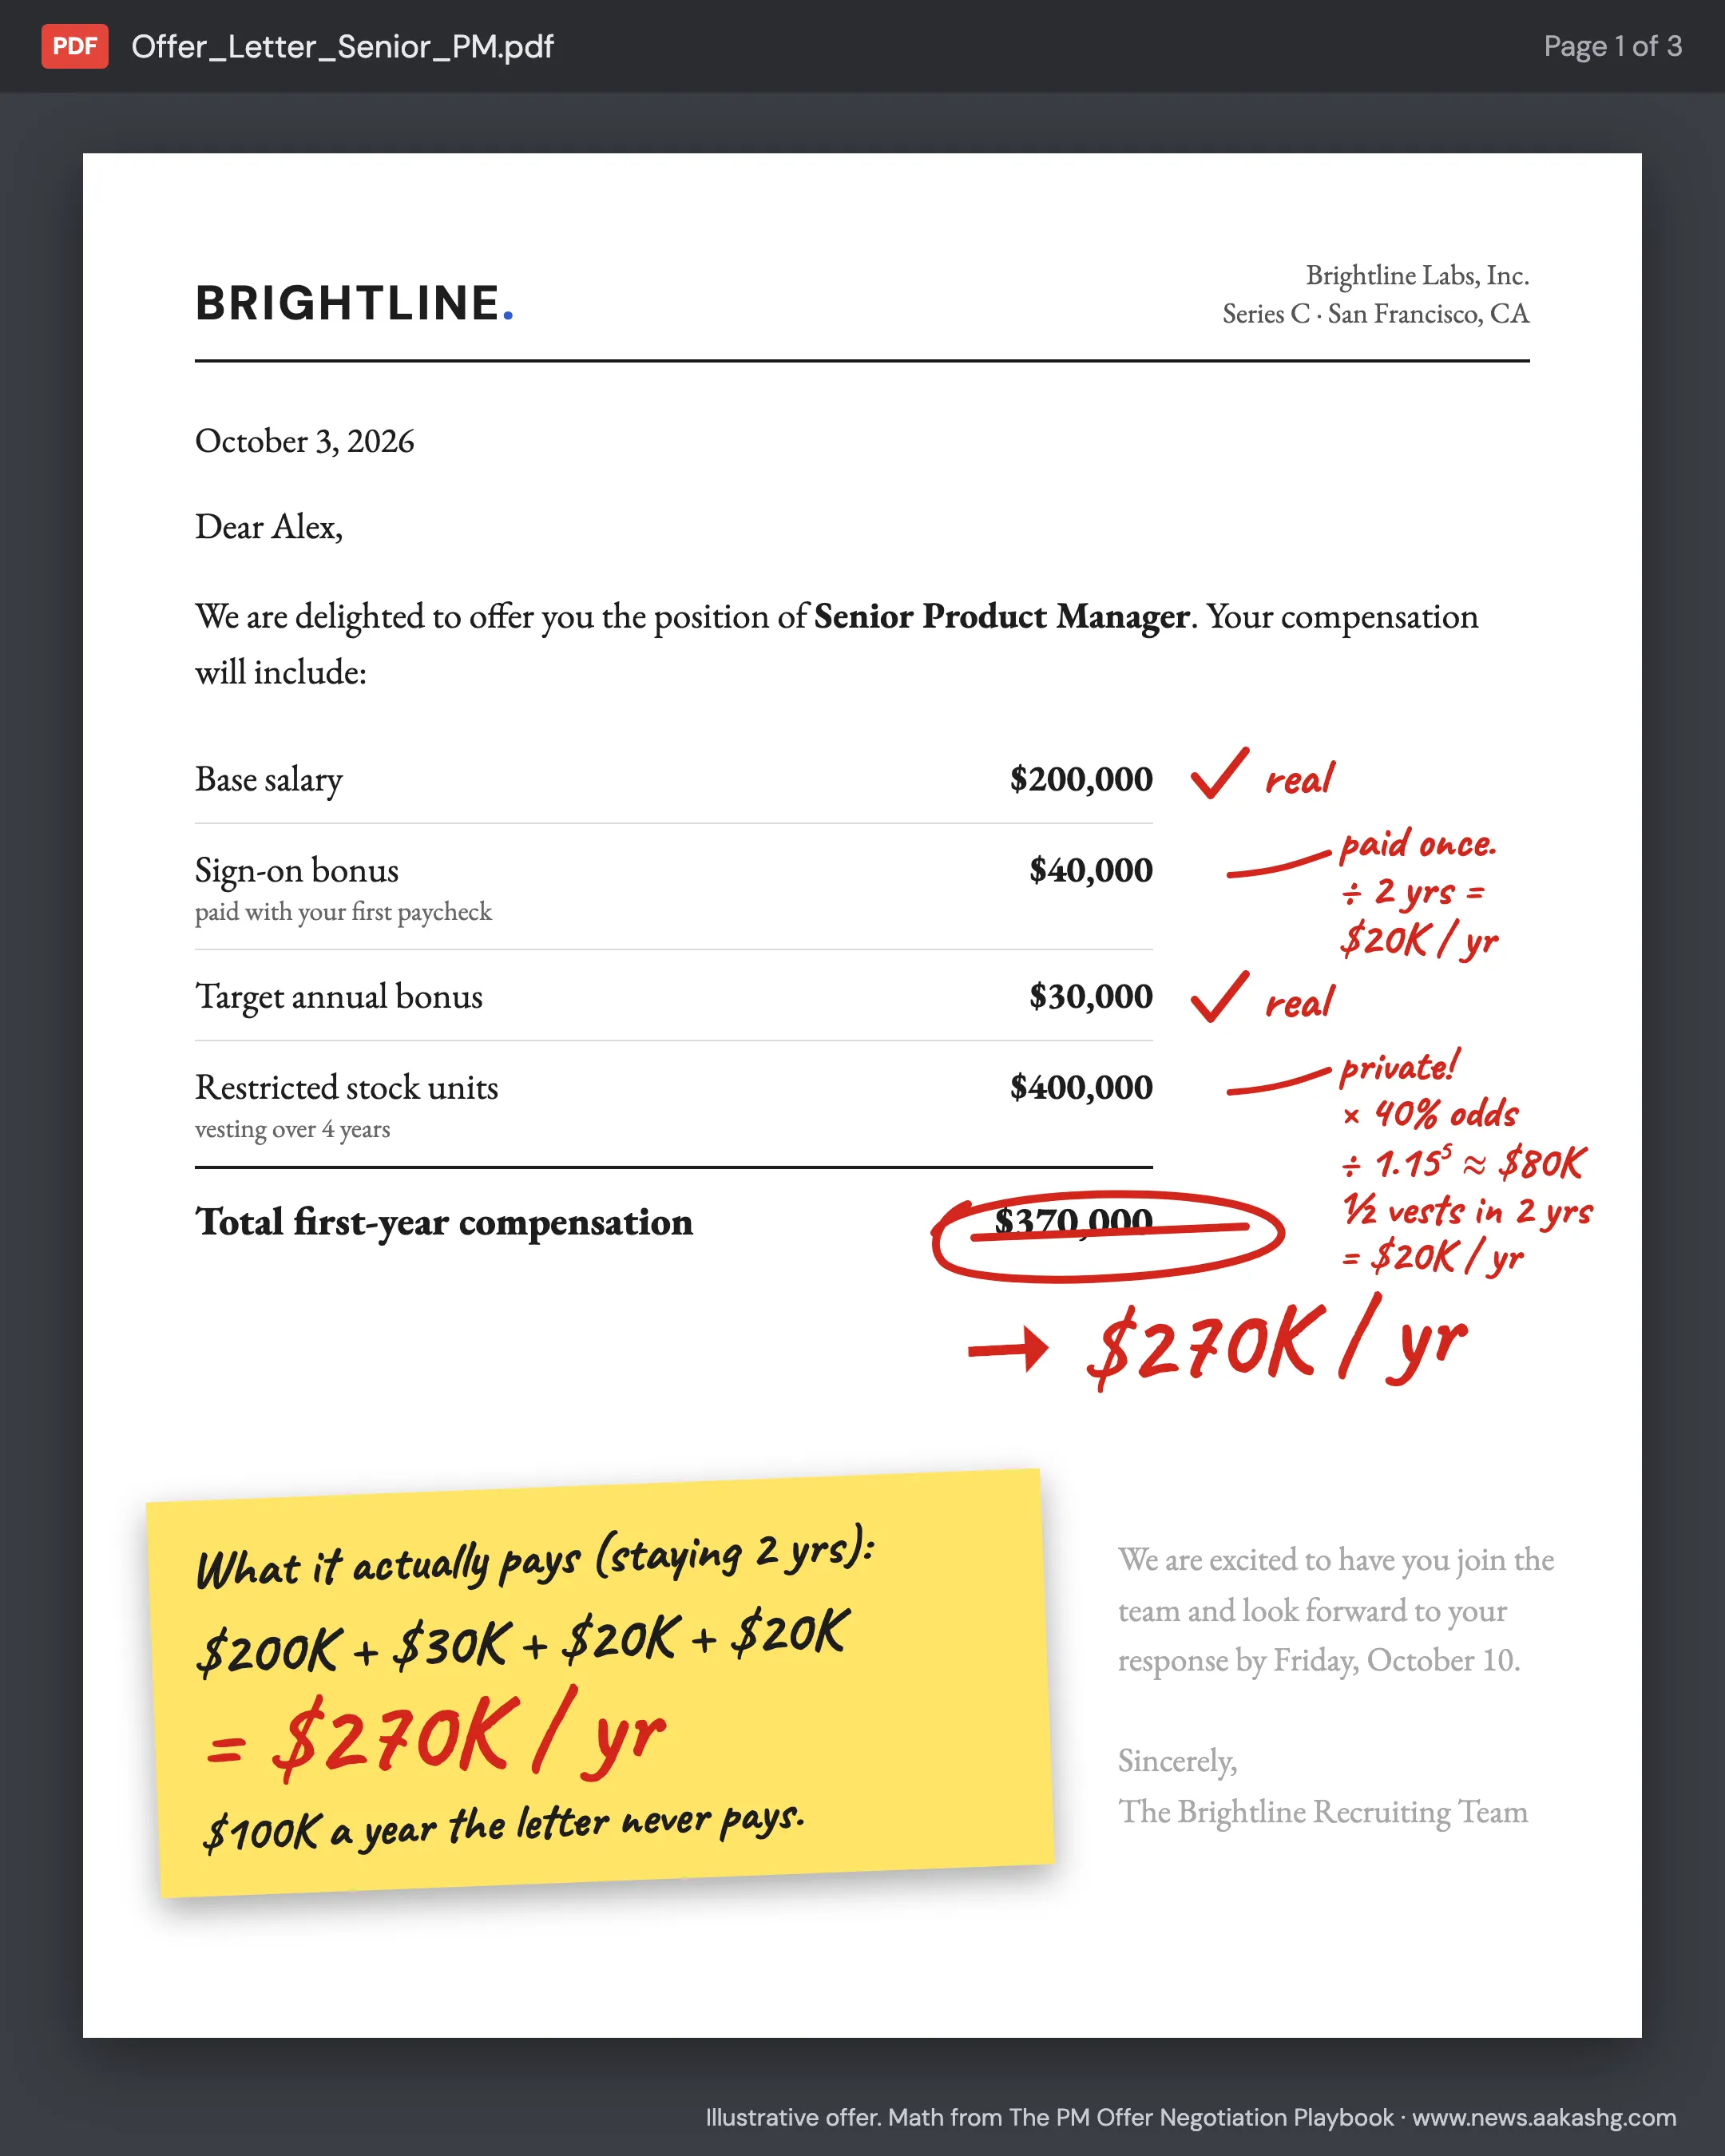
Gupta also covered offer math. Annualize the sign-on bonus over how long you expect to stay. Value private stock as quoted value × odds of payout ÷ 1.15^(years until you can sell) . In his Series C example, the recruiter's $370K first-year figure works out to about $270K a year. That assumes a two-year stay, 40% payout odds and five years to IPO . If you plan to stay 2–3 years, negotiate on sign-on and front-loaded vesting. For 4+ years, negotiate on base and equity .
Observed, believed, tested
Ravi Mehta defines data fluency as turning data into insights that change what the team does, then tying them to business outcomes. "Activation fell" is an observation, not an insight . His warning for AI products: if users send more messages because the assistant's answers need correcting, engagement goes up while value goes down . The core skill is knowing whether you've observed something, believe it, or have tested it .
Hiten Shah's early-access essay applies the same discipline. Each kind of evidence answers a different question: a signup, a task done with the founder's help, an attempt the user makes alone, and a payment. Even payment doesn't prove the product keeps delivering value . Superhuman's "very disappointed" score went from 22% to 33% just because the team narrowed who it surveyed, before any product changes . On feature requests, Shah asks what the user was trying to do, what stopped them, and how often it happens. He warns that following a few highly engaged users can make the product harder for everyone else .
When Customer Success wants the redesign rolled back
On r/ProductManagement, a PM shipped a v2 that changed a legacy workflow. Analytics suggest most users adapted, but Customer Success wants a revert . The strongest reply pointed out that adapting isn't the same as being satisfied, since users may have found workarounds or just stopped complaining. It suggested separating three questions: is v2 better at the task, did the migration add avoidable friction, and is that friction big enough to justify a product change . Another commenter recommended agreeing with CS, in writing, on what would trigger a rollback. Examples: an account up for renewal that cites the change, or a task that measurably takes longer in v2. Anything below that bar gets enablement, not a reopened decision .
Building AI features and agents
- Proven/Better/New. Gupta, citing someone he calls Mark, sorts features into three groups: proven (copies what already works), better (rebuilt for the new platform) and new (never done before). Because AI is already new, keep the "new" share small. A new use case, built a new way, with AI added on top is "too much new" .
- Snaptrude Agent takes building design from a site to a construction-ready model and lets designers decide where cuts land when a budget shrinks. The company reports that more than 2,000 early-access designers ran more than 25,000 tasks. It also built AECBench, its own benchmark, because "an almost correct answer is still wrong" .
- SuperMe raised a $20M Series A led by Forerunner. It turns operators' work into profiles that help you work through a problem, available in group chats, Claude and ChatGPT .

- Treat early access as structured discovery, not just a signup count: find people already facing the problem, study their existing workflows before pitching a proposed solution, and use interviews, prototypes, MVPs, and alpha tests to answer different questions. Crazy Egg drew more than 23,000 prelaunch signups, but that did not establish whether its software helped; at KISSmetrics, roughly 18 months spent pursuing two misdirected product directions preceded workflow research that changed the direction.
- Select early testers whose work fits the product, but keep asking whose work is missing: a well-matched initial cohort can validate the core experience while remaining forgiving. Beam’s early testers exposed pointer offsets, display-size difficulties, permission and sleep issues, and keyboard/display problems; the team responded with input and sizing improvements, unattended-Mac support, and whole-desktop control. Beam reached #1 on Product Hunt on October 19; launch made demand for Intel Mac support more visible, and support for Macs running macOS 14 or later shipped on October 22. The ranking was a launch outcome, not evidence of repeat use.
- Translate feature requests into the underlying task: ask what the user was trying to do, what stopped them, and how often it happens rather than letting isolated requests set priorities. Assess value when the task next arises and how much help it takes; signups, founder-assisted success, independent use, and payment provide different evidence. Superhuman’s “very disappointed” score rose from 22% to 33% when the measured audience narrowed, then to 58% during later product development; the audience change came before that product work, and the survey was not a direct measure of retention or willingness to pay.
- Make beta expectations explicit: explain what works now, what may change, what feedback is wanted, and how users can get help; calling a product a beta does not make failures inconsequential. Gradually reduce founder-led onboarding to test whether users can reach value independently, and widen access to learn under less controlled conditions.
- AI can make a working first version possible in hours, but it does not shorten the wait for another meaningful opportunity to observe infrequent tasks. Working software can look complete before its assumptions are tested; synthetic interviews can help prepare, but real users’ work is still needed to establish whether the product solves a problem.

A roundup of 22 remote roles includes three senior product openings: 1Password’s Senior Director of Product Management – Developer & AI ($267K–$401K), Superhuman’s Head of Growth Product, Mail ($302K–$370K), and Affirm’s Senior Director of Product Management, Financial Platforms ($340K–$375K). A reply clarifies that the 1Password and Superhuman figures are base salaries and exclude equity.
- Treat early access as discovery plus real-world testing: find people already doing the job, study their current workflow before pitching a solution, then observe them using a working product. Choosing users who fit the initial use case can sharpen feedback but leave other teams, tools, and expectations untested; widen access to learn what happens in less controlled conditions.
- Prioritize the problem behind a feature request: ask what the user was trying to do, what blocked them, and how often it happens. Following a few unusually engaged users too closely can make the product harder for everyone else to use.
- Match evidence to the question: a signup, a task completed with founder help, an independent attempt, and a purchase each reveal different things; payment does not prove continuing value. For recurring products, evaluate use when the task next arises—not necessarily the next day—and test whether people can succeed without founder assistance.
- AI can speed up building and iteration, but real-world learning still depends on when users next have the task. For background agents, look for evidence that the work was completed rather than relying on dashboard visits; synthetic interviews cannot show what an actual person did.
- Make unfinished-product expectations explicit: describe what works now and what may change, provide support, and tell users what feedback is sought and what happens when something breaks. Calling a product a beta does not make failures inconsequential.

- PM take-homes or past-project presentations are common but not universal: the author’s interviews and job-seeker cohorts suggest 40–45% of PM candidates face at least one, while 16–31% of hiring processes request one.
- The author reports that Amazon, Airbnb, Anthropic, Uber, Intuit and Databricks assign them regularly, while several other large companies do so depending on role; Series A–D companies and AI-native firms may be more likely to use them. Common formats include PRDs, strategy or roadmap work, case studies, past-project presentations and AI prototypes, so candidates should tailor each response rather than reuse one submission.
- In the AI era, the author says hiring managers look for work that surpasses internal examples, offers a distinct insight rather than a generic AI-generated answer, and demonstrates effort through research and polished writing; the core test is whether the candidate’s judgment adds something AI cannot produce from the same prompt. Anthropic’s candidate guidance is cited as disallowing Claude use unless explicitly permitted.

a16z Speedrun’s SR008 residency is aimed at founders from the earliest stage—even before they have a company or settled idea—and runs Feb. 1–Apr. 18, 2027, in San Francisco. The program offers up to $1M and access to a talent network of 171,000+ engineers, designers, and product people; it reports 230+ hires through the network with no fees.

- In a hypothetical OpenAI product exercise, Bala proposed starting with animal-to-human translation for companion animals—initially dogs and cats—because she said human-to-animal audio lacked science-backed validation and could create safety and trust risks if wrong. Her opportunity case cited a $4–5 billion companion-animal technology and wearables market growing 15–20% year over year; she described Pet Chat’s 95% accuracy claim as self-reported and unverified, and said it had no physical product yet.
- To test demand, she proposed measuring how many ChatGPT users already ask it to interpret pet health or behavior, as a proxy for interest in an animal-focused model. She would target owners who treat pets as family, proactively invest in their well-being, are financially comfortable, and adopt technology early; the initial problem to solve would be triaging discomfort and detecting chronic illness early, since animals may mask pain and the outcomes are more verifiable than interpreting everyday wants.
- Her proposed MVP was an Animal GPT within ChatGPT, using smartphone audio/video alongside physiological data from existing wearable partners via APIs, rather than requiring OpenAI to build hardware. She positioned a more agentic product that takes actions based on its interpretations as a later step.
- Trust and safety guardrails included grounding accuracy claims in peer-reviewed research and third-party verification, routing at least 5% of outputs to board-certified veterinarians and behaviorists, and measuring success by positive outcomes from interventions rather than engagement. For health-related use, she recommended directional guidance rather than diagnosis and prioritizing high recall to reduce false negatives; on-device processing of raw media with only metadata sent to the cloud was proposed as a privacy measure.

Julie Zhuo says Jason Yuan’s theater background comes through in how he tells stories and creates visions . The episode describes Yuan’s path from playwright to Apple designer to Hivemind founder .

SuperMe is positioning operator expertise as AI-assisted problem solving: it says operator profiles can work through users’ problems in group chats with Claude and ChatGPT, and Brian Balfour invited users to use the group-chat experience to debate their problems.

SuperMe positions its product as making operators’ insights accessible without requiring users to have a strong network: it turns operators’ work into profiles that help work through problems, now in group chats and Claude and ChatGPT. The company announced a $20 million Series A led by Forerunner, with Greylock participating.

- Matt Angel argues that trust is more durable when grounded in a business model than in individual leaders: Paradromics’ implantable BCIs are prescribed by doctors, paid for by hospitals, and reimbursed by payers, which he says aligns the business with delivering for patients; platforms paid for by someone other than the user can instead be steered toward that payer.
- As BCIs move from decoding attempted speech toward inner monologue, signals may include private or automatic thoughts; a proposed safeguard is to separate what users want to say from what they want to keep private and let them control how each stream is used. Farahani also says patients have been denied access to neural data and offers have been made to acquire it, making data access and ownership material trust risks.
- In a speech prosthesis, a wearable transmitting 2 bits per second would leave AI to fill about 38 bits of the roughly 40 bits per second needed to transcribe speech; the speakers argue that higher data rates let users steer the system more directly and preserve agency.

- PM interview loops should assess judgment, not just the ability to produce a deliverable: one proposed exercise is to have candidates audit flawed AI-generated work, such as a metrics plan tracking the wrong thing or a launch plan missing a necessary team, then assess what they catch and how they explain it. Set a rubric beforehand to reduce bias. The intended signal is whether candidates can make progress on a messy problem, challenge AI output, and notice what is missing.
- LinkedIn renamed its entry-level APM program “associate product builder,” removed resume upload, and now asks for a 60-second video about a product people use plus answers to six questions. But AI makes polished prototypes easier to produce, and a demo alone may not show whether someone chose the right problem, would abandon a bad idea, or can work with others; taste is also subjective without a scoring rubric.
- Felix Reezberg’s product-relevant advice is to prioritize business impact over backlog throughput, choose one good idea, and build a working prototype over a weekend rather than write a PRD; he also argues newcomers may try things experienced people assume are impossible.
- As zero-click search reduced referral traffic to Philippine news sites by 85% and Facebook’s news distribution had fallen at least 60–70% by 2024, Rappler responded to a 49% advertising-revenue drop by building tech and data capabilities through its sister company Nerve. Its tools identified clusters of attacking messages and the networks spreading them; the tech/data business now contributes roughly 40% of Rappler’s revenue.
- Rappler launched a chat app in 2023 using the Matrix protocol, with 65 Filipino news groups and a rollout into Southeast Asia. The federated product is intended to avoid manipulation and protect information integrity, though Rappler cautions that it may feel “boring.”
- A cross-company trust-and-safety effort gathered tools from companies including OpenAI and Discord, refined them, and made them available free to everyone.

- Ravi defines data fluency as turning data into actionable insights, using them to achieve product goals, and connecting those goals to business outcomes; more activity is not necessarily more value—for example, repeated corrections to AI answers can raise engagement while reducing value.
- Use a four-rung ladder: report what happened, analyze where the pattern occurs, form a possible explanation, then decide what to change and test. Check whether the change produces expected outcomes; distinguish what is observed, believed, and tested, since a pattern or explanation alone does not prove causality.
- AI makes it easier to query structured data and analyze unstructured customer evidence, but wrong data definitions, flattened customer differences, and correlation can mislead. Use analyst and data-science expertise on data trustworthiness, hypothesis testing, and interpretation rather than treating experts as a report queue.
- Data-fluency expectations grow with scope: APMs instrument launches and question metric meaning; PMs investigate behavior and evaluate outcomes; senior PMs frame investment decisions; leaders establish shared standards and an evidence-led culture.
A free session on deciding what to improve before launch once people are trying a product is scheduled for tomorrow at 10am PT; Hiten says it will show the early-access process behind the latest launch. Registration: https://www.hiten.com/early-access-101
Hiten Shah announced a session for AI app builders, scheduled for the next day at 10am PT, on reaching people who need the app and learning what would make them use it again; the announcement links to an early-access page.
Hiten Shah said one X post helped his team find early users before a launch; their feedback surfaced missed problems and changed what shipped. He previewed sharing the research, decisions, and a six-play process for applying the approach to a product.

- For AI features during a platform shift, apply Proven/Better/New: reuse proven patterns, adapt them for the platform, and limit genuinely new elements because AI is already novel; combining a new use case, implementation, and AI can stack too much novelty.
- PM take-homes are common in the author’s samples: 40% (8/20) of interviewed candidates had faced a take-home or past-project presentation, 31% (4/13) of interviewed hiring managers assigned them, and 45% of job-seeker cohort members had faced at least one; the author estimates 40–45% of job seekers and 16–31% of processes encounter them. Assignments include PRDs, strategy or roadmaps, case studies, past projects, and AI prototypes; evaluators look for work that beats internal examples, offers insight beyond generic AI output, and shows effort through research and strong writing. Anthropic’s cited candidate rule is not to use Claude unless explicitly allowed.
- For PM compensation negotiations, annualize sign-on pay over expected tenure and value private equity as quoted value × odds of payout ÷ 1.15^(years until sale). In the example, a $200K base, $30K target bonus, $40K sign-on, and $400K in RSUs work out to about $270K in effective annual compensation—not the $370K first-year figure—under the author’s assumptions of a two-year stay, 40% payout odds, and five years to liquidity. For a 2–3-year stay, prioritize sign-on and front-loaded vesting; for 4+ years, prioritize base and equity.
Before FYI existed, the team’s survey asked respondents how they could participate in building the software; 653 people answered, and the team conducted 52 interviews. Hiten Shah also previewed a session on finding early users and deciding what to build.

For a candidate with 10 years of fintech experience moving toward AI product management, commenters advised targeting AI-PM roles at fintech companies, arguing that domain knowledge may be more valuable than another certificate and can make a stronger pitch than entering a new sector . Another commenter recommended hands-on practice with AI assistants such as Claude, Grok, and ChatGPT rather than relying only on coursework or established learning tracks .

A thread about DoorDash buying Instacart asks what the deal could mean for the companies’ PM organizations . One commenter predicts that many PMs would work on integrations for 3–6 months before layoffs, viewing an acquisition as a poor sign for employees .