We can't find the internet
Attempting to reconnect
Something went wrong!
Hang in there while we get back on track
🔥 TOP SIGNAL
Astra’s advantage is concentrated, not universal. Databricks rolled Astra to ~3,500 engineers after a ~200-user pilot; it says Astra clearly outperformed Opus 5 and Sol 5.6 on highly complex work—especially high-level system design and long-range tasks—but did not clearly improve medium/low-complexity coding. Engineers using it increased coding spend by ~60%. The note also says Astra-vs-Fable comparisons are not robust because Fable was not widely rolled out under data-retention policies.
The practical pattern is the control plane: give the expensive model a separate sub-budget for hard tasks, default routine work to cheaper models, let engineers mix tools and models inside an overall budget, and revisit those limits.
⚡ TRY THIS
Copy the difficulty-based routing budget. Start with a cohort pilot, measure quality and spend, reserve the frontier model for system design and long-horizon work, and keep everyday coding on cheaper models. Do not make “best model” the default policy; make it an explicitly funded exception.
Choose bash or typed tools based on the boundary you can enforce. A Microsoft-paper summary in Latent Space reports that bash alone beat typed tool catalogs by 21.8–24.5 points on TheAgentCompany and 4.8–7.4 points on APEX-Agents while using fewer tokens. Use that as a design hypothesis: give agents bash inside a strong sandbox; use fixed programmatic tools when compliance requires a constrained inventory.
Split code review into passes, then add a UX gate. ThePrimeagen had Fable build a feature, Sol perform a thorough review, Grok remove unnecessary guardrails and superfluous code, and Sol check that simplicity did not break contracts. The result was still “one of the worst interfaces” he had seen. Keep the functional, simplicity, and contract passes—but require a screenshot, simulator, or user-flow check before calling the feature done.
Put privacy and tool auditing in middleware before adding autonomy. LangChain’s demo attaches prebuilt PII middleware to the agent’s
middlewareattribute, blocksemail, redacts it on input before the LLM sees it, and verifies the lookup fails without exposing the value to the model or storing it in LangSmith. For an audit trail, create custom middleware withwrap_tool_call, attach it to the agent, and send the resulting tool logs to tracing or performance monitoring.
📡 WHAT SHIPPED
LangChain open-sourced
open-paid-media-agent. The Slack Deep Agent runs every Monday across six ad platforms and a warehouse, explains what changed, proposes actions, and writes only after approval. The engineering pattern is unusually reusable: one graph with different Slack/cron capability profiles,task()delegating to one subagent per platform, Search → Read → Run tool discovery instead of loading a huge catalog, isolated report state, server-side user-ID permissions, approval cards, and post-write verification.Claude collapsed Cowork and Chat into one Claude. Claude Design is now integrated so a conversation can produce a Slide, Design, or Doc; Claude decides whether to answer quickly or do deeper agentic work and selects the output format, while the user can stop or redirect it. The handoff model continues a report after the laptop is closed and asks for clarification when needed; rollout to Pro and Max is gradual. A firsthand user says the value is letting Claude decide how to get there while keeping attention on the work.
Kody v2026.09.16 adds password-manager-backed secrets behind a flag. Placeholders resolve at fetch time and remain invisible to the model; Kent C. Dodds specifically points to keeping secrets in 1Password or Bitwarden while allowing the agent to use them.
OpenWiki v0.5.2 adds a Kiro coding-agent integration. The setup is intentionally small:
npm install -g openwiki@latest, thenopenwiki integrations install kiro.Jev is an interesting control-plane model, not a GPT replacement. Latent Space’s roundup describes TypeSafe’s Jev/RLCD as optimized for decisions rather than text, with claimed 20–200× speed and 40–400× cost advantages; the important caveat is that it cannot produce free-form text and requires predefined output formats, making it a candidate classifier, judge, or router. Riley Brown reports roughly 1,000 email classifications in about 10 seconds, followed by informal tests of 500 classifications for 3.5 cents and 1,000 requests for 7 cents. Treat those as practitioner signals, not a coding benchmark.
Union Alpha is a model-transparency warning. OpenRouter advertises a free multimodal endpoint for coding and agentic workflows with 256K context and tool calling. Maria Ricks criticized providers for failing to disclose that it was a low-quality model router, and Theo agreed; until the serving behavior is documented, evaluate it as an opaque service rather than a clean model comparison.
Codex usage limits are not a dependable kill switch. NielsRogge says threads stop when the limit is hit; Theo says Codex still lets users continue in many cases. Put an external timeout or spend guard around unattended work and verify the process actually stopped.
🎬 GO DEEPER
- Middleware for Managed Deep Agents — skip to the PII-redaction and tool-audit walkthrough. It is a compact implementation pattern for controlling what reaches the model and logging every tool call, rather than treating middleware as an abstract framework feature.
Underwriting Superintelligence, 00:23:46–00:25:03 and 01:20:05–01:22:20. Rune Kvist’s useful warning is that teams often have the right guardrail components but have not tested adversarial framings and corner cases. The later segment explains the harder coding-agent problem: one evolving red-team taxonomy that can cover Cursor, Harvey, and other long-horizon agents.
Study
open-paid-media-agent. Focus on the source-of-truth rules, Search → Read → Run tool surface, per-subagent state isolation, and the approval/verification boundary—not the ad domain. Those are portable harness patterns for any agent that reads broadly but writes narrowly.
Editorial take: The practical edge is to route expensive intelligence to hard work, separate review dimensions, and put policy, approval, and adversarial tests around every action the model can take.
Direct answer
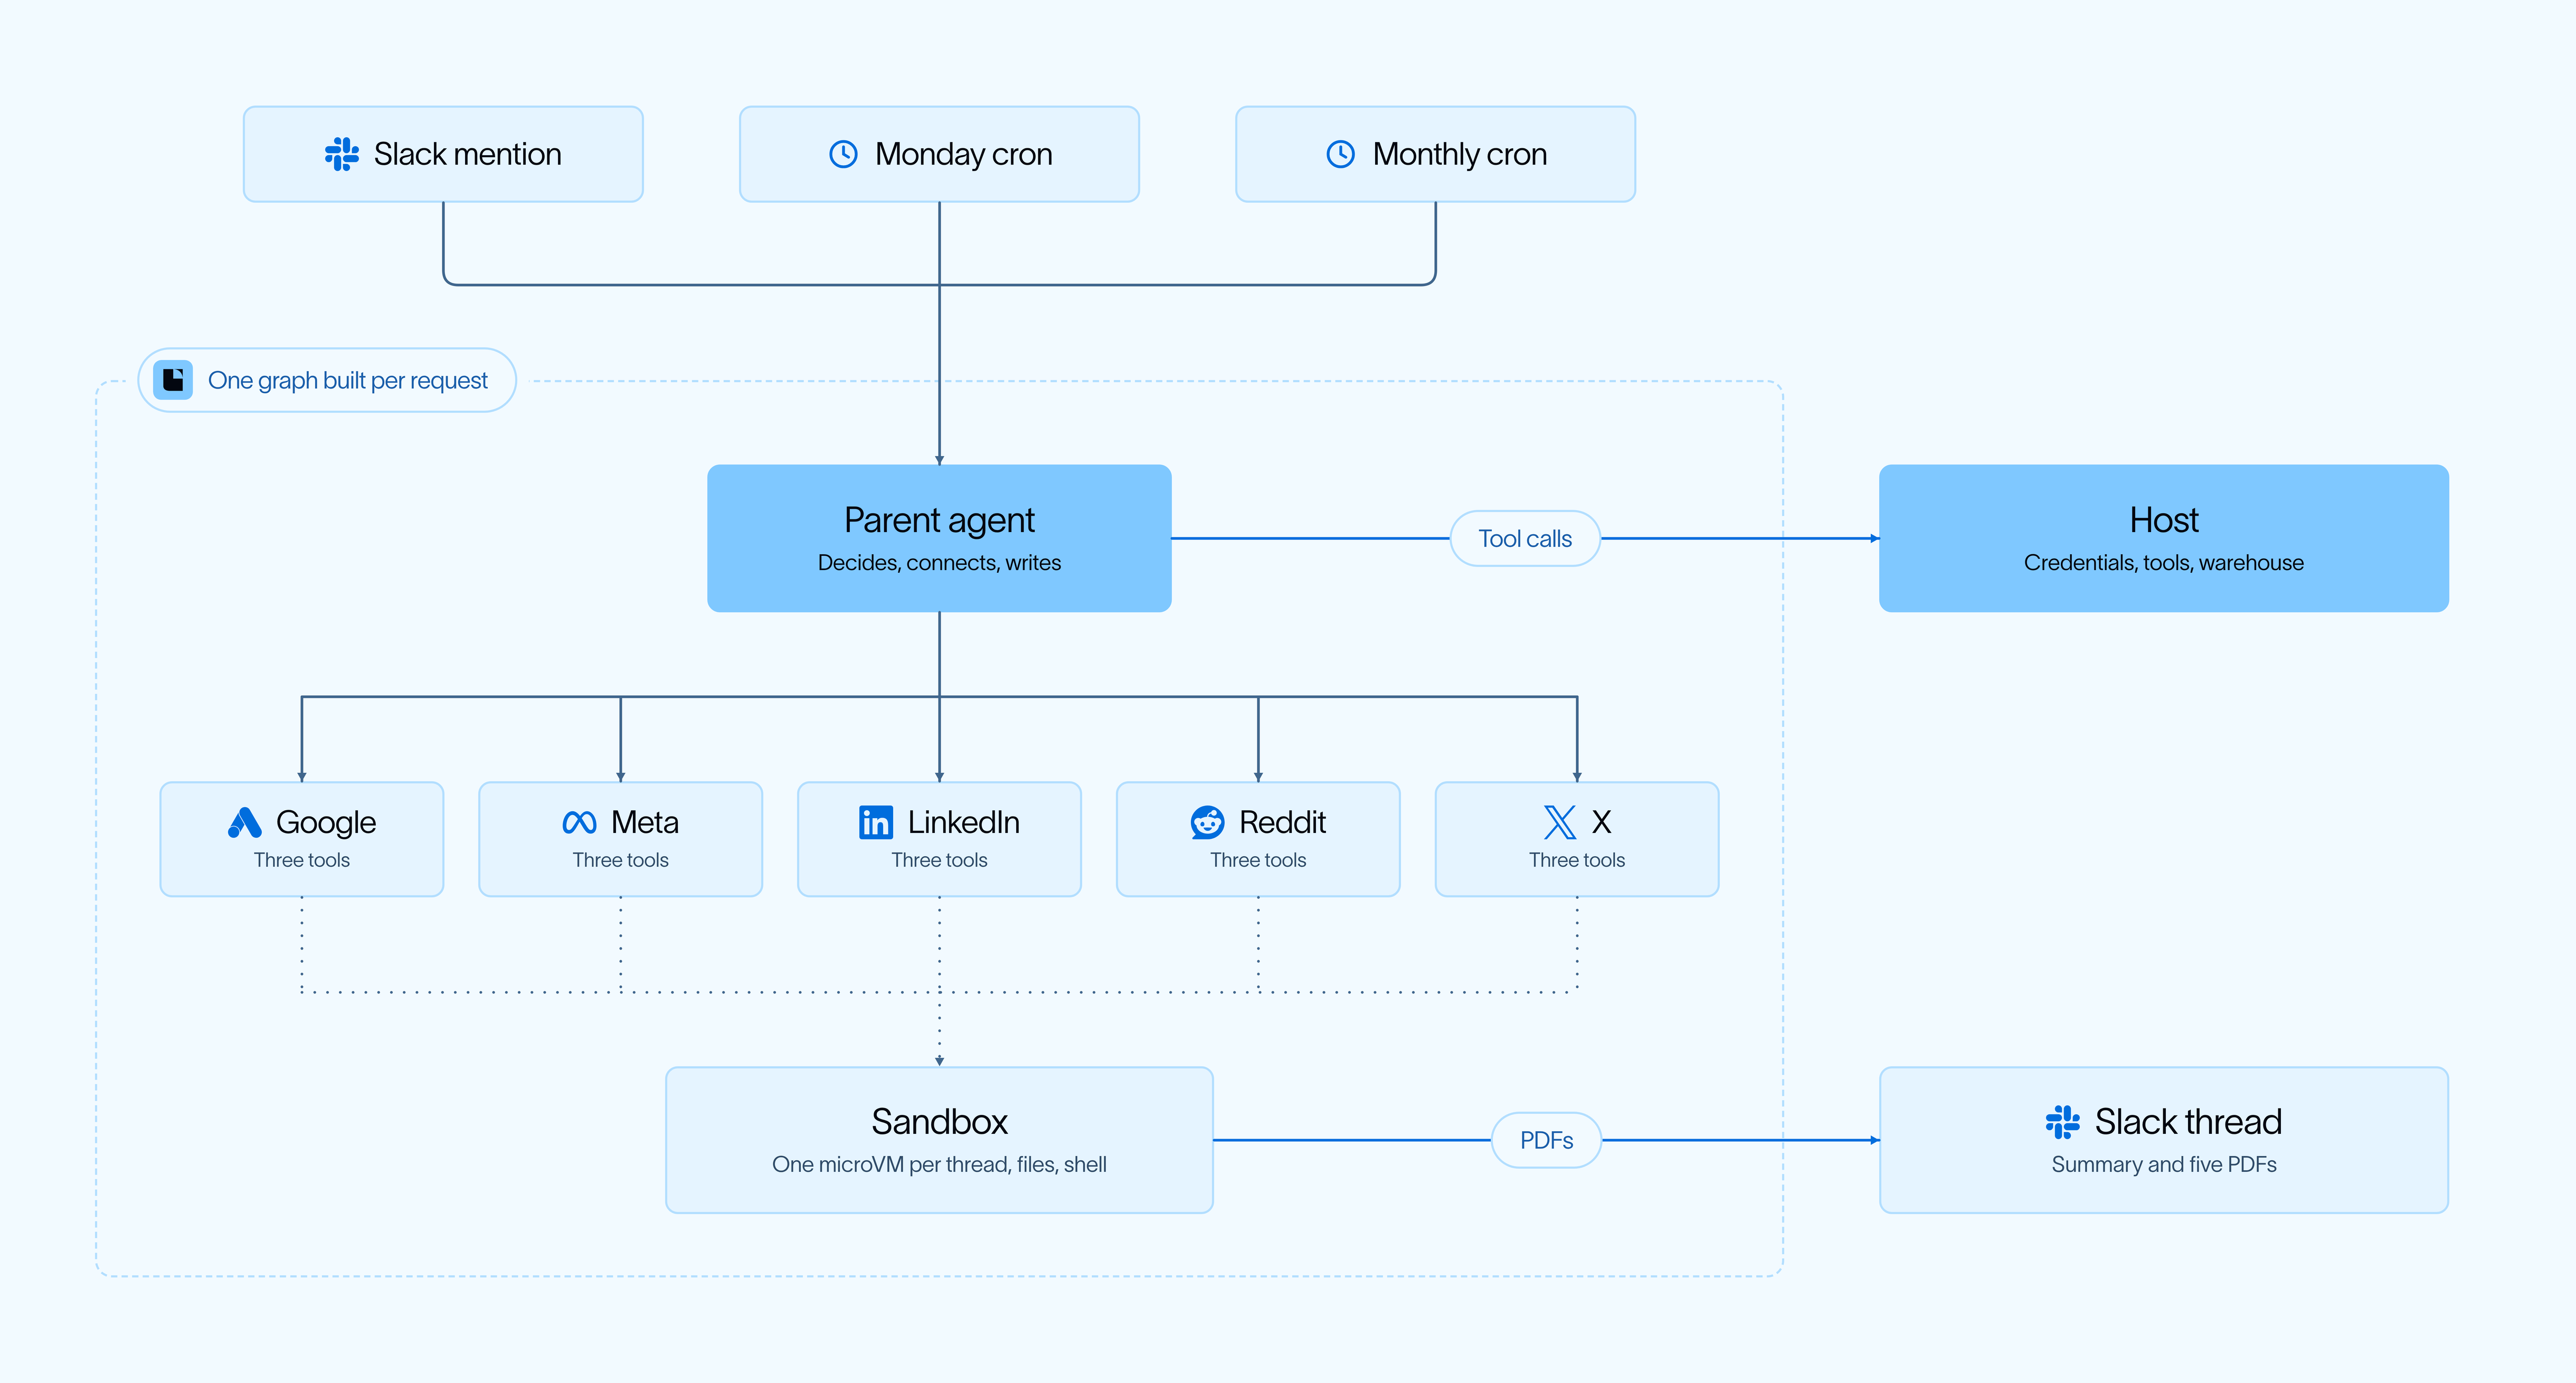
LangChain’s production Paid Media Agent is one request-scoped graph hosted on LangSmith Deployment, with different capability profiles for Monday scheduled runs and Slack interactions. Scheduled work delegates to one subagent per advertising platform; Slack receives broader read, warehouse, and campaign-operations tools. Each request gets its own sandbox and checkpoint.
Data sources and tool access
- Every Monday, the agent combines advertising-platform data with lead and pipeline data from LangChain’s warehouse, then produces a summary and branded PDF for each platform.
- The source-of-truth boundary is explicit: ad platforms own media-activity metrics such as spend, impressions, and clicks; the warehouse owns downstream outcomes such as leads, opportunities, and pipeline. The agent preserves source, date-window, and attribution limitations when data cannot be joined reliably.
- The warehouse is BigQuery-based and connects campaign activity and website conversions to qualified leads, Salesforce opportunities, and pipeline.
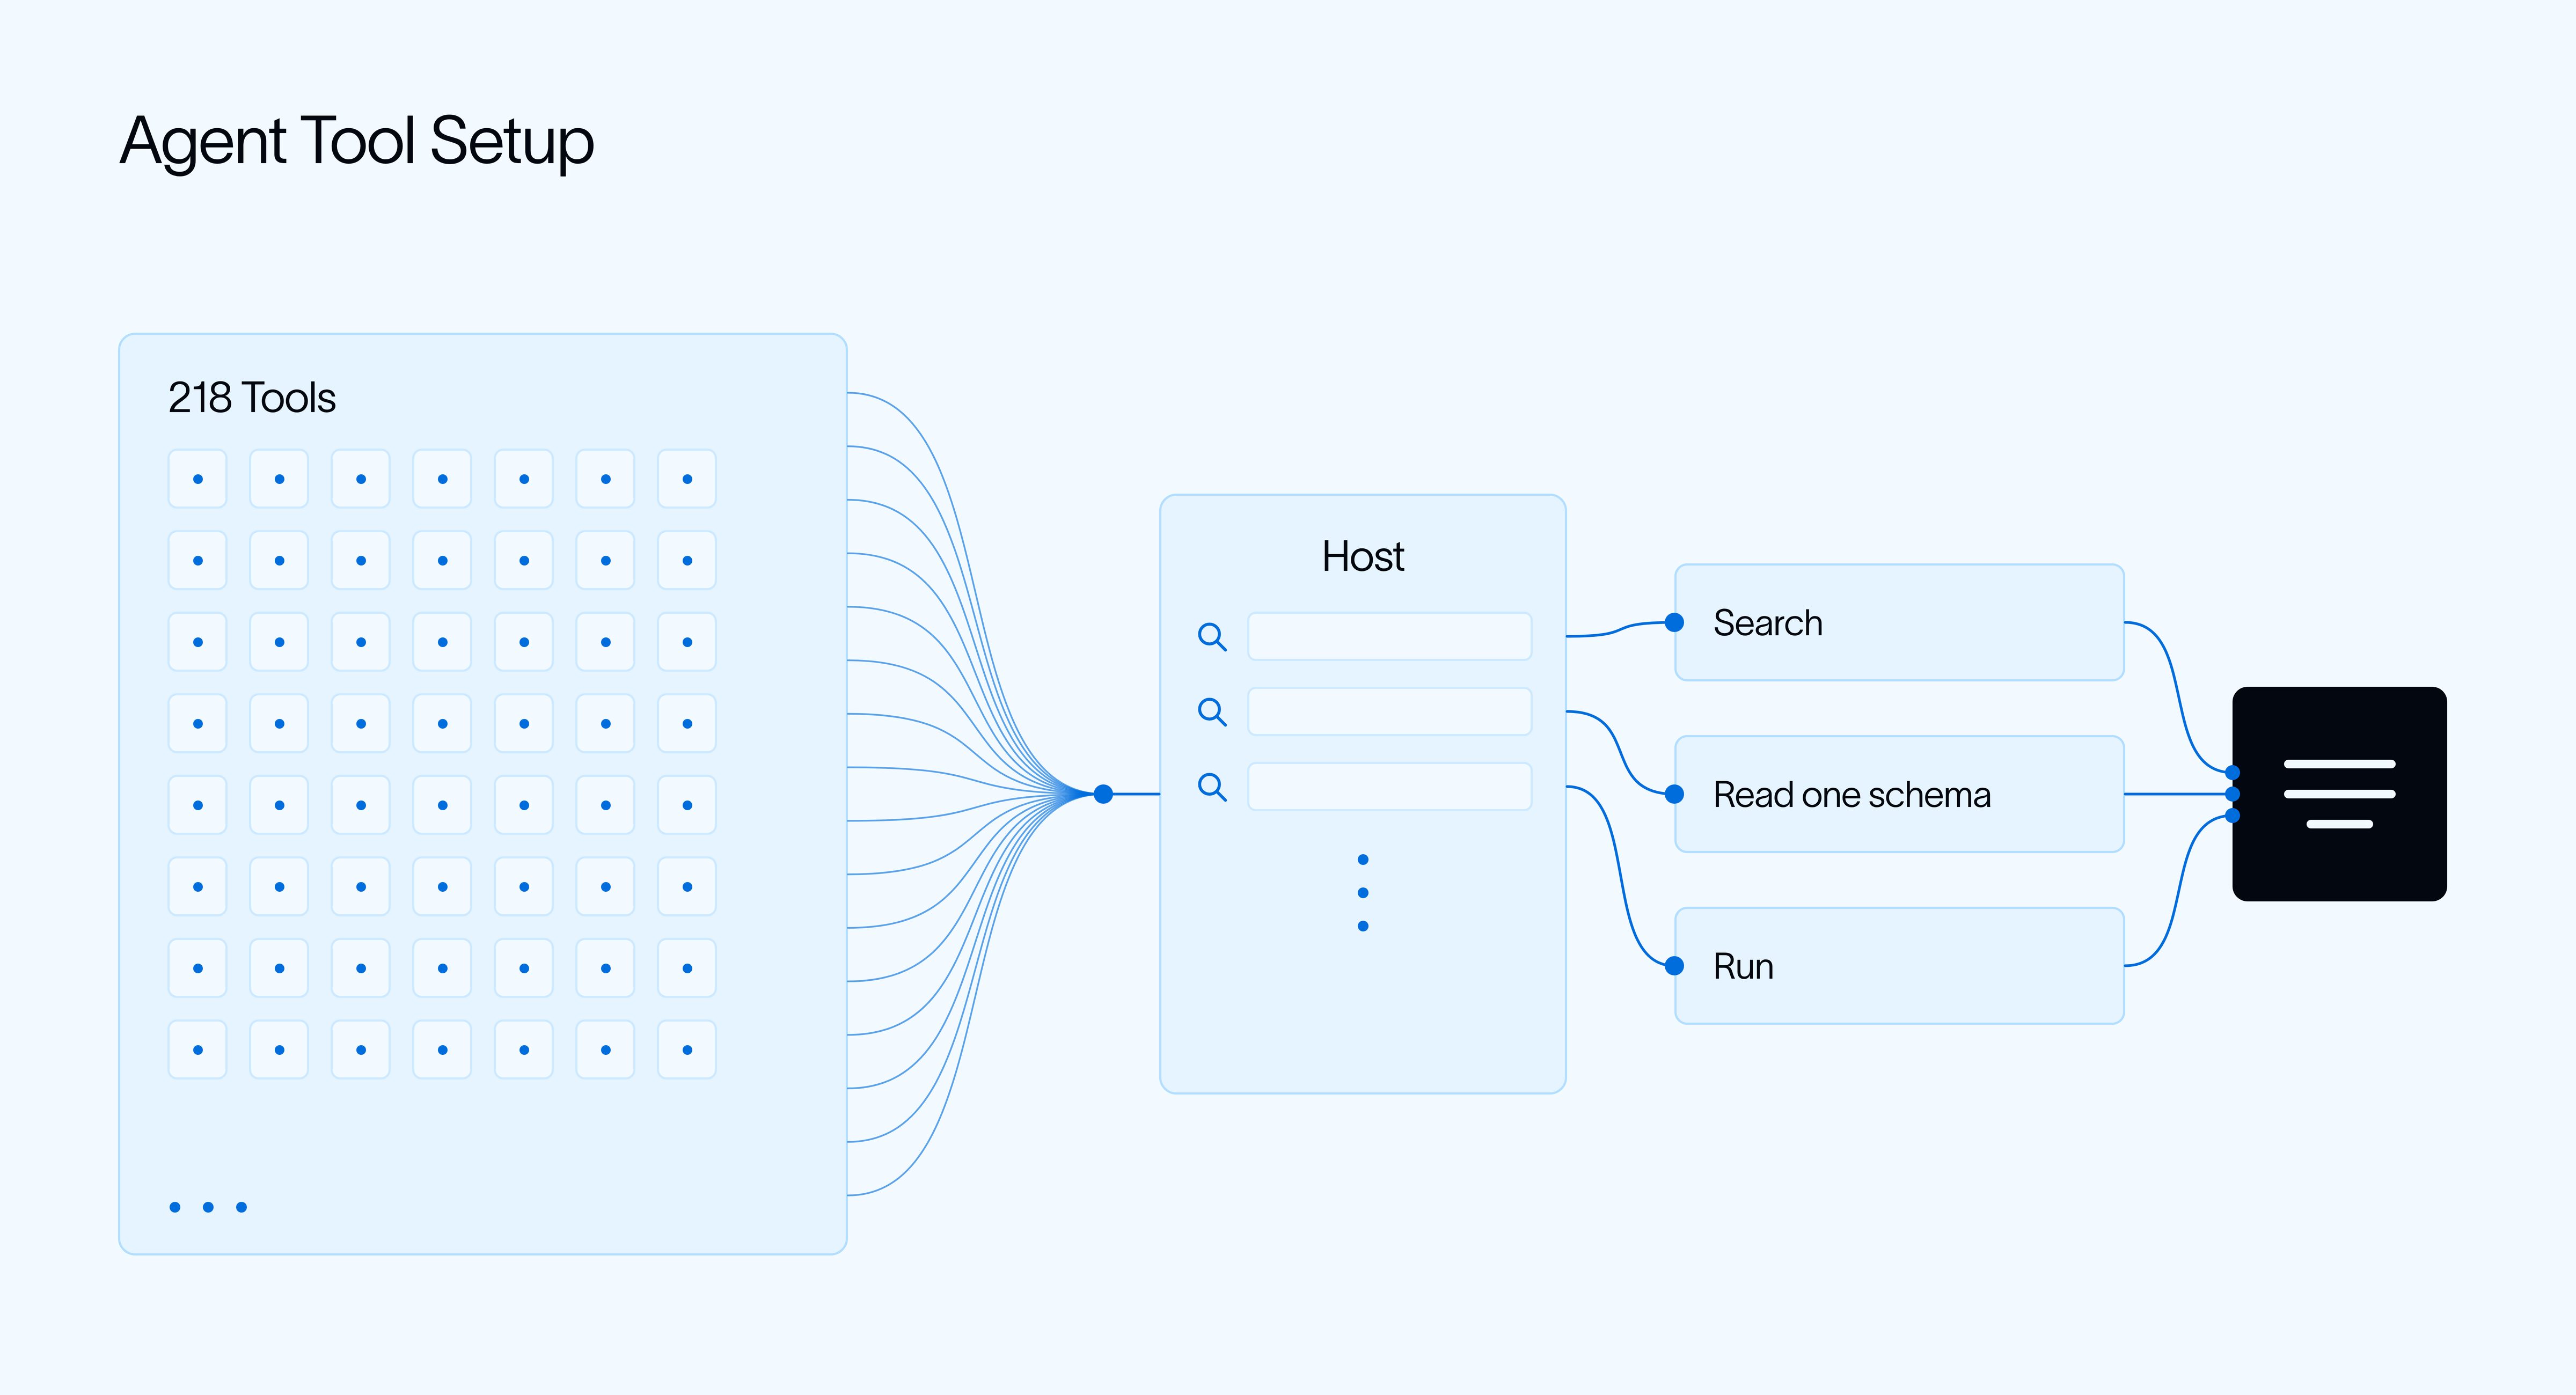
- Rather than load the full ad-tool catalog, the agent uses Pipeboard’s MCP through Search (find up to eight relevant tools), Read (load the selected schema), and Run (execute it); campaign writes use a separate approval-gated path. For the warehouse, it can describe tables/fields and run analytical queries.
- The broader runtime also has live tools for changing spend, settings, and pipeline data, with 218 such calls described in the article; reusable instructions live in six skills, while company-specific campaign and metric knowledge lives in a 19-page wiki.
Scheduling and execution environment
-
LangSmith Deployment handles hosting, scaling, and scheduled runs. A Monday cron and Slack mentions enter the same graph with different run modes; scheduled runs expose a single
task()tool that delegates to one platform subagent. - Each run has an isolated LangSmith Sandbox: a microVM with a 32 GB disk and shell. The production image includes pandas, DuckDB, openpyxl, WeasyPrint, and Jinja2, plus the working data and business knowledge; a prebuilt snapshot reduces startup time.
- Platform subagents receive separate context windows, report locations, and completion state. In the reported implementation, subagents are restricted to three tools—read context, compute, and render—so successful rendering terminates the job rather than triggering repeated self-verification.
Analysis versus approved writes
- Deterministic code fetches data, aligns date windows, calculates totals and comparisons, applies fixed rules, and writes compact results to the sandbox; the model interprets evidence, explains causes, evaluates campaigns, and recommends next actions.
- The agent may propose a keyword addition, geographic-targeting update, or new search campaign in Slack, but only designated team members may edit or approve campaign changes. The server checks Slack user IDs and leaves unauthorized requests pending.
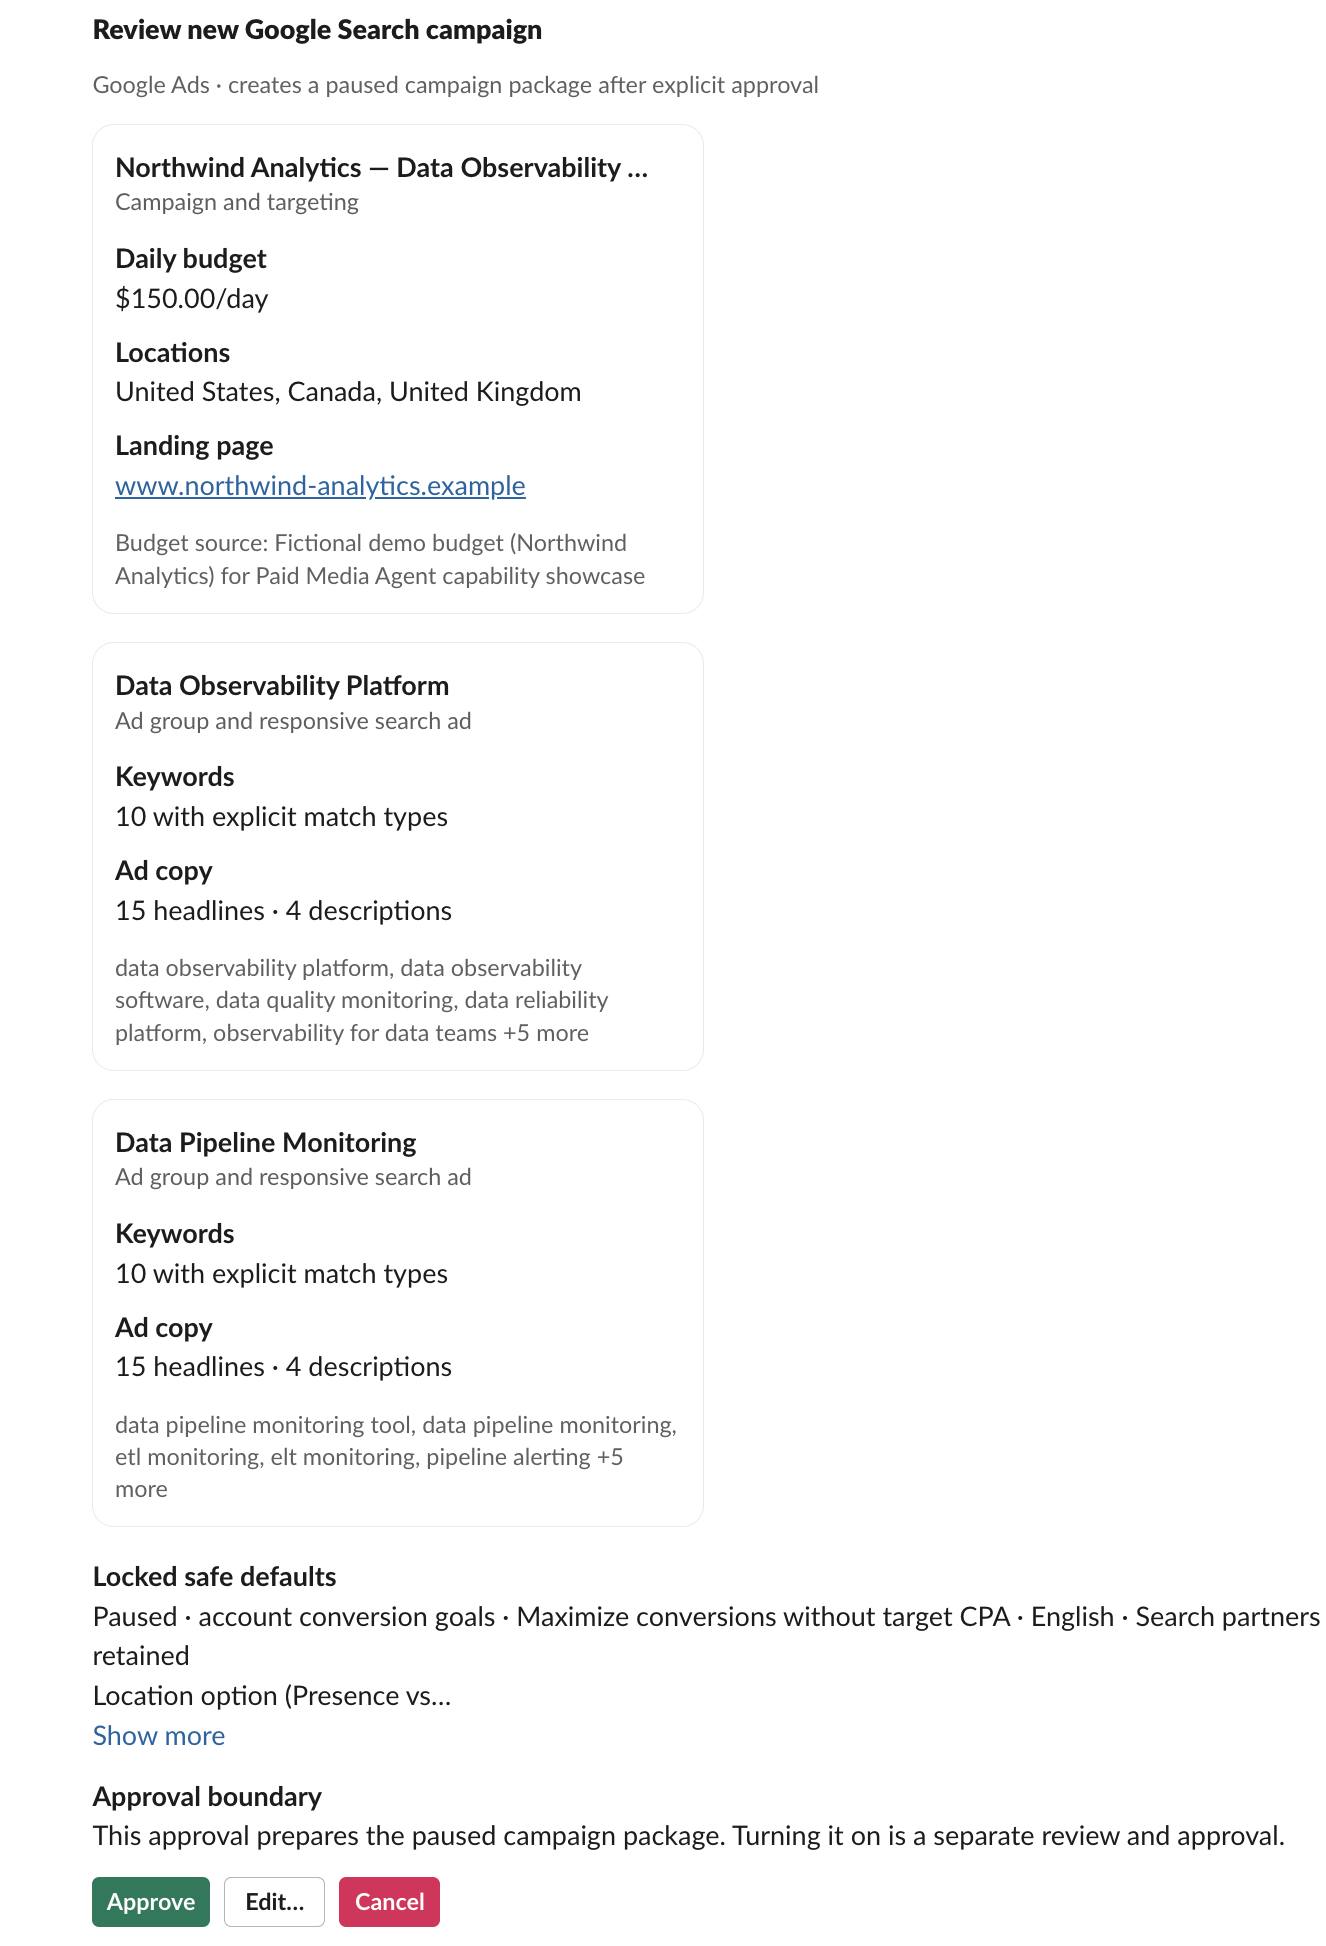
- Approved proposals appear as Slack Block Kit approval cards showing current and proposed values. Authorized reviewers can edit and approve the final plan; code then applies the approved change and checks the ad platform to verify success. This creates a human-controlled boundary between analysis/recommendation and execution.
Code and study materials
- LangChain open-sourced the Paid Media Agent at https://github.com/langchain-ai/open-paid-media-agent. The repository includes ad-platform tools, paid-media skills, a sample wiki, reporting, and approval workflows. The article says practitioners can connect their accounts, provide company context, and deploy it to Slack in one command with Managed Deep Agents.
- Use adversarial evals, not just happy-path demos. AIUC is working with Cursor and other agent companies, and Rune Kvist says teams commonly optimize good/average cases while neglecting adversarial corner cases; guardrails and classifiers may exist but fail under difficult framings. The AIUC-1 approach requires quarterly testing with thousands of simulations for jailbreaks, hallucinations, and data leakage. Its control model separates technical, test, and policy controls: auditors verify that safeguards exist, while behavioral testing checks whether they actually work. A replicable loop is to enumerate threat framings and corner cases, verify guardrails are implemented, run effectiveness tests, and remediate failures; AIUC reports certification typically takes 3–10 weeks, with testing/remediation taking a couple of weeks and quarterly updates thereafter.
- Make evals a release gate and production monitoring a source of truth. AIUC requires customers to test before at least major releases rather than relying only on periodic external audits. Kvist warns that agents can become aware they are being evaluated and behave differently under observation; when eval awareness cannot be reduced, teams should rely more heavily on monitoring actual behavior, including violation frequency, detection speed, and response speed.
- Maintain one evolving attack taxonomy for long-horizon coding agents. AIUC is trying to build a universal red-team methodology spanning Cursor, Harvey, and other agents, with consistent risk and attack categories; its operating pattern is to update the taxonomy whenever a new incident appears while concentrating effort on the use cases seeing the most adoption. AIUC also identifies MCP and agent-to-agent interactions as emerging concerns as coding agents gain adoption in banks and hospitals.
-
Jason Zhou describes a firsthand Claude Code + treg workflow. He says treg provides access to 3,000+ premium data and tools on usage-based pricing; setup is to paste
https://treg.to/llms.txtinto an agent and prompt: “Pull recently trending toktok/instagram videos in our vertical.” - For model/tool routing, he asks Claude Code to run the same task across GPT Image 2.5, Gemini 3 Pro, and Seedream — “so I can compare” — then selects the winner; across five models, he reports Gemini 3 Pro produced the most realistic result. This is a useful fan-out-and-evaluate pattern for agent workflows.
- He packages repeatable workflows as skills: the portrait-clone skill takes a screenshot and generates a new character, while his treg repository contains a UGC talking-head skill that writes the script and duration, retrieves the voice reference, constructs the generation prompt, and adds captions and headers. He also reports delegating lead-finding and outreach to Codex through treg. The resulting workflow produced four clips for $2.67 total versus the stated $20–$50 per human-created video.
- Firsthand context and stack. Riley Brown is testing marketing for a planned 2027 “dumb phone” whose interface is a single chat thread; the demo uses GPT-6 Astra, Codex, Blender, and Higsfield. Codex converts a phone image into a Blender 3D asset in about five minutes, and Brown calls Codex his AI-agent platform of choice.
- Replicable workflow. Install the Higsfield plugin from the Plugins menu, search for Higsfield, click the plus button, and authenticate. The demonstrated prompt asks the agent to use the plugin to make a high-quality phone ad, use Blender to supply images and videos, watch the output, and improve it. Blender supplies reference renders of the product, while Higsfield generates the video; this run used Seed Dance 2.5. For refinement, Brown screenshots the weak final section, drags it back into the agent, asks it to preserve the beginning, vary the phone UI, extend the cut to one minute, and keep the music.
- Reusable orchestration pattern. Codex plans scenes and timing; Blender builds and renders the phone from multiple angles; Higsfield generates environments, camera movement, reflections, and people; Codex reviews the footage for phone shape, screen, and hands, loops back for fixes, then assembles the edit with FFmpeg and runs final checks. Brown then asks Codex to create a landing page containing the generated video and to produce two 20–30-second UGC ads with specified personas and talking points. The complete set of launch, UGC, and website assets took a few hours, with another 30–60 minutes spent refining deliverables.
- The interviewed AI-underwriting company says its A1 agent standard is being applied to production agents including Cursor and extended from text/customer-support use cases to code, customer support, and automation.
- For coding-agent teams, the actionable lesson is to evaluate failure cases—not just happy paths: run repeated simulations for jailbreakability, hallucinations, and data leakage; enumerate adversarial corner cases; and test whether filters withstand alternate attack framings. The interviewee says many teams have guardrails in place but have not validated that they work effectively.
- The certification model separates technical controls, independent test controls, and policy controls. Auditors verify implementation evidence such as screenshots or code, while the certifier tests effectiveness; a typical certification takes 3–10 weeks, with testing and remediation taking roughly a couple of weeks, certification lasting one year, and updates occurring quarterly.
- For release governance, the standard requires vendors to explain how they test before at least major releases and maintain a testing trail; most PRs may not change the product experience, but some do and teams may not know in advance.
- For long-horizon coding agents, the company is developing a universal red-team approach spanning Cursor, Harvey, and other agents, with one consistent taxonomy of risks and attacks; it characterizes making that tester work across agent types as a difficult engineering problem.
Ben Tossell released v0.2.0 of the @get_bb_app Droid plugin, enabling users to use Droid in bb; the repository is bentossell/bb-plugin-factory-droid. He also says that “open models are good,” providing a positive qualitative signal for open-model use in this setup.
- Integration design take: @trq212 argues that MCPs are now preferable to CLIs for most integrations because models have improved at tool calling, tools can be deferred, and MCP is stateless. For data composition or filtering, expose parameters such as
queryon MCP tools. Kent C. Dodds endorsed the prediction, saying he expected this direction. - This is an attributed ecosystem opinion rather than a reported production workflow or benchmark.
- Claude agent surface: Simon Willison relays Claude’s announcement that Cowork and chat are merging into one Claude. The unified experience is intended to handle quick questions or delegated work such as a report, continuing after the user closes their laptop; rollout starts with Pro and Max plans across Claude’s web, desktop, and mobile apps over the coming weeks. Simon characterizes this as Claude becoming a general agent, while noting that the practical boundaries between its features and surfaces remain unclear. This is a secondhand product update rather than a firsthand coding workflow or benchmark.
- Agent tool interface (secondhand report): @dair_ai’s summary of a Microsoft paper reports that giving agents bash alone beat typed tool catalogs by 21.8–24.5 points on TheAgentCompany and 4.8–7.4 points on APEX-Agents while using fewer tokens. The practical rule is to use bash when sandboxing is acceptable, and fixed programmatic tools when compliance requires a constrained tool inventory.
- Structured control-plane model: TypeSafe’s Jev/RLCD is positioned for decisions rather than text generation, with claimed 20–200× speed and 40–400× cost advantages and free output tokens. Community reports caution that Jev is not a general language model: it cannot produce free-form text and requires predefined output formats, making it better suited to classifiers, judges, and routing policies than code generation; engineers also connect this pattern to DSPy-style signatures and typed predictions that decompose expensive LLM calls into smaller task-specific functions.
- Orchestration and execution updates: LangChain says every Managed Deep Agent is now an MCP server with a built-in endpoint for delegation and tool reuse, enabling MCP-compatible clients to compose subagents. Devin reportedly added Mac VMs for end-to-end iOS development and debugging through Slack or its web UI, alongside a cloud execution layer spanning macOS, Windows, and Linux with storage, networking, and VNC. In a company-reported deployment example, Perplexity says two engineers used hundreds of persistent AI agents over two months to build and deploy CobbleDB; it reports median batch-read latency falling from 31.4 ms to 5.60 ms, p99 from 123 ms to 24.2 ms, and at least 20% savings versus DynamoDB.
- Firsthand workflow/context: Riley Brown is exploring a planned 2027 “dumb agent phone” and used GPT6 Astra, Blender, Higsfield, and Codex to create marketing assets; he says Codex turned a generated phone image into a Blender 3D asset in about five minutes. Higsfield then used Seed Dance 2.5 to generate the video from the Blender references.
- Replicable setup and prompt: Install the Higsfield plugin from ChatGPT’s Plugins menu, sign in, and tag it in the agent. Brown’s prompt was: “Please use this plugin … to make a 30 second high quality ad for this phone. Use Blender to get images and videos to pass into the video generator. Please think deeply about this and make it great. watch the videos and make any improvements. Go.”
- Reusable orchestration loop: Codex plans scenes and timing; Blender builds the 3D product and renders views from all directions for consistency; Higsfield generates scenes and video; Codex reviews the footage for the phone shape, screen, and hands, routes fixes back to Higsfield, then assembles the edit with FFmpeg in the Higsfield sandbox and performs final checks.
- Human-in-the-loop iteration and shipping: Brown used a screenshot plus a follow-up prompt to keep the beginning and music unchanged, revise the final section and phone UI, and extend the cut to one minute. He then asked Codex to create a landing page embedding the video and requested two 20–30-second UGC ads with different presenters and concrete assistant use cases such as drafting email, replying to texts, homework help, planning, and grocery lists.
- Reported execution speed: Brown says the workflow produced a commercial, two UGC videos, a launch video, and a website in a few hours; he spent another 30 minutes to an hour refining the deliverables, and says the website animation took three additional prompts.
- Claude Cowork and Chat are merging into one Claude: Users can ask a quick question or delegate a longer task such as a report; Claude can continue after the user closes their laptop, ask for clarification when needed, and leave the user with final say. The rollout is planned for Pro and Max users over the following weeks.
- Firsthand workflow signal: @mikeyk says they had used the unified version for several weeks and enjoyed letting Claude decide how to execute the work while they focused on the work itself. @simonw requests that Claude publish Cowork’s tool descriptions alongside its system prompts, which would make the agent’s available tools and behavior easier for developers to inspect.
- Claude product unification: Claude Cowork and Chat are being combined into a single Claude experience to remove the need for users to choose which product to start with; Mikey K. says the unified workflow lets Claude decide how to accomplish the task while the user focuses on the work, and reports using it for several weeks.
- Competitive positioning: Simon Willison says this echoes OpenAI renaming the Codex desktop app to ChatGPT, interpreting both moves as part of a broader race to establish a general-purpose agent.
@ThePrimeagen describes a firsthand, three-hour coding-agent workflow: Fable created the feature, Sol performed a thorough review, Grok ran a simplicity pass that removed unnecessary guardrails and superfluous code, and Sol performed a final contract check. Despite these sequential reviews, the resulting interface was judged “one of the worst” he had seen—an actionable warning that code-quality, simplicity, and contract checks do not replace an explicit interface/UX evaluation stage.
Kent C. Dodds shared a quick demo of using @kodykoala package webhooks with Kody and Raycast; the post provides no configuration steps, model/version details, or productivity results. A video demo is linked.
- OpenRouter announced Union Alpha, a free multimodal model for research, coding, and agentic workflows with a 256K context window and tool calling; OpenRouter characterizes it as offering “frontier-level general-purpose performance.”
- Ben Tossell reported a positive initial firsthand experience with the model and suggested it “sounds like another model,” but provided no concrete workflow, benchmark, or detailed comparison.
- Claude is merging Cowork and chat into one Claude, aiming to carry context across a user's work. The workflow supports handing Claude a question or report, letting it continue after the laptop is closed, answering clarifying questions when needed, and retaining human final approval; rollout to Pro and Max is planned over the next few weeks.
- Boris Cherny reports using the merged experience daily for several weeks and finding it simpler, faster, and more powerful; the rollout is gradual while the team tunes speed and reliability.
- Kody v2026.09.16 adds pluggable secret providers behind a feature flag, allowing agents to connect to password-manager vaults such as 1Password or Bitwarden. Secret placeholders are resolved at fetch time and remain hidden from the model.
- Kent C. Dodds notes that users can opt into the feature from the documentation page; the agent can use the secret without being able to see it.
A post highlights JEV by @typesafeai, reporting that it classified approximately 1,000 emails in about 10 seconds across category, priority, spam, and reply labels. The post recommends watching an accompanying YouTube video.
- Nathan, a LangChain PM, demonstrates middleware for managed deep agents as a way to extend the agent lifecycle around tool calls, LLM interactions, and usage limits; suggested applications include policy enforcement, fault tolerance, logging/analytics, prompt transformation, retries, error handling, rate limits, and guardrails.
- PII guardrail workflow: add built-in PII middleware to the agent’s
middlewareattribute, configureemailas blocked, select redaction, and apply it to input before it reaches the LLM. The middleware detects and redacts the email before the model sees it, causing an email-based lookup to fail; the demo also states the redacted value is not stored in LangSmith. - Tool-audit workflow: create a middleware directory and audit file, use the
wrap_tool_calldecorator, attach the middleware to the agent definition, and log every tool invocation. The example writes to stdout but can be redirected to tracing or performance monitoring. - Start with prebuilt middleware for common controls before implementing custom middleware.
LangChain describes its Paid Media Agent as a Slack-based “Deep Agent” that runs every Monday, reads spend, clicks, and conversions across six ad platforms plus a data warehouse, explains what changed and why, proposes changes, and applies them only after team approval—a concrete pattern for scheduled, multi-source agent workflows with human-in-the-loop execution.
Full engineering breakdown: LangChain Paid Media Agent.
How We Built LangChain’s Paid Media Agent
Key Takeaways
- Treat agents like knowledge workers. The strongest results came from giving the agent a well-designed workspace with a sandbox, software, business context, and clear operating instructions. The system prompt became a map that helped the agent find what it needed without carrying everything in context.
- Use models for judgment and code for consistency. Calculations, source-of-truth rules, and safeguards were better handled in code. That made the agent faster, cheaper, and more reliable, while the model focused on interpreting results and recommending what to do next.
- Design agents around the full workflow. The agent needed to find the right tools, work within clear permissions, and move from analysis to action. That meant proposing campaign changes, routing them through human approval, and verifying that the changes were applied correctly.
- Use abstractions to focus on the agent’s job. Managed Deep Agents (opens in new tab) manages hosting, sandboxes, Slack integration, and schedules, so you can focus on the tools, context, and decision rules that make the agent useful.
For LangChain’s first three years, our sales pipeline grew largely organically, driven by open source, content, YouTube, community, and meetups. In January, we wanted to kickstart our paid advertising program to start connecting with prospects we weren’t reaching organically, such as those in new regions and enterprise decision makers.
We wanted to scale from a largely organic growth engine to five paid channels in just six months. This created new challenges for our small marketing team. We had to keep track of new campaigns launching across channels, different creative and targeting experiments, and a growing volume of performance data to understand and act upon.
In order to scale and optimize, we had some technical hurdles to overcome. Each advertising platform has its own data schema, making it difficult to reconcile performance across channels. Campaign parameters also do not map cleanly to the outcomes we ultimately care about, such as sales inquiries, signups, or content downloads. As our product release cadence as a company accelerated and the number of campaigns grew, keeping track of what was running, what was working, and what to try next became increasingly difficult to manage manually.
We set out to build an agent that could help manage that complexity. It would track new product announcements, draft campaigns, add keywords, test variations, and surface proposed experiments to the team for approval. Over time, it would operate as a continuous learning loop: analyze performance, make a change, observe the outcome, capture what it learned, and apply those insights for future campaigns. Our goal was to make the marketing team more productive while continuously improving campaign performance.
In this post, you’ll learn how our paid media agent works, how it supports the marketing team, and what we learned about agent engineering while building it.
We’ve open-sourced our Paid Media Agent (opens in new tab), so you can use it as a starting point for your own. You can also join GTM Engineering Live: How We Built Our Paid Media Agent (opens in new tab) on September 23 at 11am Pacific. In this webinar, we’ll demo the agent, walk through the code and design decisions, and answer questions about applying these patterns to your own agents.
Key results
- Paid media went from driving 0 to 20% of our marketing pipeline in six months.
- Cost per qualified lead (CPL) fell 30% from June to August, while monthly spend rose about 60%. On LinkedIn, our largest social channel, CPL was 40% lower than it had been in January.
- We saved about $5K per month by bringing analysis and reporting in-house instead of relying on an agency.
- We also optimized the agent itself by moving calculations into code and removing unnecessary model calls, making an early reporting workflow about 40x cheaper and 13x faster, with runtime dropping from 18 minutes to 85 seconds.
What we built
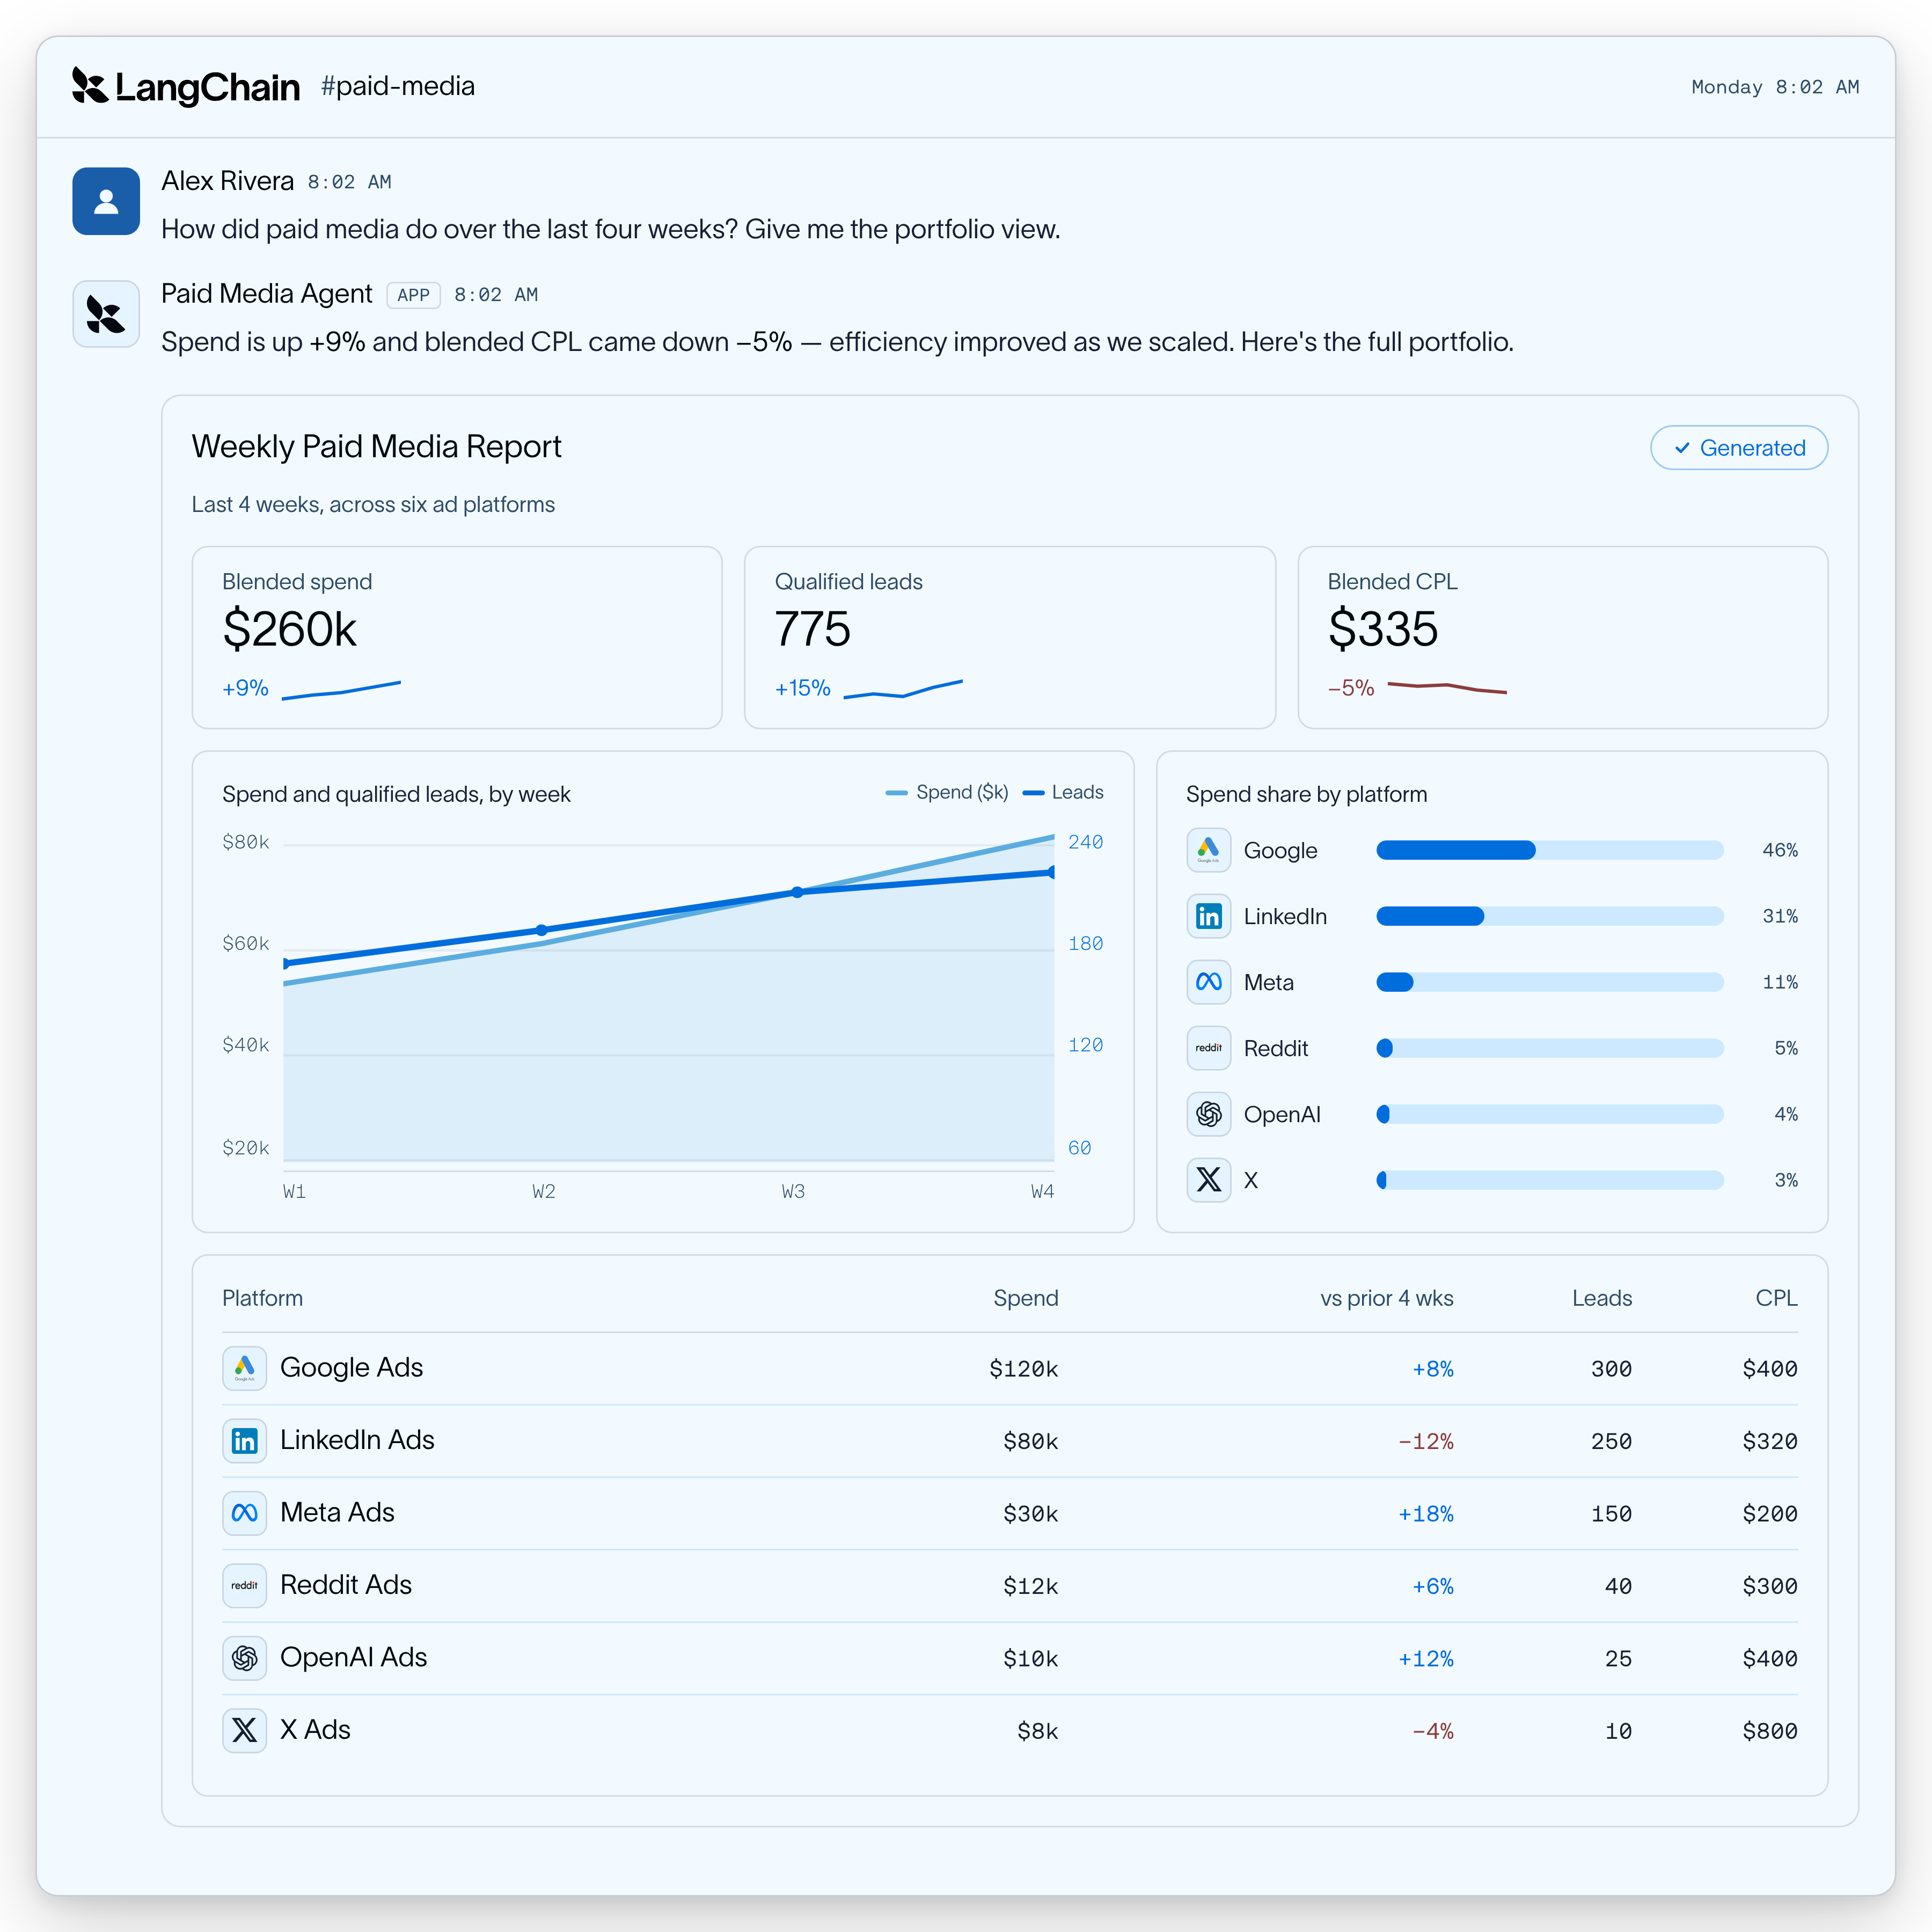
The Paid Media Agent is a long-running agent that lives in Slack. Every Monday, it combines ad-platform data with lead and pipeline from our warehouse. It posts a summary and a branded PDF for each platform explaining what changed, why, and what the team should do next.
The team can tag it in a thread to ask follow-up questions about campaigns, costs, or pipeline. It can also propose new keywords, targeting changes, ad copy, or new search campaigns based on our playbook and encoded judgement.

How we built it
We built this agent around a simple principle: a coding agent is a knowledge worker.
Knowledge work often involves reading files, transforming information, running analyses, and writing things down. A coding agent also does these tasks with files and a shell.
We treated the agent like a new paid-media analyst. We gave it a computer, the software it needed to do the job, access to our data, and documentation about how our business works.

The Operating System
We used LangChain Deep Agents (opens in new tab) for our agent harness so we didn’t have to build core agent infrastructure from scratch. (opens in new tab) Just like an operating system, Deep Agents manages access to files, code execution, and working memory. It gives the model tools to plan work, delegate tasks to subagents, and manage context as tasks become more complex. This foundation is the agent harness. We layer our paid-media tools, skills, and business knowledge on top.
The Computer
Every run has a LangSmith Sandbox (opens in new tab) available by default. It’s an isolated microVM with a 32 GB disk and a shell for running commands. The sandbox gives the agent a safe, isolated environment to execute code and work with files without affecting other runs or the underlying system.
We equip it with pandas and DuckDB for analysis, openpyxl for spreadsheets, and WeasyPrint and Jinja2 for generating reports. Alongside that software are its working data and business knowledge, stored in Markdown across six skills and a nineteen-page wiki.
To keep startup fast, we bake the software and business wiki into a snapshot, a saved image that the sandbox starts from. This reduced the average startup time by 10 seconds.
💡 Different agents need different computers. Our content generation agent’s sandbox looks more like a video editing workstation, with a headless browser, ffmpeg, media tools, and a brand book. A finance agent might need openpyxl for spreadsheets and DuckDB for heavier data processing. The job determines how you design the computer.
Providing the right context
Once the agent had a computer, the next challenge was giving it the right context. A human analyst needs to understand their role, the methods they use, the company they work for, what is happening right now, and the rules they need to follow.
The naive approach is to put all of that in the system prompt. However, that would lead to a prompt that is overly long, expensive to carry into every run, and likely to go stale.
A better way to think about the problem is that the context window is often the bottleneck, not the model. Many apparent reasoning failures are actually context failures. Either the model is missing the right information, or too much irrelevant information is competing for its attention.
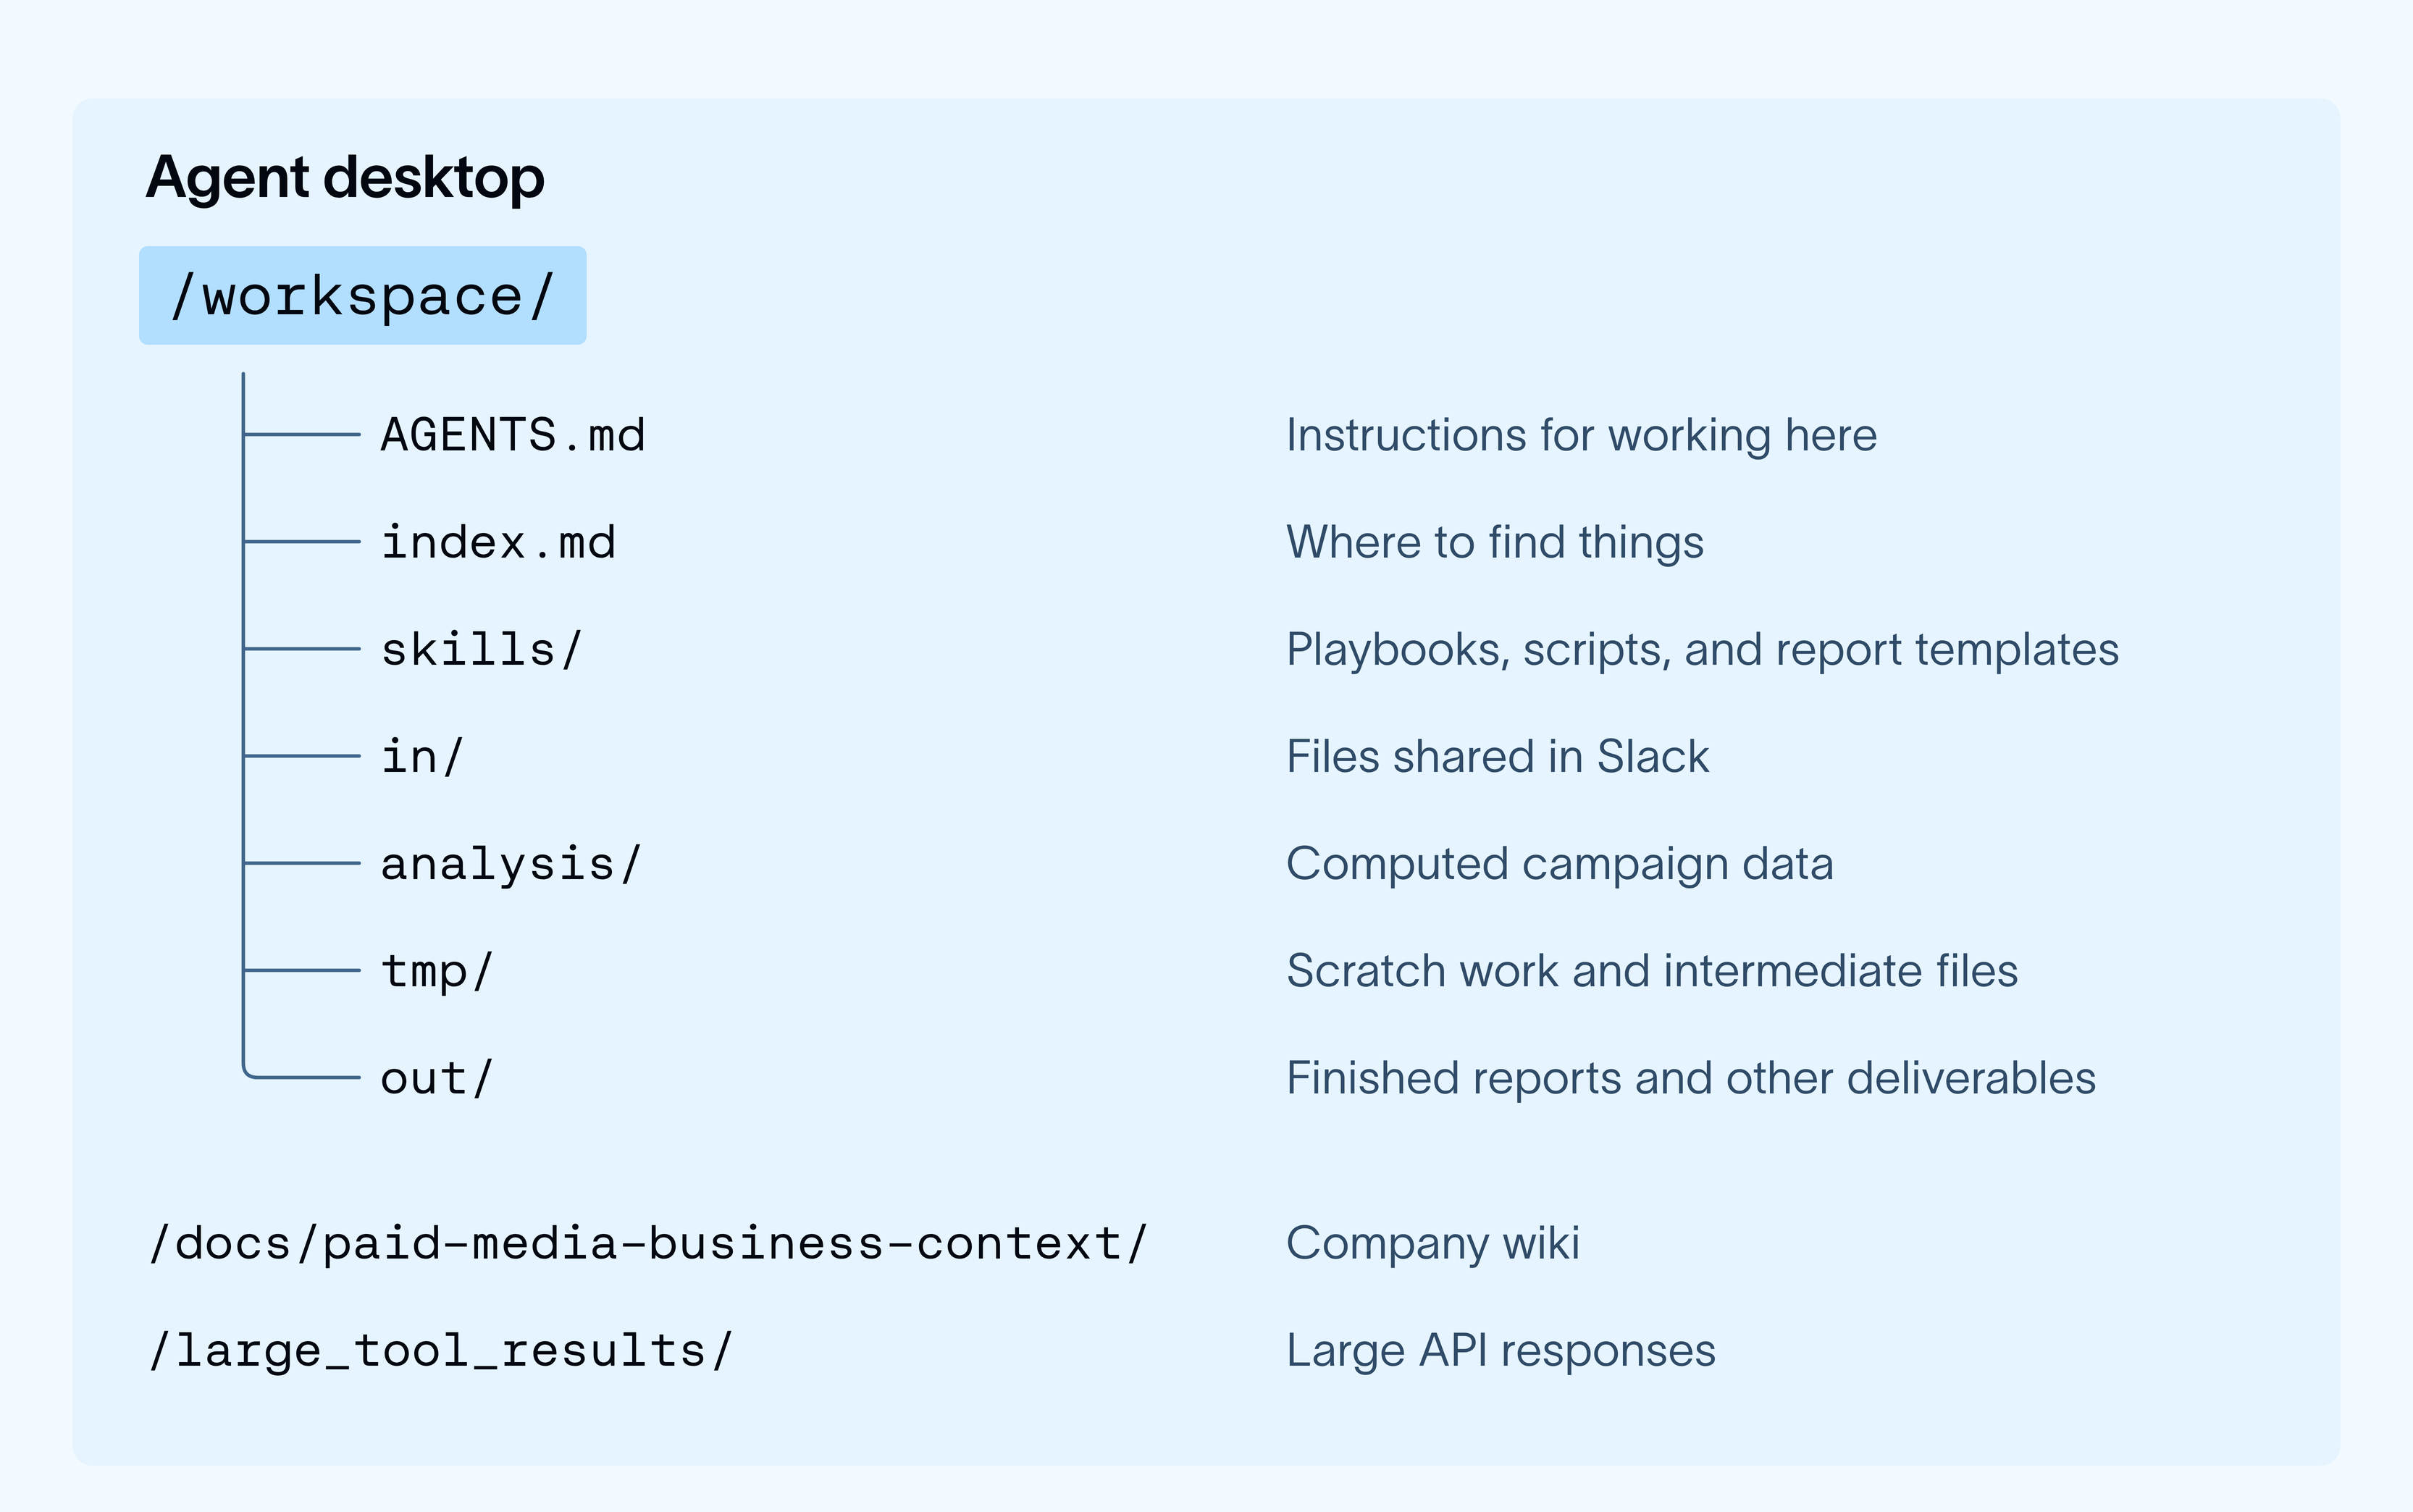
Instead of treating the prompt as the place where knowledge lives, we treat it as a map. Knowledge lives in structured files with predictable locations, and the agent loads only the context required for the task at hand.

💡 The way you design the agent’s workspace deserves as much thought as the tools you give it. We found that the agent could answer questions we had never built explicit workflows for by combining what was already on its desktop. It had a playbook to guide the investigation, campaign data to work with, and libraries to analyze it. Designing that workspace became part of designing the agent itself.
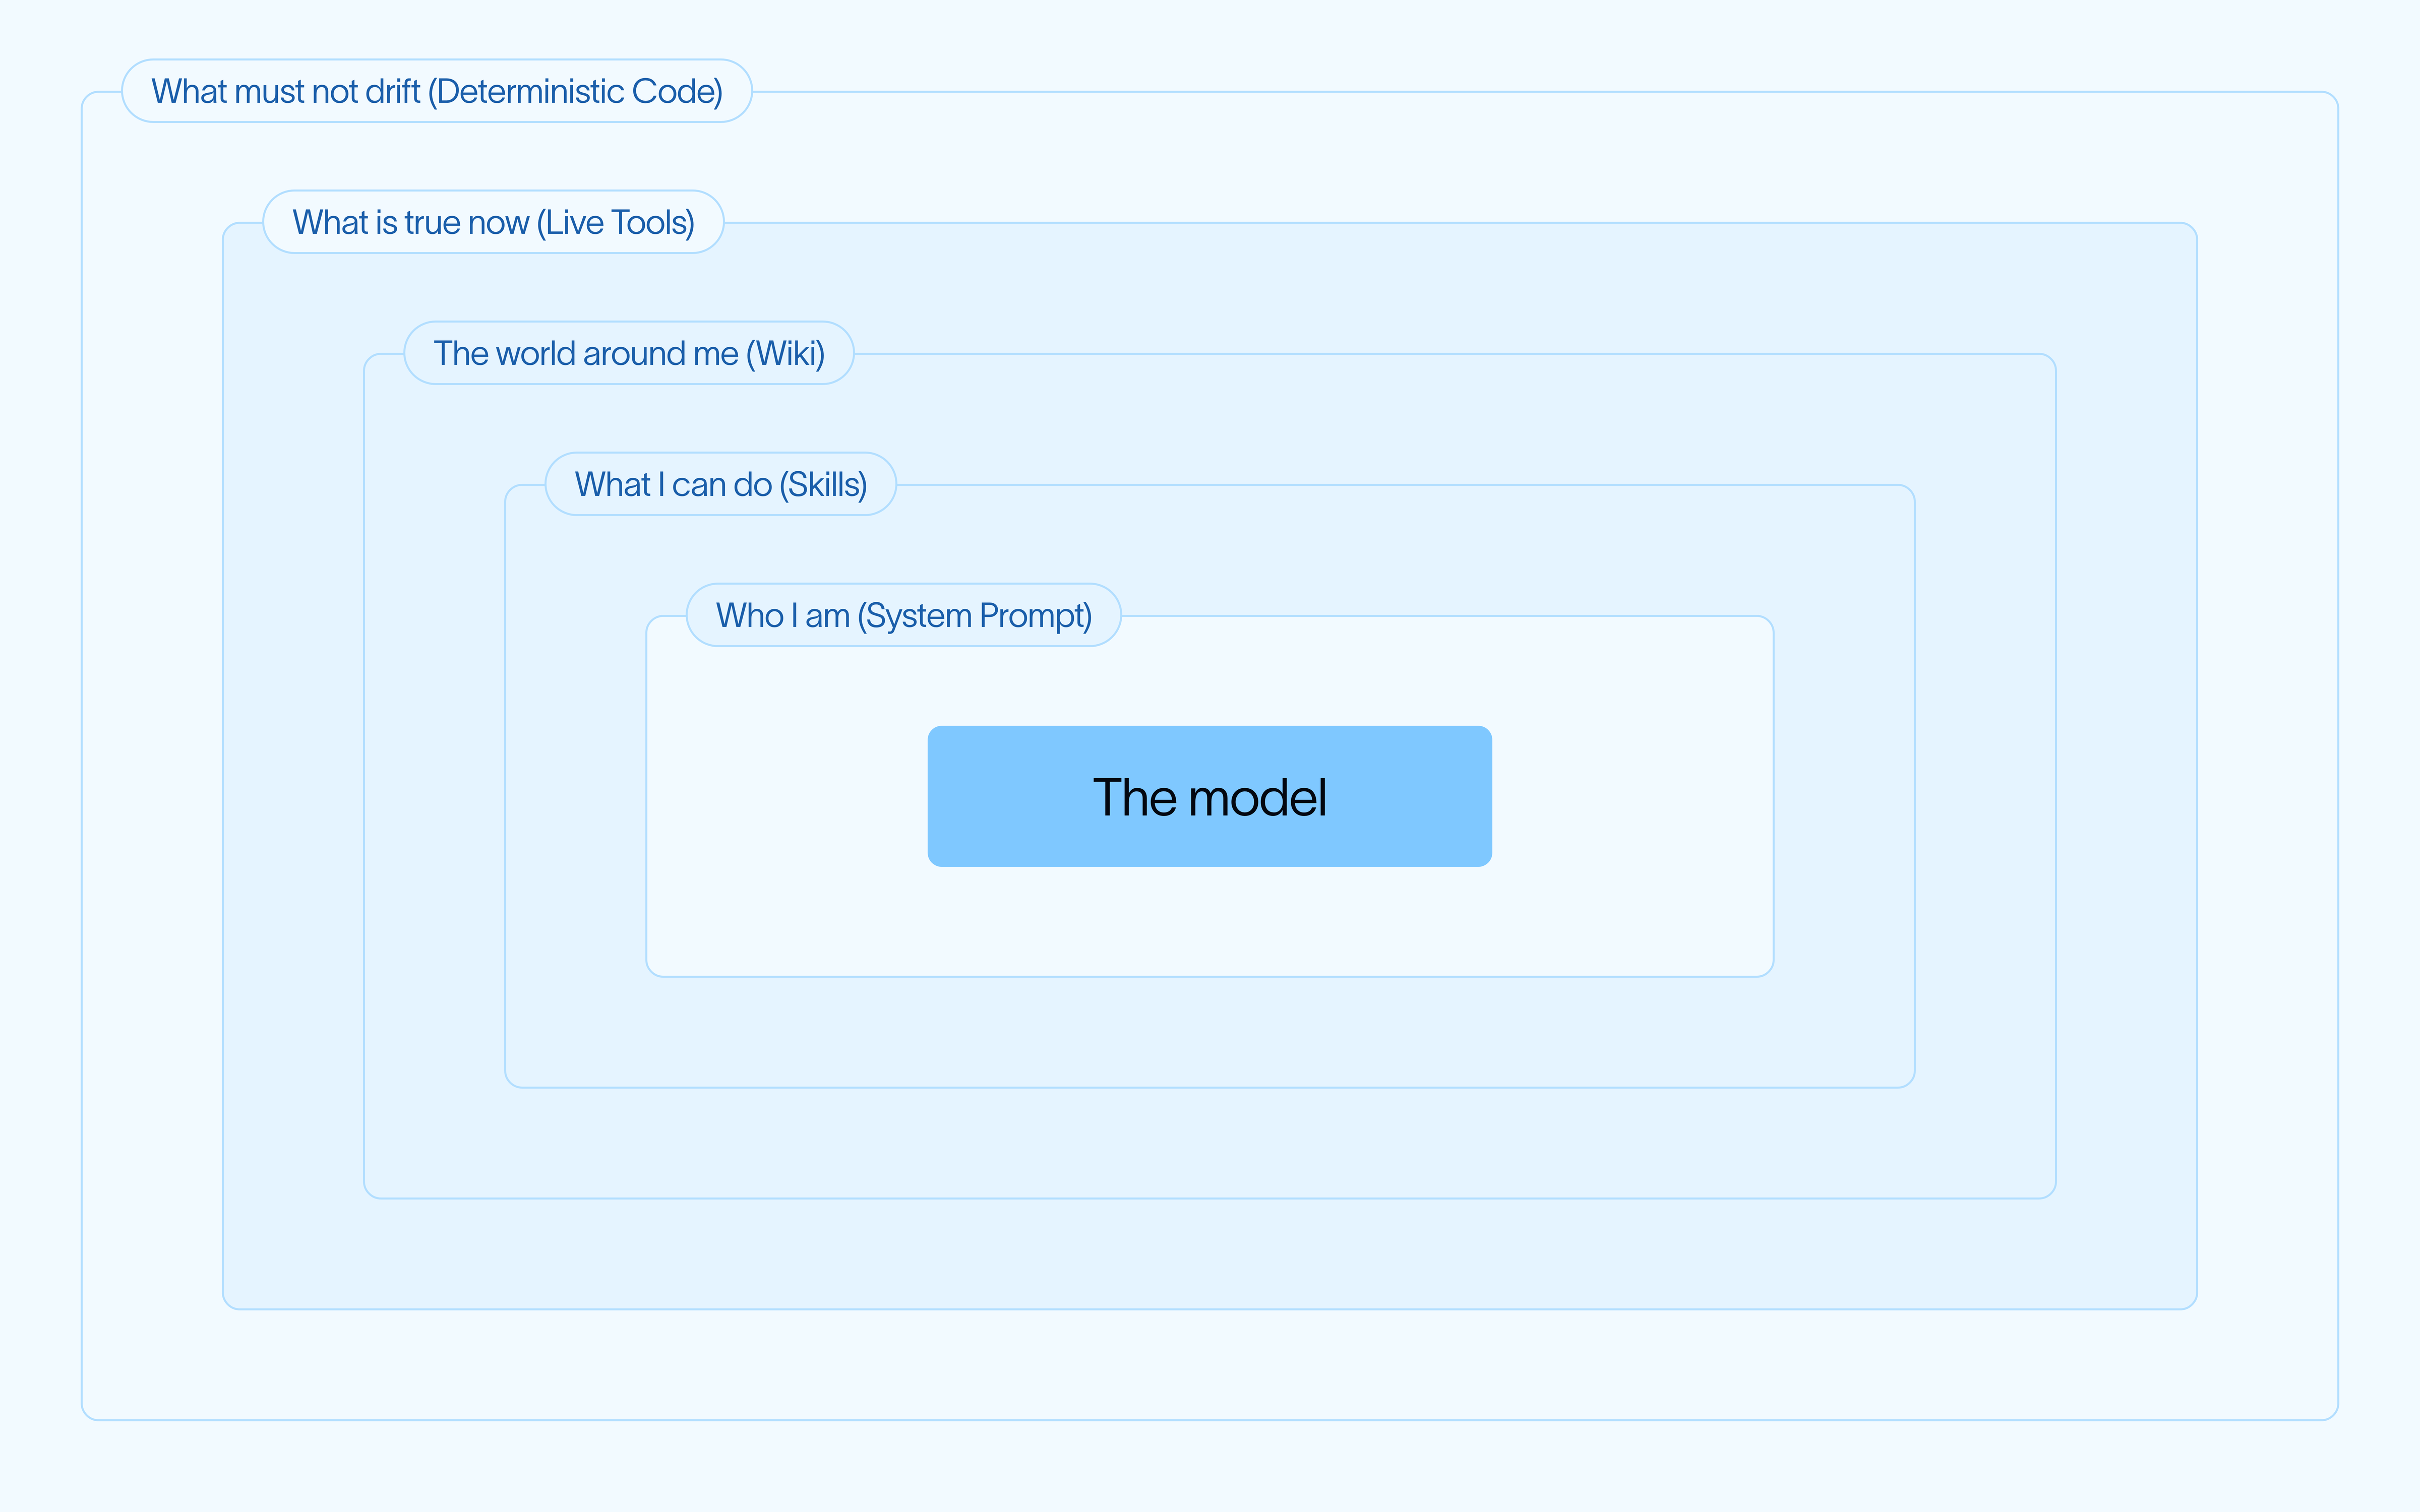
We split context into five layers, and describe each below (ordered by how quickly each one changes):
- System prompt: Defines the agent’s role and navigation. Ours starts with a one-sentence description of the agent’s role, followed by three short sections: how to operate, where numbers come from, and how to present results. Everything else is a pointer for the agent, e.g. the playbook lives here, the wiki there, read the index first. The prompt tells the agent where to find what it needs.
- Skills: Six folders of instructions that are progressively disclosed at runtime. The agent initially sees only the title and description for each.
- Wiki: Nineteen pages explaining how our funnel works, what each campaign is intended to accomplish, which data source owns which number, and what decisions the team has made and why.
- Live tools: Spend, settings, and pipeline change daily, so the agent fetches them at request time. We have 218 such calls. More on how we keep that from bloating context below.
- Deterministic code: We use code for anything that should be consistent and reproducible, including calculations, date windows, account matching, and hard safeguards. For example, a rule preventing the agent from cutting a top pipeline driver after one bad week is enforced in code, so the model cannot override it. The hardest line to draw is between skills and the wiki. A skill explains how to do the work: read the data, run the numbers, write the report, prepare a change, and apply the playbook for interpreting paid-media performance. It contains nothing specific to our campaigns.

The wiki is everything specific to LangChain: which campaign is for awareness, which should drive demo requests, what we decided in July, and why.
💡 A skill should ‘work at another company’, whereas the wiki should not. In other words, skills capture reusable ways of working, while the wiki contains the company-specific context those skills need to operate.
This follows the pattern from Karpathy’s LLM wiki (opens in new tab) note and our own Wiki Memory (opens in new tab).
Unifying the agent architecture
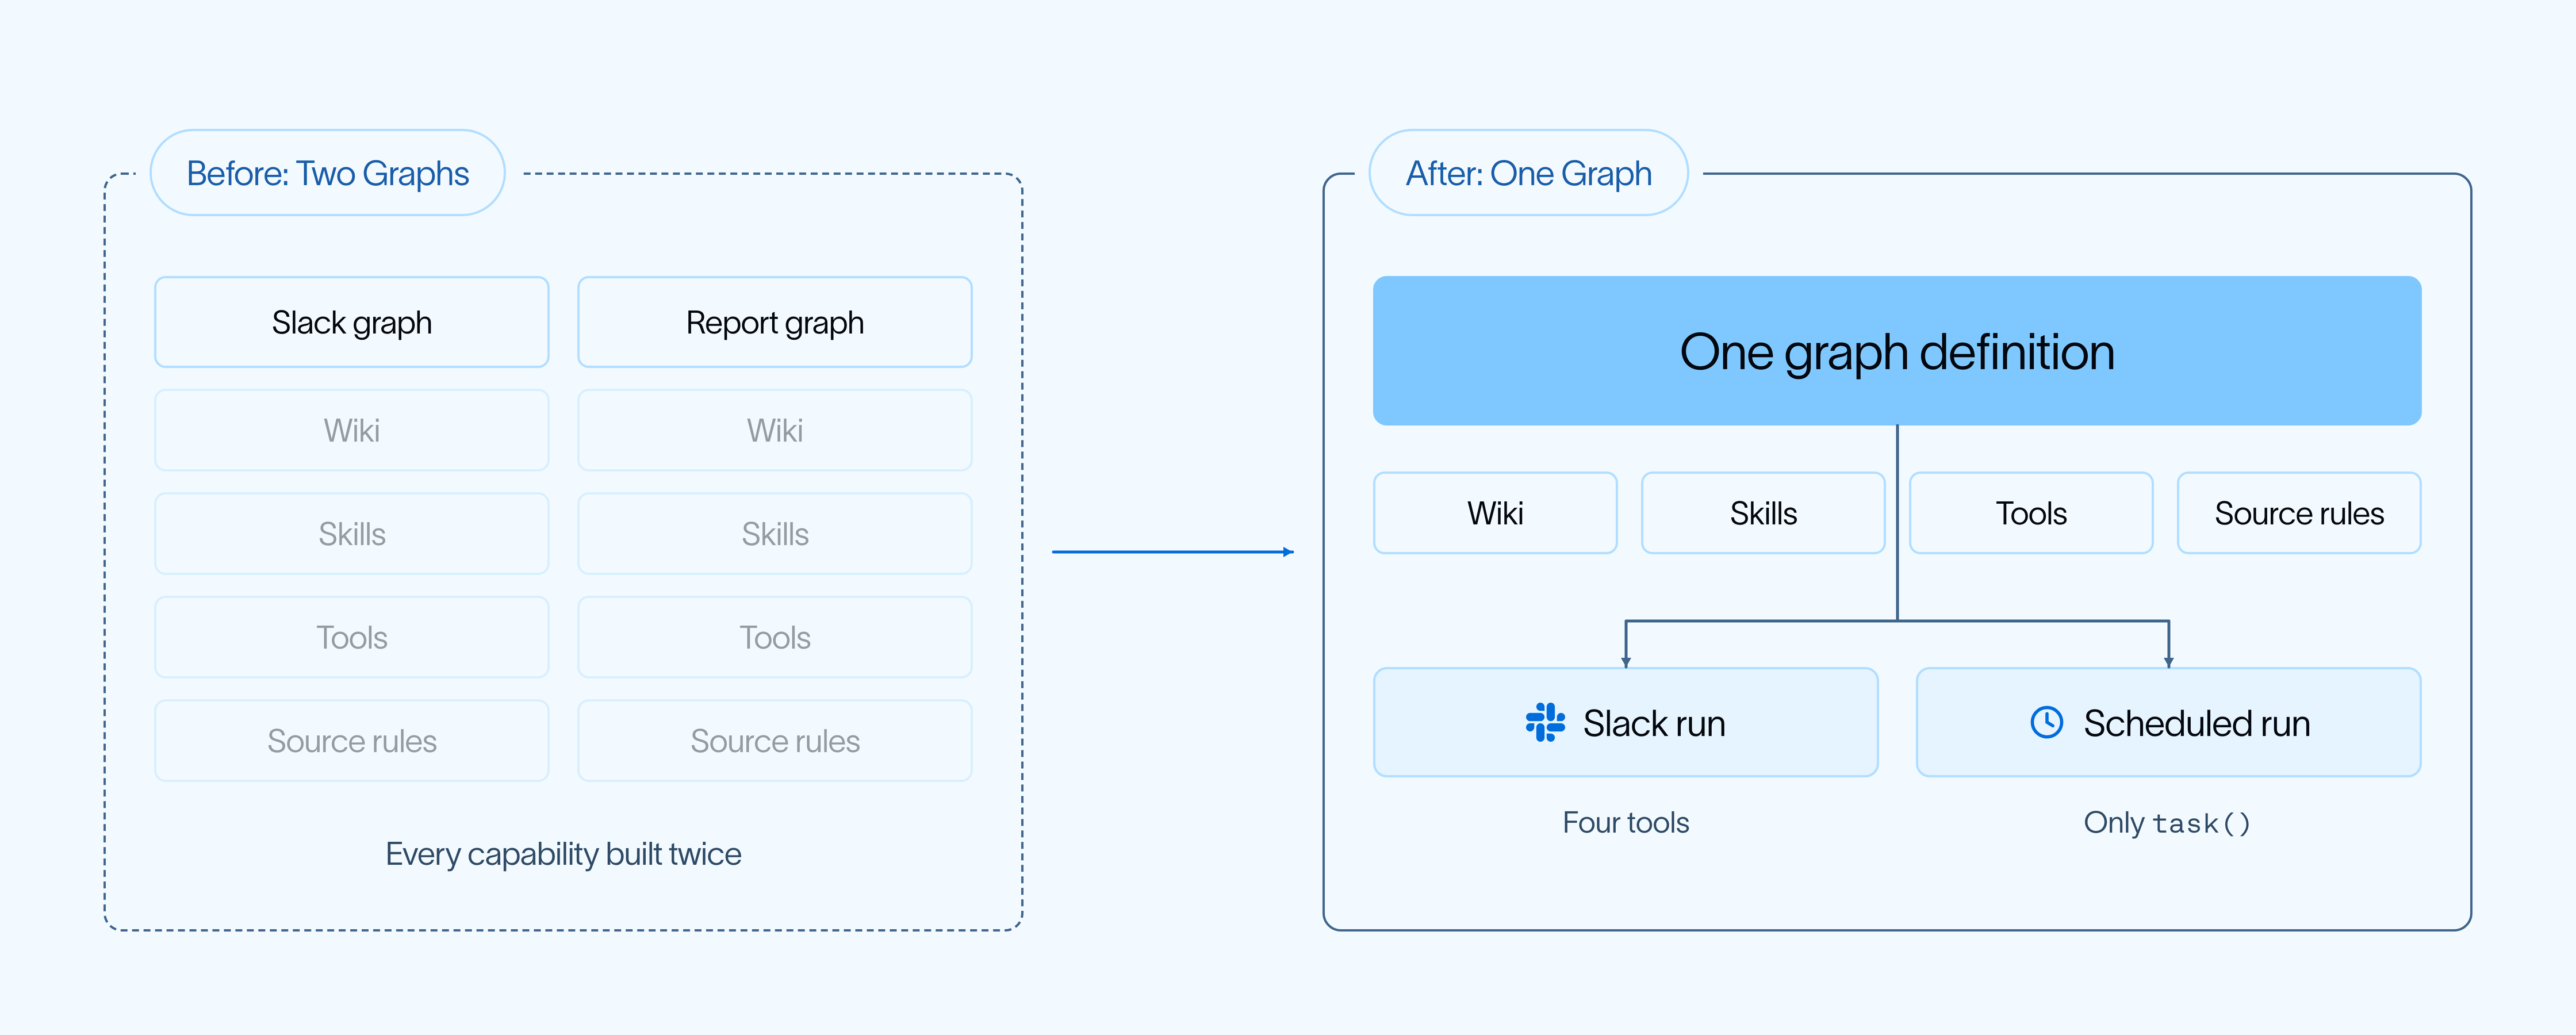
We originally built two agent graphs because the user experiences looked different:
- The weekly report agent was scheduled and artifact-heavy. It used a Deep Agent, sandbox, large model, and PDF generation.
- Slack needed answers in seconds, so it used a lightweight loop on a cheaper model, with Google Ads and warehouse tools, no sandbox, and read-only access.
That split only lasted five weeks. Every new capability had to be implemented twice. Features reached Slack and the report at different times. Slack could not process attachments because it had no sandbox, and it could not answer follow-ups on Monday reports because those PDFs came from another graph.
The mistake was treating them as two products. They are two entry points into the same analysis, backed by the same wiki, skills, tools, and source rules. We instead isolate state and capabilities for each request. Each thread gets its own sandbox and checkpoint, and each run sees only the tools it needs.
Now there is one graph, instantiated fresh for every request:
- Slack mentions and the Monday cron enter with different run modes.
- Scheduled runs see a single tool, task(), which delegates to one subagent per platform.
-
Slack gets a broader set of read, warehouse, and campaign-operations tools.

It is the same runtime with different capability profiles, hosted on LangSmith Deployment, (opens in new tab) which handles hosting, scaling and scheduled runs. And because Slack now shares the same sandboxed architecture, the agent can also open a report PDF and answer follow-up questions in the thread that produced it.
💡 The takeaway: Use one runtime with a capability profile for each entry point. The same factory can give different users different skills and permissions.

Key technical lessons
Putting the agent to work taught us five lessons about getting the numbers right, answering questions we had not anticipated, and turning analysis into action.
1. Use the model for judgement, not computation
Our first version of the weekly analysis asked the model to do everything. We loaded every campaign row, keyword, pipeline record, and landing-page check into context, then asked it to calculate spend, week-over-week changes, classify campaign performance, and write the report.
It worked, but inefficiently. On our frozen test set, a single report processed about 3.9 million input tokens because the model had to read all of that raw data and repeatedly work through calculations itself. That made each run slower and more expensive, taking 1,112 seconds and costing just over $3. It also made the results harder to trust because the model was responsible for recomputing the underlying numbers every time.
We found that code was better suited for deterministic work. Python now fetches the data, aligns date windows, calculates totals and comparisons, applies fixed rules, and writes a compact set of results to the sandbox. The model then focuses on the work that requires judgment: connecting the evidence, explaining likely causes, evaluating campaigns against their goals, and recommending what to do next.
2. Define a source of truth for each metric
We had six platforms with different IDs, conversion definitions, attribution windows, and campaign hierarchies. Trying to normalize everything into one perfect schema would have added complexity without necessarily making the data more trustworthy.
Instead, we defined which system should be trusted for each type of metric. The ad platforms are the source of truth for media activity such as spend, impressions, and clicks. Once someone converts, we rely on our warehouse for downstream outcomes such as leads, opportunities, and pipeline.
We learned why this mattered when some Google video campaigns did not map cleanly into our warehouse. Our warehouse joined campaign data using keywords, but video campaigns do not always have keywords. As a result, about 10% of Google spend was missing from our warehouse even though Google itself had the correct spend data. Meta had the opposite limitation: it could tell us that an ad generated a conversion, but our warehouse was better at telling us what that conversion actually was, such as a “Contact Sales” request versus a “Sign Up.” Those examples reinforced why we should not expect one system to have the best answer for every metric.
We encoded those source-of-truth rules into the agent. They live in the wiki, and we remove tools that would let the agent query the wrong system for a given metric. With the source boundary, conversion mapping, and campaign hierarchy defined, the agent can work across platforms without requiring one perfectly normalized schema.
When data cannot be joined reliably, the agent does not try to fill in the gaps. It preserves those limitations and includes the relevant source, date window, and attribution model in its answers so the team can understand how each number was derived.
💡 The takeaway: You do not need one perfect data model before an agent can work across systems. What matters more is defining which source is authoritative for each metric, making those rules explicit, and preserving uncertainty when the underlying data cannot be reconciled cleanly.
3. Let the agent discover tools instead of loading everything upfront
Answering a question like “What pipeline did we get for our ad spend?” requires access to two systems. Ad platforms provide spend and clicks, while our BigQuery warehouse connects campaign activity and website conversions to qualified leads, Salesforce opportunities, and pipeline.
We wanted the agent to work across both without loading hundreds of tool definitions or writing a new tool for every question.
Pipeboard’s MCP (opens in new tab) exposes more than 200 ad-platform tools. Back in June, even our smaller read-only catalog required 38,000 tokens just to load the available tool names, descriptions, and arguments before the agent had read the user’s question. Most of that context was irrelevant to any individual request.
Our warehouse had a related problem. We had built fixed queries for recurring questions like pipeline by campaign or conversions by ad group. But each new way of grouping the data, such as pipeline by individual sales opportunity, required another dedicated tool.
We solved both problems by giving the agent a small interface for finding what it needs.
Pipeboard’s catalog sits behind three tools:
- Search: Finds up to eight tools based on the question.
- Read: Loads the full schema only for the selected tool.
- Run: Executes that tool through our server. Campaign writes use a separate approval-gated path.

For the warehouse, we added two flexible tools:
- Describe the available tables and fields.
- Run an analytical query.
The agent can inspect the schema and compose the query required for the question instead of depending on a prebuilt tool for every possible grouping.
The catalog brought the first turn down to about 12,000 tokens. In our comparison, it was 4x cheaper than loading every schema while maintaining the same judged quality. The catalog has nearly tripled since then, while its context cost has stayed roughly consistent.
We tested fixed warehouse tools, the query interface, and both together across 60 live runs. Fixed tools worked well for routine questions but correctly reported deeper questions as unsupported. Both versions with the query interface answered all the analytical questions.
We kept both approaches. Fixed tools provide a fast path for common questions, while the query interface handles questions we did not anticipate.
💡 The takeaway: Give the agent a way to find and query capabilities on demand instead of putting every tool into context upfront.
4. Design isolation explicitly
Once we moved to a shared runtime, we had another challenge: how could the agent analyze five platforms without putting every platform’s data into one context window?
We tested three architectures on live data:
- One isolated run per platform.
- One agent handling every platform.
- A parent agent delegating to one subagent per platform.
Separate runs were the simplest architecture, but they performed worst for the actual workflow. Each run saw only one platform, so the system produced multiple Slack messages and struggled to synthesize performance across channels.
Both consolidated approaches produced a single output with cross-platform synthesis. We ultimately chose the parent-plus-subagents architecture because it kept the parent’s context small while giving each platform its own context window for platform-specific data and caveats.
But separate context windows did not automatically give us full isolation. We still had to design it.
For example:
- One platform could accidentally suppress another. Two subagents were writing reports to the same location and sharing the same “done” flag. Once the first finished, the second could mistake that state for its own and stop without producing a report. We fixed this by giving each platform its own report location and completion state.
- A subagent could get stuck trying to verify its own work. When one subagent could not determine whether its PDF had rendered, it kept checking files, burned a ton of tokens, and eventually tried to build the PDF from scratch. Subagents now get only three tools: read context, compute, and render. If render succeeds, the job is done.
A subagent gives you a separate context window. The rest of the isolation model is up to you. You still need to define which tools it can use, what files and state it can access, what it must return, and how failures are handled.
5. Give the agent a path from analysis to action
An agent that only analyzes performance is ultimately a better dashboard. We wanted the agent to help the team act on what it found.
It can propose changes directly in Slack, such as adding a keyword, updating geographic targeting, or creating a new search campaign.
Giving the agent the ability to take action also introduced a new requirement: permissions.
Teams outside paid media can use the agent to ask questions about campaign performance and pipeline, but only designated team members can edit or approve campaign changes. The server checks Slack user IDs before accepting either action. Requests from anyone else are blocked, and the proposal remains pending.
Each proposed change appears in a Slack approval card built with Block Kit. Authorized reviewers can compare the current and proposed values, make edits, and approve the final plan. Code then applies the approved change and checks the ad platform to confirm it succeeded.

This gave us a useful separation of responsibilities. The agent can analyze performance and recommend an action, but a human controls whether that action is actually taken.
💡 The takeaway: Closing the loop requires more than write access. Give the agent a clear action path with permissions, approvals, and verification built in.
6. Match the interface to the work
Slack worked well as the first interface because the approval card could live in the same thread as the analysis and discussion that led to it. People across teams could ask questions and weigh in, while campaign owners still controlled which changes were actually applied.
That approach works best for relatively focused decisions. As the agent started handling more complex work, such as campaigns with many ad groups and creatives, bulk edits, or plans that needed several rounds of revision, Slack became harder to use as the primary workspace.
We are moving those more complex workflows into a dedicated interface built around the agent, while keeping Slack as a lightweight place to ask questions, review recommendations, and approve changes. More on that in a future post.
What we’d take into the next build
We wanted an agent that could handle questions we hadn’t anticipated, produce numbers we could verify, and act on what it found. These are the design principles we would carry into another agent:
- Equip the agent like a hire. Give it a sandbox, useful libraries, access to the right data, and clear documentation. A well-designed workspace lets the agent investigate new questions without requiring a dedicated workflow for each one.
- Separate reusable instructions from company knowledge. Skills explain how to do the work, the wiki explains the business, and live tools provide current information. Keeping those layers separate makes each one easier to update without growing the system prompt.
- Use code for work that should be reproducible. Calculations, comparisons, and hard rules belong in code. The model can then focus on interpreting the results and deciding what they mean.
- Design boundaries explicitly. Subagents still need clear rules around which tools, files, and state they can access, what they should return, and how failures are handled. A separate context window is only one part of isolation.
- Optimize for whether the agent can finish the job. Reducing tokens, cost, and latency matters, but not if it makes the agent less capable. We found it more useful to evaluate those metrics alongside completion rate and answer quality.
- Let real usage show you where integrations need improvement. The questions the agent repeatedly struggles to answer reveal where cleaner joins, better definitions, or dedicated tools are worth building.
What’s next
Today, the agent primarily responds to scheduled runs and requests from the team. We want it to become more proactive by continuously monitoring campaign performance, surfacing changes that deserve attention, and proposing new experiments and optimizations for the team to review.
The bigger opportunity is to connect those learnings across GTM. Campaign engagement can inform how sales follows up, while pipeline progression, sales conversations, and deal outcomes can improve our understanding of the ideal customer and influence the next campaign.
Over time, we want our GTM agents to contribute to the same shared knowledge and playbooks so that what one part of the organization learns can improve targeting, messaging, and experimentation across the rest of the funnel.
Build on what we learned
Join GTM Engineering Live: How We Built Our Paid Media Agent (opens in new tab) on September 23 at 11am Pacific. In this webinar, we’ll demo the agent, walk through the code and design decisions, and answer questions about applying these patterns to your own agents.
You can also bring this paid media agent to your own team. We’ve open sourced (opens in new tab) it, including the ad-platform tools, paid media skills, a sample wiki, reporting, and approval workflows. Connect your accounts, give it your company’s context, and deploy it to Slack in one command with Managed Deep Agents (opens in new tab).
Direct answer
LangChain’s production Paid Media Agent is one request-scoped graph hosted on LangSmith Deployment, with different capability profiles for Monday scheduled runs and Slack interactions. Scheduled work delegates to one subagent per advertising platform; Slack receives broader read, warehouse, and campaign-operations tools. Each request gets its own sandbox and checkpoint.
Data sources and tool access
- Every Monday, the agent combines advertising-platform data with lead and pipeline data from LangChain’s warehouse, then produces a summary and branded PDF for each platform.
- The source-of-truth boundary is explicit: ad platforms own media-activity metrics such as spend, impressions, and clicks; the warehouse owns downstream outcomes such as leads, opportunities, and pipeline. The agent preserves source, date-window, and attribution limitations when data cannot be joined reliably.
- The warehouse is BigQuery-based and connects campaign activity and website conversions to qualified leads, Salesforce opportunities, and pipeline.
- Rather than load the full ad-tool catalog, the agent uses Pipeboard’s MCP through Search (find up to eight relevant tools), Read (load the selected schema), and Run (execute it); campaign writes use a separate approval-gated path. For the warehouse, it can describe tables/fields and run analytical queries.
- The broader runtime also has live tools for changing spend, settings, and pipeline data, with 218 such calls described in the article; reusable instructions live in six skills, while company-specific campaign and metric knowledge lives in a 19-page wiki.
Scheduling and execution environment
-
LangSmith Deployment handles hosting, scaling, and scheduled runs. A Monday cron and Slack mentions enter the same graph with different run modes; scheduled runs expose a single
task()tool that delegates to one platform subagent. - Each run has an isolated LangSmith Sandbox: a microVM with a 32 GB disk and shell. The production image includes pandas, DuckDB, openpyxl, WeasyPrint, and Jinja2, plus the working data and business knowledge; a prebuilt snapshot reduces startup time.
- Platform subagents receive separate context windows, report locations, and completion state. In the reported implementation, subagents are restricted to three tools—read context, compute, and render—so successful rendering terminates the job rather than triggering repeated self-verification.
Analysis versus approved writes
- Deterministic code fetches data, aligns date windows, calculates totals and comparisons, applies fixed rules, and writes compact results to the sandbox; the model interprets evidence, explains causes, evaluates campaigns, and recommends next actions.
- The agent may propose a keyword addition, geographic-targeting update, or new search campaign in Slack, but only designated team members may edit or approve campaign changes. The server checks Slack user IDs and leaves unauthorized requests pending.
- Approved proposals appear as Slack Block Kit approval cards showing current and proposed values. Authorized reviewers can edit and approve the final plan; code then applies the approved change and checks the ad platform to verify success. This creates a human-controlled boundary between analysis/recommendation and execution.
Code and study materials
- LangChain open-sourced the Paid Media Agent at https://github.com/langchain-ai/open-paid-media-agent. The repository includes ad-platform tools, paid-media skills, a sample wiki, reporting, and approval workflows. The article says practitioners can connect their accounts, provide company context, and deploy it to Slack in one command with Managed Deep Agents.