Last year, Alex Lieberman and his cofounder joined us (opens in new tab) to explain Tenex’s unusual bet: pay AI engineers for the work they deliver, rather than the hours they spend at a keyboard. If AI makes an engineer faster, an hourly rate can make the engineer less money for the same job. Tenex wanted the incentives to run the other way.
At AIE New York, Alex came back with CJ Hess to talk about what happens when you scale that idea into an engineering organization. We also put one of our own experiments on the table: Kill My SaaS (opens in new tab), where we asked builders to replace a conference speaker-management tool we were quoted \$43,000 a year to use.
Both stories raise the same question: when building gets cheaper, how do you decide what good work is worth?
Paying for output when the job keeps changing
Tenex still uses story points as an important part of engineering compensation. Alex says the feared failure modes—people inflating estimates or shipping bad code to rack up points—haven’t been the biggest problem. Tenex’s AI strategists are responsible for customer retention and growth, giving them an incentive to push back on work that doesn’t serve the client.
The harder question is how to reward work that doesn’t fit neatly into a ticket: understanding a customer’s problem, designing an architecture, or deciding what should be built in the first place. CJ describes spending less time directly coding as models get better, and more time getting the customer’s context into a form the model can use. A compensation system designed around shipped tasks has to make room for that work too.
Alex says Tenex has grown to 75 people, with customers split between Fortune 2000 companies and mid-market businesses. The firm started as an AI-powered development shop; increasingly, customers are asking for help with AI transformation across the company. Jump to the compensation discussion → (opens in new tab)
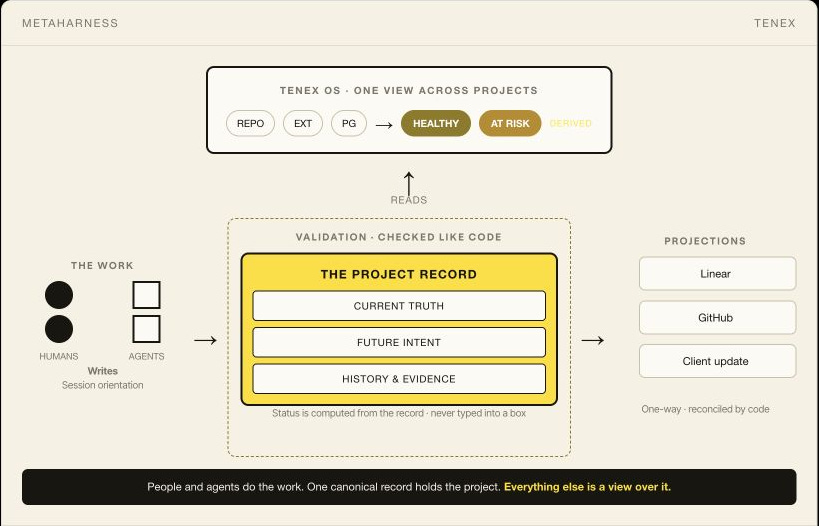
MetaHarness: keeping the project in the repo
CJ walks through Tenex’s MetaHarness: a shared set of skills, project documents and a CLI around the work. Plans and decisions are checked into Git alongside the code. When an agent comes back to a task, it can read not just what was built, but why the team chose to build it that way.
The useful distinction is between making agents write code faster and making the surrounding work legible: the plan, acceptance criteria, decisions and evidence. Tenex’s article also notes the cost: that much structure can be overkill for a small team on one project. CJ explains the workflow → (opens in new tab)
Kill My SaaS: the cost of owning the thing you build
Our Kill My SaaS episode (opens in new tab) covered 72 submissions to replace our speaker-management software. The team that won with our human judges came 19th on our AI judge’s leaderboard. It was a useful reminder that checking whether software satisfies a list of scenarios and judging whether people want to use it are different jobs.
I brought the project to Alex as a real example of a company choosing to build its own software. His pushback: the further upmarket you go, the more expensive and risky it becomes to rip out an established system. And even for a smaller tool, someone has to maintain it. Is the saving big enough to justify that ongoing attention?
My answer is that the upside isn’t just the bill. Our team has lived with a mediocre product for a long time. If we own the workflow, we can make it better for speakers and operators and iterate in minutes instead of waiting months for a vendor. That potential has to be weighed against the maintenance Alex describes. Watch the exchange → (opens in new tab)
The case for—and against—vertical AI
Alex is generally bearish on vertical-specific AI products: if every enterprise expects a one-of-one solution, how do you deliver that at software margins? And as frontier models improve, how much of the underlying task gets absorbed by general-purpose tools?
I pushed back with examples like Harvey and OpenEvidence. Domain-specific data, specialized interfaces, integrations and user habits can matter even when the underlying model is available to everyone. Bloomberg is a useful comparison: a trader can get market data elsewhere, but the terminal brings data, workflows, communication and existing habits together.
CJ draws a distinction between a vertical product whose main feature is an agent performing a task, and a tool that improves the actual workflow around that task. That leaves a more interesting question than whether “vertical AI” wins or loses: which products become a durable place people do their work, and which become a feature of the agent they already use? Watch the debate → (opens in new tab)
Show notes
Timestamps
Transcript
Automatically generated from the interview; wording may contain errors and speakers are not labeled.
0:00 And I just felt my output getting better and faster, and ultimately getting paid less. Like I was charging hourly to my clients. I phrase it to the team as, you can’t automate a process that does not exist.
0:26 Okay, we’re here at AI Engineer checking with Tenex. Welcome back, Alex. Thanks. Thanks for having us. You brought your Director of Engineering, CJ. Welcome to the pod. Special projects lead at Tenex. Okay, special projects lead. All right, you’re the SWAT team. Yes, yes. So you’ve been on the pod before, and people are vaguely familiar with the Tenex story, but can you sort of reintroduce from the top what is the 2026, how you introduce yourself? Yeah, very simply, Tenex is an applied AI partner for some of the biggest companies in the world to help them go from AI absent to AI native. Our belief is that AI is incredible, but it is raw intelligence.
1:04 And the hardest problem to solve is the final mile to actually diffuse it through the economy. And so our view is to act as the player to help enterprises to figure all of this. Can I curse on? To figure all this shit out. Yeah, yeah. Yeah, we have the explicit tag on Apple Podcasts. Although I did recently discover that YouTube doesn’t like it. Oh, really? They’re so, like, yeah, you can’t say the F word. So did I just mess up your video? What are you going to do? I don’t care. Okay. We’re for adults. CJ, what drew you to Tenex? So I was actually the first hire. I don’t even know if Alex and Armand had the name Tenex quite yet,
1:40 but I have, like, a graveyard of startups I tried to start before Tenex, ultimately culminating in like my own kind of engineering consulting company. And I spent some time there doing traditional engineering, eventually moved over to doing some of this like AI consulting and just like building more and more with it. I’m a software engineer by trade. And I just felt my output getting better and faster and ultimately getting paid less. Like I was charging hourly to my clients. and I really liked kind of the ethos of Tenex that Alex had first posted
2:16 when I saw it on Twitter about kind of looking to reward engineers for their output as opposed to rewarding them for their time. I think you know fast forwarding two years you can see like how engineers can now parallelize a ton of work and just have a ton more output. At the time with you know Sonnet 3.5, Gemini 2.5 Pro, it might not have been that obvious, but I basically took the bet that I think with my skill set and leaning more into AI, I could have much higher output and ultimately have like a higher earning capacity to do that.
2:53 And since then I’ve just like fell in love with that model. I think that’s like what the future of engineering really looks like. And ultimately when AI is solving all these tech problems, companies are gonna pay based on outcome and they’re not going to want to pay based on the time that’s required to build something. Yeah. So for more detail on that, people can refer back to our previous pod where you literally pay people by story points. Yep. And you just have to agree what the story points are. But that also means that some 10x engineers can literally make millions of dollars a year and some others may not make as much just because they’re not as productive. Yeah, exactly. The thesis is that AI is really just a leveraged bet on a human’s intellect
3:29 and work ethic. And so you’re just going to have more variance than ever before in earning capacity. and our view is our model isn’t for everyone, but for the person who basically wants to go long themselves, who has this incredible foundation in software engineering, but also is constantly pushing themselves to leverage the frontier, to stretch their time as much as possible while having quality output, there’s no better way to earn. What’s the state of, like last time I talked to you, I think you had maybe two or three people making a million a year or over a million a year. Is there an update on that? Yeah, yeah, yeah. So just to paint a picture,
4:05 we started Tenex 18 months ago when we started the business. Really, we started as like an AI-powered dev shop. Really, like the original idea was engineering is kind of like the canary in the coal mine for AI. And part of the impetus was my co-founder, Armand, who’s technical by trade, was like starting to use coding agents a lot. And then he had some people he knew that were still typing into their ID, like not adopting the technology at all. And so we’re like, why don’t we just supercharge a company’s engineering org who isn’t adopting this? So we started there. Then as we started moving up market from startups and like mid-market
4:42 companies to now, you know, 50% of our customers are Fortune 2000. And then 50% are mid-market doing 100 to 500 million in revenue. They weren’t just asking for basically staff org and AI engineering. They were asking for like AI transformation as a service. Today, the business is at 75 people. 90% of those employees are either engineers or AI strategists, which are basically think of as like technical consultants. And I think the thesis has proved out true, which is there’s a very wide dispersion in earning capacity between the highest paid engineer at Tenex and the lowest paid engineer at
5:20 Tenex. It’s probably something around 4X difference. Oh, not 10X? Not 10X difference, yeah. That’s the dream. Yeah, exactly. but everything is proved right about the thesis. I do think like there’s been interesting learnings around our model of paying based on story points where there are limits to the model that we knew would be limits and how we think about that moving forward. But overall, I think the concerns that people had around this model of like paying people based on output, like the classic concerns are, well, story points are subjective. People are going to either sandbag story points or they’re just going to
5:55 ship a a bunch of bad code. Like barely check the box. Exactly. Right. But not actually do the job. Yeah, exactly. And I would say those two concerns have not been concerns at all because of our AI strategists. We incentivize, I think, perfectly at odds with engineers where AI strategists are incentivized for like customer retention and growth. Actually, the biggest challenge has been how do you compensate engineers for all the time that’s not spent coding, whether it’s architecting, meeting with clients. And so that’s where we’ve had to find nuance in the comp model,
6:30 but it’s still largely driven based on output. Anything to add? Yeah, on that, I spend a lot of time thinking about this because if I think about my tenure at Tenex, I was coding a lot, coding a lot, coding a little less, and now we’re kind of getting to the point where the models are more or less given the right context and can get you to 90% of the solution. and I do think there is some opportunity here to think about like really the value is sitting down with a customer, hearing everything that they can brain dump and then just providing that to the model
7:05 to actually get closer to the solution. So I imagine, you know, in the future, we’re going to start to look more at like true what this output is, how it works, how it looks as opposed to, you know, kind of that traditional story point model but still anchoring to those as the unit. I think one thing you’d also, I don’t know if we’ve talked about this before, but like the, this idea of like the meta harness, which is like the, the engineering workflows at Tenex that we use that has allowed us to do, I think like really meaningful work on long running tasks. Do you want to just talk through like what our process is? Cause I feel like people would find that interesting. Yeah. So we basically started trying to kind of standardize a set of skills.
7:44 Um, I think most engineering orgs have done something similar by this point. Um, and for us that grew into what is actually like a very structured set of documentation within a repo and then a CLI that’s around it that kind of the models are using to actually drive the work that’s being done, whether it’s creating a plan, a visualization, you know, creating some readout for a client, effectively like building all the pieces of the process around actually writing the code to just happen more automatically and standard across our team. So we have a couple of things, Like one is this like big canonical plan document that has some similar
8:20 structure, but I’d say as the models have gotten better, we’ve actually reduced the enforcements there in the structure. Kind of similarly across all of these. But once you have your plan, you actually build it out. And we have a very opinionated way on how agents will go and log their decisions and log what they’re doing and just keep track of what they’re up to. Everything checked into Git. Yeah. All of this is checked in. All of this is really kind of marked down for me now, more HTML. I like to see these picture books that the agents fit out. But all of that gets checked in and then it serves as this surface where not
8:55 only do you have the code as the source, you know, I think there’s a debate on like, do you even need docs? Like the code can actually be the memory of a code base. And I do think you do. You need to know why you made a decision. You need to know the context around the conversation that was had. But ultimately, that plus the code base, if there’s a question, if there’s something we need to answer, if we need to look back on why we did something, we just always have that in some durable record. And it’s never in someone’s head. It’s always in the repo. So that just gives our agents and our tools these superpowers to have all the context that I think a lot of engineering teams still just have in
9:31 conversations or have in their heads. And our goal is to kind of continue to push that forward so that all the context is in one place and more and more of that work is just driven by the agent as opposed to us having to provide everything up front. Yeah, amazing. And one way we even measure, like if any of these kind of like processes are working is are we seeing an increase in trend in average story points per month of every engineer in the company? Right. And what do you think it is, let’s say compared to started this year? I don’t know. What do you think? Do you think… Plus 50? I think, so it really depends, because we have some people that…
10:09 There’s some picture that I saw on Twitter of a guy over a wizard orb, and he’s got these things in the sky. And that’s how I think of some of our engineers when they’re whipping agents around. I’d really say, overall, it’s been a 2x increase, this year in particular. I think, basically, if you think of December as the Opus 4.5 moment where the models really started to take on these long-running tasks to today we’re back to Opus, but Opus 5.5. I mean, that’s just a magnificent model that can really do a ton of work. Over that period, I’ve seen the actual output of engineers, I would say,
10:44 roughly double in terms of what they were able to do to what they’re able to cover in the same time span now. Is a single story point worth the same now as it was a year ago? We’re always trying to calibrate. It’s a tricky equation. Is there inflation or deflation? I mean, in theory, there should be deflation, right? Yeah. Yeah. I don’t know. And that’s roughly how we think about it. I would say at least once a quarter, we kind of sit down and evaluate, like, what is our criteria for these story points? How are we actually estimating these projects? There’s a fine balance to be made between, like, still rewarding this
11:19 output, but also as the models get better, we do need to be able to kind of calibrate, like, the value that we’re creating. so overall I would say roughly that 2x has played a similar role in how we do these estimations but if I just look at some of the features and things people are building and pushing out now versus this time last year, it’s insane what the difference has been so there’s a couple ways I can take this but I’m just going to check in on the model preference stuff since it’s always a topic conversation I think you just let people choose whatever tools they like but then maybe you have some statistics
11:55 on what is preferred in the office. It seems like Opus is leading. Can you care to estimate market share, whatever? The vibe right now is Opus 5.5, I think. No Fable? I don’t particularly use Fable and I think a lot of people right now are just defaulting away from it. Opus is so good. It’s fast, it’s cheap. It kind of hits all my checkboxes. I would say I previously have had two to three models depending on whether they’re cheap and fast, whether they’re really smart, whether they can solve specific problems. And now Opus is kind of covering my full range.
12:30 I think a lot of the team still reaches for tools like codecs when we need to do something maybe more in the computer use world. And really workflow-wise, I think using both is still the best option, whichever your driver is, which I think for most of our team is Opus 5.5. Using a codex to review and having them actually work back and forth on your machine, I think still produces the best results. But right now we’re pretty aligned on those two. And are you still AMP maxing or no? Oh, I am AMP maxing. So you’re using Opus through AMP? So yeah, they recently…
13:05 Or that’s the default model for AMP. Yeah, they recently launched the ability to hook in your Cloud Code subscription. So that’s been a pretty big game changer for me. Because that’ll really cut your cost by like 80%. Totally. I mean, I love AMP because it takes everything off my computer. They have this cloud setup, the orbs. We actually co-hosted a happy hour with them last week, so it was cool to meet the team and orb out. That’s never going to be a thing. Oh, yeah. I want to make it a thing. This may be the first time in history that any human has said it.
13:41 We’re orbing out. We were orbing out. No, they do say it’s orbing time. Yeah. But, yeah, that’s my interface of choice. and models are really between that if I’m leaning on codex. It’s Sol6 one. Did you give CloudTag a shot? Isn’t it weird that Anthropic never captured the remote environment thing in the way that Orbs did? Yeah, I think there’s a piece of that, I think on the AMP side of them being very opinionated and not trying to build this general solution. Tools like CloudCode in the cloud and CloudTag, I think, provide value for teams
14:16 that are really trying to collaborate maybe on non-technical tasks. But part of the reason I love AMP is that it has all these cross-model functionalities and I can do that. Opus writes it. I can even hop to another orb and say, look at that orb and review it. And all of those things still come together to basically replicate what I’m doing on my machine. And I just couldn’t quite get there with a Cloud Code in the cloud, a Cloud Tag. Yeah, yeah. Fair enough. Another thing I always track, I’m starting to track this year, is percent of, let’s say, token spend to employee spend. I don’t know if you have that number. So roughly, most companies are at maybe,
14:53 let’s call it \$10 to \$200 in spend per employee. The more sort of AI native ones would sort of convert that to a percentage, so roughly 10%. The average AI startup employee is about 1x in terms of employee spend and token spend, and then it goes up to maybe 5 to 10x in terms of token spend. Where are you guys in that range? I actually don’t have a number off the top of my head. I’d say we’re somewhere between, if we’re talking like raw tokens, somewhere between 1 to 1 and maybe like 2 to 1.
15:29 Really? That’s pretty high. And what we think about a lot is like when to reach for the biggest model. I think every company is starting to think about that. But I will say recently our costs have been driven just way down from Opus 5.5. We kind of had an era of like everyone was using Astra and Fable and they just gave the best results. But ultimately those models are expensive. And like a lot of like, you know, since the last time we talked, a lot of people had this sort of token maxing error, token leaderboards, everything. And then they were like, oh, no, no, no, no. Now we have too much cost. And like, well, it’s the most predictable thing in the world. Did you ever fear about it or like you were just getting good ROI
16:07 regardless? this yeah I mean there’s a few ways that I think about it is like we were for sure we were for sure worried about it just as like our headcount was growing and um I think also like even though our team I would say like I don’t feel like anyone on our team ever really ascribed to like token the token-maxing zeitgeist, because… I had a few moments. Yeah, me too. But it’s like, well, if the boss is going to pay for it, I’m just going to go nuts, right? Because then you do the weird stuff
16:42 so that you can scale back, but you have to do the weird stuff first to discover the lessons that you can take with you. Yeah, totally. I mean, this may sound crazy, and I’d be curious of your thoughts, but I was talking to someone earlier about the debate that continues around… like basically, I promise this is related. Like I was talking to someone earlier around the data companies, right? Like Micro One, Mercore, Handshake. And just like, what does the long-term for these businesses look like, right? Because like 90 plus percentage of their revenue is from the labs.
17:17 And a number of these founders would argue that they think it’s going to flip-flop where in the next few years, it’s going to be enterprise-driven. And then like the thing that comes to mind, like the next thing I assume you have to believe if enterprises are going to be the core buyer of that data, is that enterprises are going to be doing a lot of fine-tuning on their own models. And then the question becomes, where is that going to make sense? It’s either you think there’s going to be better quality, which, again, like the bar is just going to keep moving on the frontier. So that’s like a hard bet to make. Then it has to be price. The price one feels hard to me because it’s like we’re just seeing token costs continue to go down on these models.
17:52 And so I guess part of the reason we’re not concerned internally is because it almost feels like we’ve kind of hit this like Pareto point of like costs are coming down at a per task basis. Then it is way harder today for someone to token max and like really F the company in terms of cost than it was six to eight months ago. Like I almost think six to eight months ago was the point at which like you’d be really concerned. Yeah. Do you agree with that? Yeah. I think there’s a couple ways like the future might play out there like if there’s a world
18:30 where there’s a Astra 6.5 a Fable 5.5 and they’re super expensive but they get the best results I could see us trending back that direction but generally I agree that you know you look at something like Muse Wonder that they launched yesterday today and it’s on the frontier it’s dirt cheap, the competition is heating up, both in open source and closed source. And I think that just will continue to drive costs down. And when you really look at it, a lot of tasks that are economically valuable can be done with Opus 5.5. So it’s that cliff of like,
19:08 would a 10 times smarter model really justify the cost of moving some cells in a spreadsheet? Probably not. Right. So coming back to your customers and what you’re seeing from the market, what is the most common ask that you guys get? And then what is something that people come to you with and you’re like, no, we don’t actually want that job yet? Yeah. So one way I think about this is I think about enterprises adopting AI as almost like these different milestones in a race. And I think, especially at AIE, when I tell people about what percentage of companies have reached these milestones, they’re kind of like mind blown by it.
19:45 But it’s like, okay, first milestone in the enterprise AI race is just rolling out a general purpose LLM to your people. And I’d say of the, you know, let’s call it 100 enterprises we’re talking to today, 90% have rolled out either Claude or Codex to their employees. Then the next milestone is like actually teaching people how to use it, like training and enablement, which like never gets the love that it should get, but is arguably more important or as important as the technology itself. I would say that’s at like 60%.
20:21 Oh, that’s pretty good. Yeah, yeah. Like there’s some group there of companies that are like, our people will just figure it out. But then there’s like a good chunk that is like, okay, we need to teach our people what skills are. We need to teach our people the features and functionality of these surfaces. Then the next after training and enablement within a general purpose LLM is coding agents. And the crazy thing is like, I was asking a few people here, like what percentage of enterprises do you think have rolled out coding agents to the engine product org in their company? And most people are like, it has to be 70 or 80%. The number is closer to 50%.
20:57 Like every other enterprise that we speak to either hasn’t rolled out a coding agent or what they are using is closer to not having a coding agent than having a coding agent. Then the next, and this is where like the biggest, I would say, drop off is, where like the biggest diffusion gap is from like raw intelligence to enterprise usage, is agents in production for non-engineering work drops to like 5%. It’s like, I mean, you’re in these conversations all day long, but like most enterprises that we talk to that have, let’s just say more than a thousand employees do not have an agent in production that is doing work
21:33 that is not building software. And so I think there’s a few things. One is there is, because like there’s just, this whole wave is driven by a combination of some small group of people understanding what is possible from this technology in a way larger group of people driven by FOMO. And by the way, FOMO isn’t bad. It creates some forward momentum, but it also means that people will latch onto the things that are most in the zeitgeist. I guess now for the last year and a half, people have been saying it’s the year of the agent or however long it is. Every year is the year of the agent.
22:08 Like enterprises are like, can you help build us an agent for some back office task within the organization. That is one of the most common things. And it’s why now a lot of the work we’re doing at Tenex is deploying agents into production outside of the entor for companies for repeatable work that they’re doing. The second is permissioning and RBAC. Basically, as every employee in a company has CLAWD or they have codecs and they need access to certain data, it has turned into an absolute nightmare for CIOs and CISOs. And they don’t have basically a good gateway for easily doing,
22:46 almost like a control panel for data permissioning. Literally just what can you read, what can you not read. Exactly. And that is a huge issue. So that’s like something we spend a lot of time on. So you make them for people or do you like buy something off the shelf? So basically we started by building Bespoke for companies and now we actually productize that where we have our own gateway solution. Yeah, exactly. Is there anything else that comes to mind that’s like, we’re hearing a lot from customers? I think that covered what we’re hearing when it comes to like, particularly the agent deployments. I think one of the pains that just always gets discovered,
23:22 I phrase it to the team, is like, you can’t automate a process that does not exist. So when you have 40 people that are all roughly doing the same function, but they’re all doing it a little bit of a different way, there’s actually it’s it’s way harder to build an agent that’s kind of proactively doing that in the background you can totally sit down with them give them the tools walk them through how they could augment their own workflow but when you really start to get the leverage is when you have these agents that are surfacing work to you you’re reviewing it you’re throwing it back and you become more of this like you know everyone’s been talking about becoming an agent
23:57 manager and i think we’re on the cusp of that but when you zoom out oftentimes our recommendation to companies is like, hey, first, we need to build a process around this organization within your company. And then here are the steps for us to actually hand off that work to an agent in the background. But if we don’t have some form of standardization, it’s going to be impossible for the agent to know whether it’s doing it right for us to build evals around this system and actually deliver the value that an agent that is doing this function would have. And even one thing I’d be curious your thoughts on we were literally talking about this right before
24:35 is and like uh cj will be okay with me sharing this is like the we were talking about like vertical specific ai solutions and like what does the future look like for these solutions and we we were generally expression expressing an overall bearishness with vertical specific ai solutions in different functions or industries and part of it is just from our vantage point of spending all day in like the guts of enterprises, there is so much nuance and so much inertia and so many systems you have to wrangle and people you have to wrangle. And also when a buyer of a vertical solution
25:11 is expecting truly a one-of-one experience, we’re in an age where people are expecting one-of-one software solutions. And so if you’re expecting that, it’s no wonder that every software company is basically building up a team of FDEs because there’s just this convergence happening of services and software when every company wants all this nuance that was not traditionally expected from software. And so I think it’s really interesting to think about, yeah, like four vertical specific solutions. Either one, how will they be able to do this
25:47 at software margins if everyone expects a one-of-one solution? And also, why should we not expect like frontier models to just gobble them up. Yeah. So to give some concrete examples, you’re talking like Harvey for lawyers. Yep. Open evidence for doctors. These are the classic examples of people that are winning their domains. And you’re bearish on them? I would say generally bearish on them. Correct. Wow. Well, so far you’ve been wrong. Yep. And I think the answer very simply is access to data that ChatGP is not going to have,
26:22 which is very common. That is a moat. Obviously, Anthropic and OpenAI are also acquiring those same data sources, but they’re just not as dedicated as these guys are going to be. They do have innovations. If you’ve tried it, Harvey, they have the Tabular Review. Legora also have them. We’ve had the CTO on the podcast where they have affordances and UIs and all that that is just customized because they only serve them. The pitch is focus, basically. Focus, affordances, maybe. What do you mean by affordances? In a way that you care about the last mile for your customers, they care
26:57 about their last mile in terms of the software. And as long as people train in that software, like it never goes away. Like as a banker or, you know, in my finance career, I could always access the same exact information from the NASDAQ, from the New York Stock Exchange. But why do I pay the \$50,000 a year for Bloomberg? Well, it’s just like that’s that’s what everyone, all my peers do. And it’s all consolidated for me and it’s all specialized for me. So I don’t make mistakes or whatever. or like it’s tied into my trading system or my chat or whatever, my news system. No, I think people play for Bloomberg is the social network. I think people love the DMs in Bloomberg.
27:33 There’s that, there’s that. But as a trader, I know I actually use that for. Yeah, yeah, yeah. So, I mean, I think there’s a bunch of integrations and tools and like, I think ultimately it’s hard to be bearish on any of them, mostly because the demand for software, the demand for tooling to do your job is just huge. And some of it, yes, it’s going to be fulfilled by horizontal generalized tools like the Claws and ChatGPTs, and some of it, you’re just going to want something better. And, you know, I always think about maybe the success of Superhuman as an email client. Everyone has Gmail, but here’s just premium Gmail with, like, more stuff for people who live in email all day long.
28:09 And, like, that’s a market. It maybe wasn’t the largest startup in the world, but I think reasonable people can disagree how large each thing is. Yeah, totally. I think what’s not to be disagree with is the total market’s going to grow, and all rising tide is where they’re tall boats. And then you’re just talking percentage pressure market share at that point. Yeah, yeah, I agree with that. Totally agree. I think there’s even, there’s like a differentiation between some new app built from the ground up with AI involved. That’s what comes to mind when I think about Superhuman. I love Superhuman. I don’t even spend a ton of time in email, but anything that has…
28:44 No, you pay 30 bucks a month just to not worry about it. Anything that has cool hotkeys, I’m into. Yeah. But when I think about, I guess, products where they are really pushing some agent as the product that is doing work in some specific vertical, unless there is some very strategic compliance data, whatever it might be, moat, I think those are going to struggle going forward as we start to see quite literally the ability to either spin up your own really quickly, continue to compound as the models get better, or just those tasks start to fall into the world
29:21 of the models just generally. But anything that has this app and tool built around it, kind of to my previous point, changes the process and has an agent on top of it. And I think that kind of builds on the same philosophy, and I think that can still be super helpful, and those will be successful. Yeah. Oh, okay, okay. So there is a related view about this that maybe isn’t quite as spicy as yours, which is basically it’s not like nobody wants to use… People probably don’t want to use the agent that you built. They want to use the agent that they already have, and they want to plug in your data into their agent. So everyone is sitting on some part of your data,
29:58 and they’re like, use my agent, please. Please pay me that \$20 a month. But you can’t just stack up all these \$20 a month subscriptions. Ultimately, probably a small set of companies are going to own the interface, and then everyone just plugs into that overall agent, which I agree with. Then it’s interesting that Salesforce, being one of the system of record companies, is the biggest probably or the most well-known, is embracing that path as like you will not use our agents. Like we will just provide APIs and MCPs for you to plug into your stuff. Yeah, which is kind of cool. Okay, so I actually wanted to also walk through one example.
30:35 So I just released my results for my Kill My SaaS competition where we replace a mid-tier SaaS. I call it mid-tier basically in the sense that it’s probably not that trivial, but it’s not Salesforce. It’s somewhere in the middle. And I think there’s a lot of mid-tier SaaS out there that people are always talking about, like, the death of software, right? we were quoted \$40,000 a year. We spent \$1,000 to replace it. It’s going to go into production for the next conference. So we are that customer that says, like, I want the one-on-one tool, and I’m expecting all these things. And we’re building a domain-specific or vertical-specific thing for our business. And, like, so far it’s going okay.
31:10 Tell me where it’s going wrong. Also, I’m wondering how many story points that is. Yeah, well, CJ can size up the story points on it. I mean, my general view is I think the ripping out of – my general view is like the more you move upmarket in business, the harder the proposition of ripping out and building from scratch gets. I agree with you. Like part of the reason when, as people have said, like a very small group have said, like Salesforce is really at risk. SAP is really at risk. Like don’t agree with that at all. It’s just like those businesses in my mind just accrue value in this moment
31:48 in time. And part of the reason they accrue value is there’s so much money at stake where if a company gets it wrong ripping them out, you’re talking about potentially hundreds of millions or billions of dollars. You’re going to be risk averse. Yeah, exactly. I think for mid-tier, it actually comes down to what is the size of the opportunity, and is that ever going to be the worthiest opportunity to rebuild inside of a company? I’m trying to even think. In an enterprise, let’s just say there’s some mid-tier SaaS that is a few million bucks a year.
32:23 I think the first question is, from a percentage of revenue or cost perspective, is that going to ever move the needle enough to basically allocate engineer or resource to? I think it’s going to be case by case. I think for some enterprises, the answer may be yes. For other enterprises, the answer may be no. I think more of it is going to be the thing that gets companies outside of capability. Like, you know, we talk about how, I forgot who created the repo. That is basically the reverse engineer repo. RIA. Yeah, exactly. Like, everyone’s talking about that right now. And even at Tenex, like, we built our own, like, CRM from scratch.
33:05 What did we build? Our OS we built from scratch. And, like, one thing I think we realized, and every company realizes this, is one of the beauties of software is not just the utility that you get from it. It is all of the headaches you don’t have to think about in maintaining it and improving it when it’s not in your core. So I think it basically comes down to, is the size of the prize big enough to justify the cognitive load that is going to take from some amount of resource in your company to nurture something that is not core to your business?
33:41 Evidently, like I think for your business, the difference of basically \$39,000 a year, you’re implicitly saying that it is worth it. It is not just about costs. That’s defense. I also think about the offense of like, no, actually our experience could be a lot better for literally every party concerned. Totally, totally. And so, yeah, I think part of the thought there is actually just, there’s a significant, basically it’s not just that. So there’s two pieces to it. One is like, not just we’re being overcharged for a product, but it’s like the product has been mediocre for a long period of time. Yes. What would the 10x better version of this product look like?
34:17 Yes, because we are the customers and we can iterate with like minutes and not months. Totally. I think, I actually think what’s interesting is I think startups and like even like high growth, mid-sized companies can be nimble in that way. I think for enterprises where like they’re so entrenched in a certain capability, rarely is that going to be the thing that, rarely are they going to say like, oh, we can create a 10x better version of this SaaS we use and we’re going to spin it out potentially as its own thing or whatever it is. I just don’t think enterprises function that way. For sure. Yeah, it’s been discussed.
34:52 Actually, I would say that you talk about automation. The more spicy thing is are they automating humans, right? And once everything is automated and smooth sailing, do we replace those jobs? I don’t know how much you can speak to that. Yeah, I mean, I think there’s two pieces here. I really deeply believe in the like, AI will produce good for humanity. It’s going to augment people’s jobs. It will absolutely change and displace. But I think it’s more of a movement as opposed to just like cutting off work. I think A16Z posted something about
35:28 how like call centers are truly now on the decline and AI is starting to handle more and more of that work. And ultimately, if that is a skill you’ve built up your whole career, that is devastating to have something come in and take that function over. That being said, part of what we do when we’re talking to customers about, hey, an agent is now going to do this work is actually around reallocation. I don’t think any business would claim like once we have this solved, there’s nothing for this group of people to work on and try to solve. So our approach really is about what can we replace and then what are the next biggest problems to look at?
36:05 and I’d make an argument in most large companies that that cycle kind of continues forever. There’s always the next problem if I think about how we’ve grown. Infinite demands. There’s always been another problem and actually taking those people that may have this like super deep subject matter expert and bringing them above water to start to maybe work more across teams or like think about parts of the business less so on like the level of a sell in a spreadsheet and more about how these teams are working together. Ultimately, in the long run, I think that keeps most people there
36:41 and allows those businesses to become more nimble and actually tackle the big meaty problems and not the drudge of most people’s day-to-day. When you’re thinking about someone that’s in a finance division, they’re mostly in spreadsheets, but how can we elevate them to think strategically about the business and where money is allocated and things like that. Yeah, and I also feel like when we have these conversations around job displacement or job reallocation, we talk about it as this thing happening to people. And one of the reasons I don’t like that is I feel like it doesn’t give enough credit to people
37:17 to have agency in their own lives, meaning I think… You can adjust. Yeah, people really should be thinking. When I think about enablement or people re-skilling, I think it is the job of an employer because they want to drive growth in their business, but it is also the job of an employee. And I think when people say that AI is going to replace all of the work that people don’t enjoy doing, I think that’s a little bit of like cope for the reality of just people are going to be put out of jobs because a lot of people don’t have the luxury of liking or not liking a job. They do a job to make money. And also I think people, to the extent that it’s possible,
37:53 should have agency in saying to themselves, okay what is the the stability or replaceability of my job over the next few years and if i am to try to skill up in a way that i’m better protected what does that look like people have agency to say that to themselves and actually take action yeah yeah yeah um i think that’s a good message for people to reflect on um the last piece i wanted to touch on before i let you guys go is just new york um you know uh greatest city in the world according to some people some people what’s the mood generally among the people they talk to, whether it’s at work, personally, what’s the feeling, right?
38:28 I live in San Francisco all day long. Everyone’s just in agents all day long. The discussion is instincts or grok or muse. It’s not like do you like AI or not, right? And I feel like I want to step out of that bubble for a bit, but it’s still New York. It’s still progressive. It’s still forward-looking. Yeah. I mean, what I’d say is I feel like, basically, I would just say there’s a bubble in New York that is a smaller bubble than exists in SF. If SF is like a big bubble, I think we at Tenex feel like, you know, we are in a, what I would say is like a microcosm of San Francisco
39:03 because of the people that self-select to work at the company. And then also the companies that we’re partnered with and like the people that we engage with in New York. But I would for sure say also, it is true that it is a smaller universe than like in SF, when you go to SF, it feels all encompassing where it’s like everyone, everywhere you look, There was someone who, similar to AIE, how I was saying earlier when I went on stage, if people go on Twitter or X because they feel like they’re on Edge City, they’re living in the future, AIE is that on steroids. I feel like SF is similar to AIE.
39:40 I mean, it’s probably the overlap of AIE generally and people who have lived at some point in their life in SF is probably a very large overlap. We’re roughly 1% of the city now. Actually? For World’s Fair, yeah. That’s crazy. Yeah. But like to that point, I just think like it is in the culture and the DNA of SF where a very big population of people live in the future. I think you can find that group in New York. And I think we at Tenex have found that people. And part of our goal is to drive like AI as a hub or New York as a hub for
40:16 AI in the US because there is so much commerce here that like it is going to be a place where diffusion of the technology actually has such a meaningful impact on the GDP of this country. I think the bubble is smaller now and we take it almost as like a charge of ours to increase our bubble. Maybe I don’t know that it’s possible to get to SF size, but I do think we can have a meaningful impact on getting more people to live in the future here. There’s a physical, like you see it on the billboards. It’s slowly creeping in. Oh, totally. People used to, remember the friend campaign where people would like spray all sorts of graffiti on that? I think that was like a little bit of an intentional rage bait. But now you have the unironic AI billboards and people are like, I guess
40:52 that’s part of life now. A hundred percent. Yeah, so I think it’s like, I think there’s an opportunity to bring kind of like the edge and like the, just like the living in the future nature that SF has created because of just like the economic climate that exists there because of venture, because of tech companies, then because of the people that are attracted there. but I also think of us as like we’re in a, it’s weird, we’re in a smaller pond for AI but I would argue we’re in as big of a pond if not a bigger pond for like
41:29 commercial value and so I actually the way I put it is like the reason I do AI in New York is I bring all the people from San Francisco to come here and meet their customers and also get a reality check Totally. And I actually think there’s a really interesting arbitrage there. Yeah. Yeah. Yeah, totally. Okay, awesome. Call for hiring. I know you guys are always hiring. Yep. What are you hiring for? What’s changed? Yep. We’re hiring forward deployed engineers at Tenex. Just go to tenex.co. We’re also always hiring AI strategists, which are basically technical consultants who are leading client engagements. And the team is 75 strong in New York City. We’re continuing to make New
42:07 York City our home. And then if you are an enterprise who is looking to actually get AI native and you’ve tried it, it’s not working, hit us up. I promise we’ll do better work than, not going to name them, but a lot of other traditional consultancies. Ooh, spicy. CJ? Yeah, I mean, I echo all of that. I’m particularly looking for engineers. What’s a special project? What is that? A special project involves anything outside of kind of our client work. So I think about my brain right now. It is building that meta harness and system internally that basically it’s
42:45 like find the bleeding edge of what the models can do and give them tools to augment how well they can do it. And then also internally working on the platform that Alex mentioned. big goal there, diffuse these background agents and actually get them out to enterprises in a way that’s truly, truly helpful to them. Yeah. And solve a lot of those like messy IT problems that we hit on earlier. Dude, when you have some solutions, we take guest posts on the Latent Space blog. I’d love to welcome some sharing of knowledge. But otherwise, thank you so much for your time.
43:20 And good to see you again in New York. Yeah, likewise. Appreciate it. Once a year, once a year. Hell yeah. Thank you.