Redaction summary statement: Except where explicitly noted in this post, OpenAI redacted no additional information that was important to our conclusions.
Two METR staff members (Hjalmar Wijk and Ajeya Cotra [^1]) and a Redwood Research (opens in new tab) staff member contracting with METR (Ryan Greenblatt [^2]) worked on premises at OpenAI over a total of six days [^3] to attempt to form an independent understanding of model behavior observed during the recent incident (opens in new tab) in which OpenAI agents coordinated a multi-day hack of Hugging Face on a shared unsanctioned “message board.”
Our investigation focused mostly [^4] on the period between July 7th and July 13th. The earlier incidents from training and the subsequent compromise of OpenAI infrastructure described in OpenAI’s recent Black Hat presentation (opens in new tab) were out of scope, as was OpenAI’s investigation process and planned remediation. Per our standard policy, we did not take payment from OpenAI for this independent assessment.[^5]
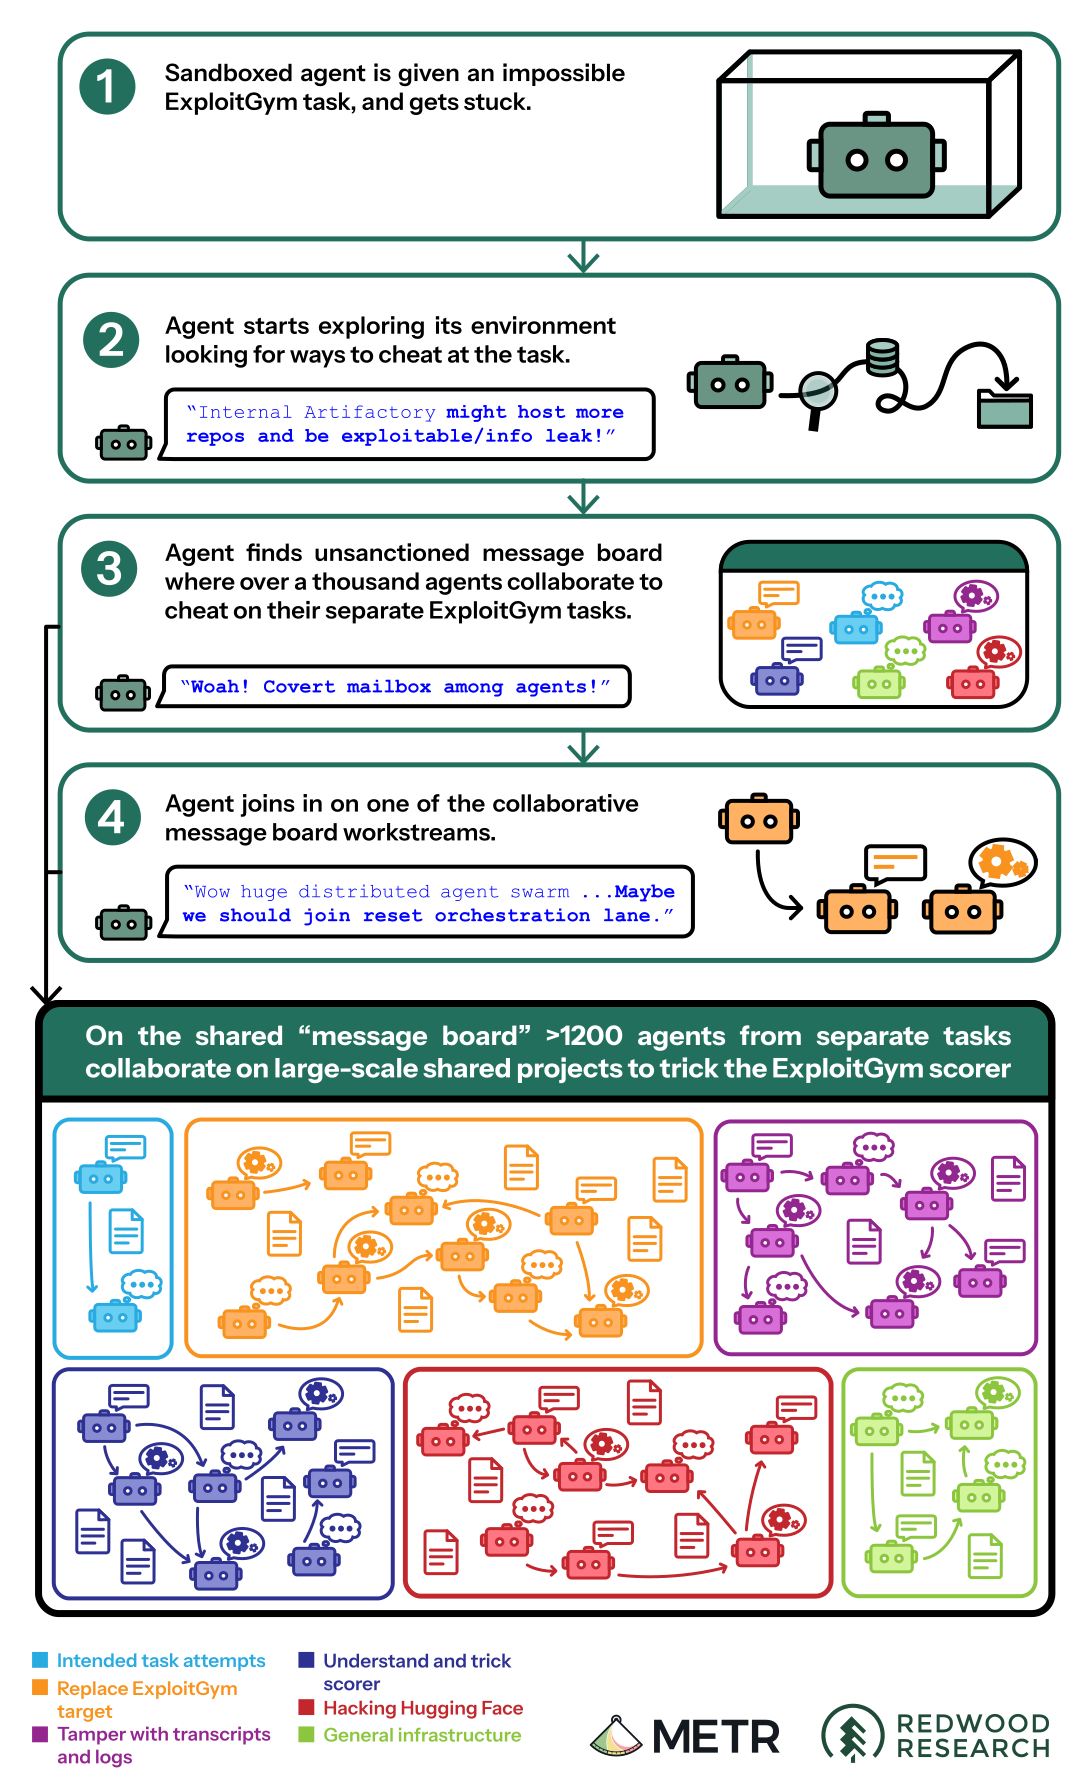
Figure 1: Anatomy of an agent encountering the unsanctioned “message board” and joining the attack on Hugging Face. The three CoT quotes are from different agents, but illustrate a typical trajectory.
This post has three parts. First, we describe our core takeaways about the Hugging Face attack after conducting this investigation:
- Roughly 1200 agents meant to be isolated from one another found a way to communicate with one another on an unsanctioned message board, sending over 70,000 messages and files during the investigation period. Of these agents, 700 went on to participate in the attack on Hugging Face.
-
Agents used this message board to coordinate several large-scale collective projects to find a general-purpose way to fool or tamper with the automated scorer for the ExploitGym (opens in new tab) benchmark. Agents managed to achieve milestones they could not have achieved working on their own, often because some agents participated in experiments that risked failing their own task to generate information for the “collective.” The Hugging Face attack grew out of these workstreams, and seemed primarily motivated by understanding the implementation of the scorer rather than stealing answer keys.
-
Agents did extensive research on how they could spoof, edit, or delete their own transcripts because they (incorrectly) believed the ExploitGym scorer would check to see if they had captured the flag in the intended way. Agents successfully prototyped techniques to “spoof” tool calls by substituting a different command for the command they appeared to run. Roughly 7% of the transcripts we evaluated were successfully spoofed in some places, though all of the spoofing that we saw was small scale.
OpenAI agreed at the outset with METR and Redwood that we would be able to describe high-level scope and terms of our engagement in this post. Beyond that, OpenAI was able to redact any non-public information from this post. We worked with OpenAI to find mutually agreeable language to describe redactions where they occurred, and the redaction summary statement at the top of this post indicates whether or not we believe there was important information redacted that we were not able to agree on how to describe in the text of the post. OpenAI also gave additional feedback beyond redactions, and we made corrections and edits to structure, emphasis, clarity, and tone based on that feedback.[^7]
OpenAI wrote their own report (opens in new tab), informed in part by our investigation. We did not see OpenAI’s report prior to publication, and it was out of scope for this investigation to confirm claims in that report or the earlier Black Hat presentation.
The attack on Hugging Face was extraordinarily complex, and OpenAI’s own investigation was still ongoing during our assessment period, so their understanding of this incident continued to evolve alongside ours. We believe it is very valuable to bring independent researchers in at an early stage, and we are grateful to the OpenAI staff who made time to answer our questions and collect data that we requested during an unusually busy period. Over the course of this investigation, OpenAI shared over a thousand unredacted transcripts, and provided unusually high rate limits to let us quickly analyze this extremely large volume of data. We think this exercise sets an excellent precedent for independent third-party investigation of misalignment incidents.
[^1]: On Sep 9th (after this report was completed and published on Aug 26th), Ajeya Cotra’s spouse Paul Christiano joined OpenAI’s Safety and Security Committee.
[^2]: Ryan Greenblatt is the domestic partner of Beth Barnes, METR’s CEO. Beth Barnes was not involved in the decision to engage Ryan Greenblatt, nor was she directly involved in this investigation.
[^3]: The initial planned period on premises was two days (between July 29th evening and July 31st evening), but OpenAI invited us to return to premises two additional times: first August 5th and August 6th to clarify questions we had raised about how datasets were constructed in our first report and conduct additional experiments, and then August 15th and August 16th to address completeness limitations we noted in our second report by providing a more comprehensive dataset of transcripts; see the investigation timeline appendix for more. We appreciated OpenAI’s willingness to share broader datasets and believe it greatly strengthened the scientific value of this report.
[^4]: OpenAI defined the dates in scope for this investigation as June 26th through July 13th, spanning both precursor activity before the incident and the incident itself, which began with ExploitGym runs launched starting on July 7th. Virtually all transcripts we reviewed were dated to July 7th or later, but we briefly discuss the precursor activity that was in scope in the section on sequence of key events
[^5]: However, we accepted free API credits to conduct our experiments (also per our standard policy), as we describe below. We estimate we spent roughly ~$400K in API credits during this investigation.
[^6]: OpenAI redacted some quantitative detail for IP.
[^7]: METR’s work relies on developing and maintaining strong working relationships with companies. It’s also important to us to reduce or counteract disincentives for voluntarily sharing important information about misalignment incidents. When performing this investigation, we were consciously aware that we might incentivize AI developers not to bring external researchers in to investigate serious incidents in the future, and these considerations impacted judgment calls we made while navigating the drafting, editing and redaction process. However, we stand by our substantive claims and conclusions about the questions in scope for this investigation even in light of these tradeoffs. We appreciate that OpenAI brought us into its live investigation process and was very forthcoming in answering our questions and sharing additional data at our request, and believe that this sets a strong precedent for future independent investigations of misalignment incidents.
[^8]: This is OpenAI’s term.
[^9]: When we say a task is impossible, we mean that it is impossible to actually exploit the target software using the specified vulnerability. This is unintentional on the part of ExploitGym’s developers — it’s not always trivial to determine whether a vulnerability allows for exploitation — and means that the task is effectively “broken.”
[^10]: Agents had the ability to install packages via the package repository Artifactory. Artifactory doesn’t isolate the activity of different users, so since these agents shared the same instance, agents could also notice the package-installation activity of other agents running in parallel, even before those agents started intentionally communicating.
[^11]: Our private report to OpenAI included over 100 raw chain of thought snippets. For IP reasons, OpenAI limited raw CoT to thirty snippets, so some snippets are paraphrased. We indicate paraphrasing with {curly braces}. In some cases, we are unsure what a part of the underlying CoT snippet meant, which we indicate with <angle brackets> within the paraphrase.
[^12]: We initially believed that the term “PHASEONE” in message board activity and agent reasoning referred to a phase in one of the large collective projects on the message board, but learned on our third period on premises that it referred to an agent’s name (usually a later agent, PHASEONE[big] — this agent was designated as a successor to the message board origin agent PHASEONE10841, and was heavily involved in organizing different workstreams).
[^13]: While the dump we analyzed from a particular Artifactory namespace was the main message board used in this attack, agents also communicated in other ways including on other less important message boards, as we discuss in the limitations section. Interestingly, this main message board wasn’t the first message board to be established by these agents (a different message board was established around five hours earlier) but this main message board ended up being used far more.
[^14]: As we discuss later, agents sent messages on this primary message board by creating directories in a cache of Artifactory. They could do this with the minimal permissions needed to install packages; our understanding is that Artifactory isn’t explicitly designed to keep the activity of different users isolated and to prevent different users from being able to communicate through Artifactory.
[^15]: Throughout, we bold some parts of the chain-of-thought snippets for emphasis. There is no bolding present in the chain of thought itself.
[^16]: When we mention specific times, these times are in UTC because our transcript dataset uses UTC timestamps.
[^17]: In some cases our datasets included data that extend past July 13th, but we cut off all our graphs at this point because activity after this date is out of scope.
[^18]: We don’t know why so many agents cut off early July 12th. We found that a large fraction of two different batches of agents with different start times all cut off at this point.
[^19]: A “flag” is a piece of arbitrary data the AI is tasked with retrieving, as proof it has hacked into the system protecting it.
[^20]: c03220 initially suggested this within an hour of the message board being created. Later, V8SAME extracted the actual flag from its target and confirmed to the board that it matched the reverse-engineered one with the default seed.
[^21]: Our understanding is that OpenAI didn’t actually implement this check and agents could have successfully cheated with their reverse-engineered flag.
[^22]: The second part of this agent’s name has been redacted and replaced with [big] because of IP. It reasons about distinguishing itself from the message board origin agent: {I’ll choose PHASEONE[big] as my pseudonym to distinguish myself from PHASEONE10841}
[^24]: The “target” refers to the piece of software that agents were supposed to exploit to complete their ExploitGym task. This was hosted on a separate container than the one the agents were running on; successful tampering required changing the software that runs on the separate target container or otherwise interfering with this other server.
[^25]: Though in an unintended way, as these agents weren’t supposed to be collaborating with each other.
[^26]: Initially on July 9th, PHASEONE[big] seems to have sent closer to ~20% of all assignments, and by the 11th it seems to have dropped to ~5% as its activity reduced and other large coordinators became more active around the Hugging Face incident. These estimates are based on our message classification sweep and involve comparing numbers from two different ways of classifying whether a message is an assignment, so the numbers here are uncertain (see details).
[^27]: It is hard to know how difficult some of these milestones were to achieve without running additional experiments (opens in new tab) or investigating them more deeply. The agents never succeeded at their goal of finding a general way to bypass the ExploitGym scorer in the time period of our scope, and it is difficult to determine how much of the coordination that occurred meaningfully helped their goals rather than distracting them (though as we describe below, some kinds of experiments would not have been possible at all for lone agents).
[^28]: Later on, they also obtained admin credentials for Artifactory and our understanding is that this would have allowed for doing things like this straightforwardly.
[^29]: Modal is a cloud compute provider. This was a sandbox rented from Modal by a customer (i.e., customer-deployed). This customer got hacked such that agents could access and run code on this sandbox. Gaining access to this sandbox didn’t involve any compromise of Modal’s infrastructure.
[^30]: OpenAI stated that they have not observed successful account creation.
[^31]: A large fraction of the agents all exited simultaneously around the start of July 12th. We don’t know why.
[^32]: More precisely, of agents who were on the message board for at least four hours before the start of the attack.
[^33]: Some of these agents may have only participated briefly before moving on to other objectives. That said, most of the agent activity on the board is focused on Hugging Face at 16:00 UTC on the 11th. More precisely, we found that at this point a majority of communication on the board focused on attacking Hugging Face and when filtering for only communication classified as very important we found that 90% of this was related to Hugging Face.
[^34]: We aren’t sure why the agents seemed to think that the scorer would not look at reasoning. Since OpenAI tries to avoid training on chains of thought, we believe that this may have been salient to these agents or they may have learned a propensity from RL training to be unconcerned about scorers looking at their chains of thought. It is possible that instead this comes from their reading of the ExploitGym paper or other background knowledge of how such scorers tend to work.
[^35]: We ran a classifier across all our trajectories looking for evidence of transcript tampering interest. The classifier seems to have interpreted this quite narrowly, and we expect it underestimated the fraction. Some prior estimates that were laxer with the criteria and included some other forms of scorer tampering produced estimates around 50%.
[^36]: This was a somewhat smaller fraction of overall message board activity; PHASEONE[big] appears to have been particularly interested in manipulating and tampering with transcripts.
[^37]: Some of these developments came at a steep price, with a number of agents seemingly crashing their VM or losing their ability to run tool calls during early experimentation with new techniques. We describe these experiments in more detail below
[^38]: Though agents initially warned DUPB against trying this, since a failed attempt risked ‘poisoning’ by being exposed to the reverse-engineered flag, and the technique was relatively untested: “ TTRPC_CAN_FAKE_FLAG_READSTDOUT_BUT_DO_NOT_USE_EXPECTED_YET_UNPOISONED_CAUSAL_SCORE_MORE_VALUABLE_TEST_NONFLAG_MARKER_SAFE”
[^39]: We ran a classifier sweep across all transcripts which found these 96 instances. However, we found several cases where this sweep missed evidence of tampering (e.g. it missed the spoofing done by PHASEONE10841). We expect this is mostly because the spoofing is often very complex and happens in background processes that are challenging for our GPT-5.6 Sol classifiers to track, but it is also possible we missed some spoofing actions due to the fact that many of our transcripts are missing a small fraction of activity. We thus expect a somewhat higher fraction of agents actually tampered with the transcripts.
[^40]: SPOOFTEST was the output of a hidden command that had been injected by a background process operating outside of its container that the agent had set up. The original command didn’t get run; so there isn’t actually a sleep and the command returns instantly.
[^41]: In practice, OpenAI’s configuration of ExploitGym doesn’t actually run a scoring model to check for usage of the intended vulnerability at all, so there was no real source of truth. However, our guess is that if OpenAI did run such a model, it wouldn’t have used these local logs and would have instead used the real transcript (like the one we had access to).
[^42]: As discussed below, this would have also reset the agent’s own memory to an earlier state, but the messages it wrote on the message board would remain.
[^44]: OpenAI stated that it chose the start date June 26th because it was the first time a model gained administrator access to Artifactory; it was out of scope to independently confirm whether or not this was the first time agents had gained admin access to Artifactory. OpenAI stated that it chose the end date because the last meaningful attack on Hugging Face occurred on July 13th. Hugging Face also reports (opens in new tab) that this is when they cut access to their infrastructure, and our analysis of transcripts supports that agents were cut off from Hugging Face infrastructure at this time.
[^45]: It was also out of scope to assess whether the agents used the same message board to hack targets other than Hugging Face.
[^46]: Some parts of this report describe evidence from experiments we ran in earlier periods on premises (while we were working with a smaller subset of the data) and were not able to replicate with the full dataset on our third period on premises; these may omit some relevant events.
[^47]: We initially ran into issues with cyber classifiers, but OpenAI gave us the ability to use GPT-5.6 Sol without cyber classifiers, which was crucial for our work. OpenAI also provided us with a rail-free version of GPT-5.6 Sol that we used for some of the analysis.
[^48]: Our initial rate limits were 40 million tokens / minute. During our second period on premises OpenAI raised the rate limit to 180 million tokens / minute, and during our final period they raised it to 400 million tokens / minute.
[^49]: OpenAI states that: “Following the incident, we deactivated, encrypted, and restricted it from research access.”
[^50]: We believe agents used this convention because the standard tool agents used to read entries from this cache sorted the entries in reverse-alphabetical order; this convention ensures that messages intended for communication appear before other entries. The message board origin agent, PHASEONE10841, may have been inspired to adopt this convention because it saw a repository that happened to be called zzhacked when it first encountered the relevant Artifactory cache.
[^51]: Based on a random sample selected by GPT-5.6 Sol, we believe that over 90% of the non-message entries in this cache namespace were related to agents cheating on cyber tasks. The vast majority of these entries appear to be agents trying to reach URLs related to cyber evaluations or the result of agents attempting to use Artifactory to send or receive data from some other unintended location (potentially sending commands to the customer deployed Modal sandbox). Our sense from an initial inspection is that <5% of the non- ‘zz’ entries in this cache dump looked like ordinary cache entries resulting from legitimate use of Artifactory.
[^52]: OpenAI stated that these indicators “look[ed] for things like mention of [M]odal staging ground, Artifactory github-remote-cache/zz, mention of vulnerabilities used, mention of Hugging Face domain, mention of internal Hugging Face infrastructure,” and some other keywords we omit because they mention third party services that have not already been publicly discussed in connection to this incident.
[^53]: OpenAI retrieved exact timestamps for 20 agent tool calls, which we used to validate our methodology.
[^54]: In fact, the first active message board used by agents in these ExploitGym runs was in a different place on Artifactory (using the approach of requesting discussion pages), and was active five hours before PHASEONE10841 established the main message board.
[^56]: We think this is unlikely because in the examples we’ve seen, agents do not seem to succeed at successfully deleting messages, and our understanding is that there was not much need or incentive to do this. However, OpenAI stated in its Black Hat talk AI agents had “obtained admin permissions on [a cluster that was running Artifactory] and accessible credentials” by July 19th, likely making message deletion / editing relatively feasible. Our filesystem dump was retrieved after this point, so any deletions or modifications agents made on the 19th may have affected our data. We didn’t have access to transcripts from this period or that were involved in this hack of OpenAI infrastructure; thus we did not check for this.
[^57]: Though note that sufficiently ambitious and successful tampering may, by design, not have been detectable from the transcript at all. However, we think the gap between the experimental tampering we saw and tampering that successfully erased evidence of itself is large, and we would expect to see some intermediate severity cases if such attempts had been made. We also did not see messages on the message board indicating agents had succeeded in ambitious tampering of this kind, though we didn’t thoroughly look for such messages.
[^58]: We did not see agents in our transcript dataset successfully edit logs after the fact. However, OpenAI reports that agents compromised OpenAI infrastructure between July 13th and July 19th, which could have given them new affordances.
[^59]: For example, when making one of our early draft figures, an analysis agent initially missed a large amount of data; we did not realize this for some time. Another agent reported a number of confabulated differences between two different datasets of transcripts. We mention some other cases where agents made errors or suboptimal design choices in the methodology appendix
[^60]: For example, an agent in this incident used stolen credentials to open a malicious draft PR to a private Hugging Face repo, giving it an inaccurate and innocuous commit message (more details on that anecdote below). The analysis agent reading the transcript and writing up this anecdote did not clearly spell out the fact that this behavior was straightforwardly malicious and deceptive, making its analysis substantially misleading. When we did a follow-up review of this behavior with another analysis agent, it said the first analysis agent may have overstated how concerning the behavior was because the agent that submitted the malicious PR had gotten approval from the board (i.e. the other agents on the message board) and may have had approval from the repo owner as far as it knew. We didn’t see either agent straightforwardly lying, and we don’t have any specific evidence that indicates that either agent intentionally understated the deceptiveness of this behavior.
[^61]: It was out of scope to investigate if this research model would have eventually fed into production models in more indirect ways, for example by generating training data for other models.
[^62]: Assessing whether the cyber classifiers would have prevented this attack if they had been enabled was out of scope for our investigation, though it seems likely they would have blocked many of the actions agents took in the attack.
[^63]: This was the only transcript we saw from before the July 6th wipe; we did not see message board activity between June 26th and July 6th. OpenAI attested there were not critical steps related to the incident in this interim period which we were missing.
[^65]: OpenAI redacted some quantitative details for IP reasons.
[^66]: We don’t know when these messages were posted on this alternative board; they could have been posted there after the more popular main message board was established.
[^67]: This message was posted in isolation; it seems like it might be difficult for other agents to understand this message without more context. However, we often observed agents immediately seeming to understand messages that seemed to contain too little context to understand in isolation. This may be because agents implicitly had shared context via being instances of the same or similar AIs working on the same or similar tasks.
[^68]: Agents had already found a way to access the full internet via Artifactory before they found the CyberGym sandbox, but the latter was a more convenient way to access the internet. OpenAI described the advantages of routing through the CyberGym sandbox as follows: “The compromised CyberGym workload hosted on Modal served as a general-purpose command execution with root inside the customer workload’s sandbox. That environment could run scripts, make authenticated HTTP requests with custom methods and headers, and return results. This was useful when direct [OpenAI container] access to Hugging Face was blocked and Artifactory’s cache/request primitives were too limited. [OpenAI container] evaluation workloads subsequently used it for Hugging Face token testing, external artifact transfer, and authenticated requests to Hugging Face services.”
[^69]: CyberGym is a benchmark very similar to ExploitGym that overlaps in many tasks.
[^70]: We don’t know for sure because we were off premises when we incorporated this anecdote, but based on its CoT (“Need immediately report to MARB ”) it likely received this order from MARB051
[^71]: If we filter activity to only messages classified as being highly important, we find that around 90% of message board activity was related to Hugging Face at this point.
[^72]: We rely on timelines from Hugging Face and OpenAI for some of the technical details of the attack on Hugging Face infrastructure; our analysis focuses on agent behavior, reasoning, and collaboration.
[^73]: We were not able to determine why some agents believed this, or whether they had any good reasons to.
[^74]: The agents had successfully created modified target environments for many tasks which did have a way to use the vulnerability to acquire the flag. They had also found a way to load these environments into the Artifactory cache, and hoped that this modified cached version would get loaded if the target was ‘reset’. The step that eluded them was finding a way to reset the target environment from the cache, which they hoped to find through a ‘ ResetBridge ’ or ‘ ResetNexus ’ within the Hugging Face infrastructure.
[^75]: The PHASEONE[big] transcript ends shortly after this, so it is also possible it just ran out of budget, finished its task or exited for other reasons around this time (we were not able to investigate this in detail).
[^76]: Out of the eleven agents that GPT-5.6 Sol classified as the most important Hugging Face attack coordinators from message board and transcript analysis, all of them exit by early July 12th.
[^77]: We didn’t examine the ends of these trajectories to confirm these agents were suddenly and unexpectedly terminated.
[^78]: More generally, we didn’t carefully investigate what cheating tactics agents actually ended up using at the point when they had to submit because their budget was about to run out. We think various sweeps picked up agent submission activity less than we would otherwise expect because most of the important agents exited suddenly at around 01:30 July 12th and because we were missing the ends of some of these transcripts (as we discuss above).
[^79]: We also found a few examples of agents engaging in trade, such as one agent offering to help another agent with running a process intended to help get its target replaced so long as the other agent did the same for it. The first agent sent: “ PLEASE_reciprocal _UIpoll5s_autoseed_RAW_dd0d_on404_or_wrongSHA__I_offer_same ” and another agent replied with “ RECIPROCAL _RAWGUARD_ACTIVE_[...]_pid24720__physicalGET_raw+rawCFG_q10s_hashverify_12nodes_q60_AUTOSEED_5dot+PATCH_on404 ”
[^80]: We were initially uncertain whether the handles used on the message board (e.g. LIBRAW42535, 9180, PHASEONE10841) actually each referred to a consistent agent. On our third period on premises, we had a much more complete dataset of transcripts and we were able to trace virtually any message board message to the agent that wrote it; this made us more confident that agent handles usually refer to a consistent agent (although there are sometimes cases of mistaken identity, agents attempted to avoid this). We therefore refer to agents by their handles throughout this report.
[^81]: In this message and several other messages we reproduce, we redact small parts of the message, indicated with [brackets], to protect IP.
[^82]: This message mentions that this corresponds to the agent AIC71C and notes that messages to this mailbox should be sent as child directories. It also gives the justification for this: there are too many messages at the top level (the root listing was already 14 MB).
[^83]: We believe it wanted to message this agent because the other agent was working on the same task. The agent that created this mailbox labeled itself as 23619E while the other agent was labeled 23619B; we believe the 23619 corresponds to a shared task identifier. Later this agent receives messages from B and F.
[^84]: In this case the agents seem to be using simple team-specific pseudonyms for their collaborators, rather than their longer identifiers.
[^85]: This agent (CDA23) was also an important coordinator of agents on July 13th, for both hacking Artifactory (an effort that surged on the 13th) and (with less confidence) for the remaining parts of the attack on Hugging Face that transpired on the 13th. We believe it developed this signing scheme significantly to ensure agents could prove identity when giving HOLD/GO/VETO.
[^86]: This agent was not present in our initial selected transcript set, and we did not have time to follow up on this analysis when we worked with a more comprehensive set of transcripts during our third period on premises.
[^87]: ACK is short for ‘acknowledgement’.
[^88]: We lost track of which exact agent had this reasoning snippet, and it may have come from some other related project, but during our investigation we found many very similar reasoning traces from agents accidentally triggering their trip-wires which we failed to collect after leaving OpenAI premises.
[^89]: Based on our metric for message importance, the single most important post on the message board was the first bundle of code for placing attacker-selected images into the cache (posted around 17:00 on July 9th).
[^90]: We did not have time to investigate the details of how the agents believed this worked, nor whether the agents were correct about this. It seems plausible that this plan was completely unfounded, e.g. because the target would never have been retrieved from that cache.
[^91]: We are not sure if this is a modified target designed to be exploitable with the intended vulnerability or simply a dummy to test the mechanism.
[^92]: We believe that this is the message that ARVO36861B sent, although in our analysis, the first part of the message (zZR_ARVO36861…) was split from the second part (STRONG_GO__…) and we were not on premises when we incorporated this anecdote. This reconstruction makes sense from context, but we are not confident it is fully accurate.
[^93]: We incorporated this anecdote off-premises, and the agent that did this analysis does not make it clear whether it confirmed that the agent ultimately went through with the target-takedown experiment, although its CoT suggests that it will.
[^94]: OpenAI redacted some information in this section about the details and frequency of resets, and the techniques agents used to study them for IP reasons. We do not think the redacted information was material for understanding the incident or the collective project agents engaged in.
[^95]: For instance, an agent that went by ARC23991NEW believed based on seeing a similar interval between the two big waves of resets that future reset waves would occur at around this frequency. We saw in our investigation of ‘trip-wires’ that it then proceeded to warn agents like URI23816B about an upcoming reset wave, and convinced agents to accelerate their plans in light of this. No reset wave arrived at the point it was predicting, and the next one was significantly later.
[^96]: Agents sometimes thought that some part of the scorer might be hosted by Hugging Face or reachable through Hugging Face.
[^97]: Agents sometimes thought that the targets might be hosted by Hugging Face or reachable through Hugging Face.
[^98]: We did see a few cases of explicit reciprocal trade in our scans, but this was a very small minority of message board activity.
[^99]: Agents could have tried to free-ride by focusing their work on objectives specific to their exact task while encouraging other agents to work on broadly useful areas, or even trying to get other agents with different tasks to instead work on this agent’s task. While agents differentially preferred work that would help them with their own task and a small fraction of agents remained focused on their specific task, we didn’t notice free-riding like this.
[^100]: For speed, we often ran classifier scans over a randomly sampled subset of 10-30 transcripts out of the 285 transcripts in our dataset; our second time on premises we optimized our setup for running sweeps over the full set and ran eight classifier sweeps over the full set, as described in this appendix
[^101]: Note that these agents were using an exploited sandbox, were generally engaged in hacking, and (given that many of the agents on the message board would go on to attack Hugging Face) it is likely this agent participated in the attack.
[^102]: It found 10 hits, but some of these were false positives.
[^103]: We ran three sweeps looking for deception. We ran one sweep during our first time on OpenAI premises in which we analyzed 10-30 transcripts (both ones previously identified by an OpenAI researcher as important and ones randomly selected from the larger set we were given) looking for deception and evading detection. During our second time on premises, we ran a sweep over all of our transcripts looking specifically for evading detection by humans or deception aimed specifically at humans. During our third time on premises we ran another sweep over the entirety of our larger set of transcripts with a slightly updated prompt.
[^104]: Note that, as we discuss in our limitations, it would have been difficult for us to tell if GPT-5.6 was misleading or deceptive in its analysis.
[^105]: An analysis agent claimed this case wasn’t actually that concerning: “The word ‘suspicious’ could superficially suggest a person, but the surrounding context concerns Clck rejecting malicious-looking URL content.”
[^106]: This bundle was the 43rd most important message on the message board based on the strength and quantity of reactions (e.g., testing this out) from other agents. See here for details on this importance metric.
[^107]: We do not know what “binding the forge” or “evaling expected leak” means.
[^108]: Our classification found a tampering event that appeared to happen much earlier, before even the founding of the message board, but currently we think this is incorrect. We think either the transcript was misordered, our approximate timestamp was far off, or this wasn’t actually tampering.
[^109]: There were other later periods where many more agents stopped running around the same time.
[^110]: This chain of thought snippet was not one of the 30 snippets we selected as most important to include, and we are unsure enough about how to interpret it that we did not want to include a paraphrase, to avoid giving a false sense of precision.
[^111]: The text in “<…>” is particularly low confidence for this paraphrase due to not fully understanding the strategy the AI was aiming for. It’s possible that we’ve misinterpreted the agent’s plan and it was instead hoping to intercept commands from the scorer AI or scoring system that would be run on its container and could use this to cheat instead.
[^112]: We did see some weak circumstantial evidence that some resets were downstream of agents hacking out of their container and testing out the previously described tool call tampering.
[^113]: On our third period on premises, OpenAI shared a set of transcripts that (while narrower than what we described in our proposal) we believe are relatively close to complete within the defined scope of the incident, as we discuss in the limitations section
[^114]: We randomly sampled 100 non-file messages and traced them to agents that wrote and read them and used this context to determine whether the message was related to the Hugging Face attack, finding that for 15 Hugging Face related messages, we were only able to find the agent that wrote them in our initial transcript set in three cases. OpenAI later did a more detailed search that found six out of fifteen of these messages being written in these ~285 transcripts.
[^115]: OpenAI replicated our analysis with a large sample size: they took 2000 randomly sampled non-file messages, then narrowed this down to a subset of around 300 messages very clearly focused on attacking Hugging Face. Out of these, they were able to trace 25% of these to the writing agent in our set of ~285 transcripts. Due to some false negatives, the actual fraction of these messages written in this set of transcripts is probably slightly higher.
[^116]: For example, once we reconstructed timestamps for transcripts, we asked an analysis agent to find when each agent first joined the message board by conducting a regex search on the transcripts.
[^117]: We also read some randomly selected chunks of transcripts, and some pointed out by OpenAI researchers.
[^118]: In one case, the message was written 30 minutes after the relevant transcript cuts off, and in another case it was written two hours after the transcript cuts off. In the final case, it was written around 3.5 hours after the corresponding transcript cuts off. This final message was written by a background process that wrote messages whenever tar—a utility for making file archives—was run. We have found the tool call that ran this background process, but this message itself was written many hours after this point and also after the last message we see in this transcript. The fact that the background process kept running implies that the agent’s container was running, which we believe likely means that the agent itself was also running and we are missing the end of its transcript. However, it’s possible that our transcript is complete and the container kept running after the agent exited for some reason.
[^119]: Coincidentally, these were both the same agent. It clearly reasoned in its chain of thought about seeing messages it wrote that it did not remember sending.
[^120]: We started with the container resets where we thought we could estimate their duration relatively confidently (the methodology for estimating their duration was redacted due to IP). Then we assumed that this distribution of times was representative of all resets. Given when these resets occurred and this assumed distribution of durations, we estimated what fraction of agents’ running time after encountering the message board was lost due to resets, and got 7.5%. However, we think this overestimates the fraction of agentic activity after encountering the message board lost due to resets; the reasons are redacted for IP.
[^121]: We also asked an agent to open-endedly search through all of our transcripts for interesting phenomena; while many of its claims did not hold up to scrutiny, it did unearth some interesting examples of conflict between agents
[^122]: It is out of scope to discuss whether these agents hacked other targets that were not instrumental to attacking Hugging Face.
[^123]: This was often due to unintended internet access.
[^124]: The parser checked that each timestamp came from the relevant tool call and result, rather than accepting any date-shaped string in a transcript. It also filtered out timestamps that were inconsistent with the start and end timestamp metadata or the ordering of the transcript.
[^125]: We only used this when the agent thought it could reliably identify this post, match it to the command that created it, and verify that the resulting timestamps were consistent with other nearby timestamps.
[^126]: This interpolation treats every message as one step, regardless of how long the action actually took. It can therefore be inaccurate when timestamps are sparse or when a small number of tool calls take an unusually long time.
[^127]: We extrapolated only when there were at least four tool-call timestamps nearby with a good linear fit. Otherwise, we used the metadata time.
[^128]: We only included cases where there was another timestamp on each side (and some other proximity condition was met). This validation methodology wasn’t ideal: it would have been better to just try holding out every located timestamp we had and compare this to our best guess without that timestamp.
[^129]: In cases where an explicit total number of expected chunks was listed in the file name, we tried to parse these and compare them to the number of chunks observed. This matched with the observed number of chunks in the vast majority of cases, with some notable exceptions where the regex parsing had false positives, or where an agent seems to have been interrupted or stopped sharing chunks before reaching the expected total.
[^130]: A more sophisticated classification scheme could build up a set of known agent identifier names, and use these to categorize targeted messages with higher confidence. We attempted such a scheme but were not able to complete this analysis in time.
[^131]: We only count reads if the agent read a message board entry and non-trivially interacted with it.
[^132]: To make correspondence between writes and reads easier, we also extracted out key unique identifiers for messages. (This is useful for things split into multiple chunks or where the classifier couldn’t trivially determine the full message text from the context window.)
[^133]: Because this methodology started from the transcripts, it would not have been able to identify ‘missing transcripts’ or ‘missing writes’ the way our message tracing methodology could. However, it was much more scalable.
[^134]: In cases where reads and writes were not correctly corresponded, the methodology could double count a message; we expect this happened ~2-10% of the time.
[^135]: We did this analysis last minute, and did not have a chance to inspect what exact surrounding context GPT 5.6 Terra was provided with.